DeepSeek mHC: Manifold-Constrained Hyper-Connections

Modern deep learning rests on the residual connection. This post is for engineers who know the Transformer block and want to know what mHC changes in the residual path, why, what it costs, and when to try it. Hyper-Connections (HC) explore another architectural dimension: widen the residual state into several interacting streams. DeepSeek’s Manifold-Constrained Hyper-Connections (mHC) paper studies how to keep that routing stable at larger training scales.
The post starts with standard residual connections, then adds Hyper-Connections and the instability they create. The mHC constraint, a small NumPy demo, and the implementation cost come after that.
Why residual connections work
The depth problem
Adding layers can increase capacity, but it also makes optimization and signal propagation harder. Depending on initialization, normalization, and architecture, forward activations or backward gradients can shrink, grow, or become poorly conditioned across depth.
The residual solution
The ResNet paper introduced a simple fix. Instead of learning a direct mapping, learn the residual, the difference from identity:
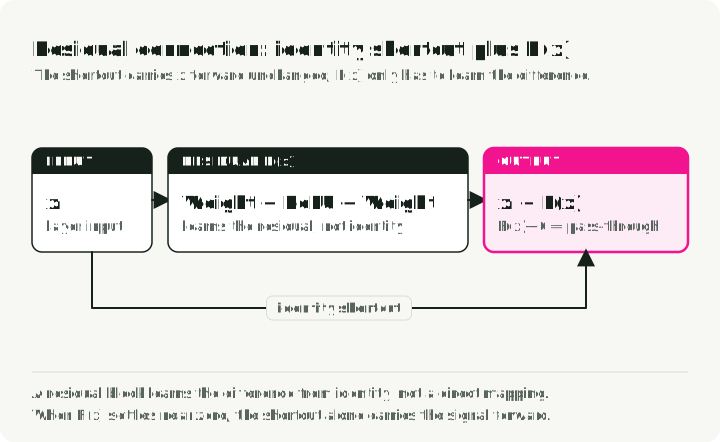
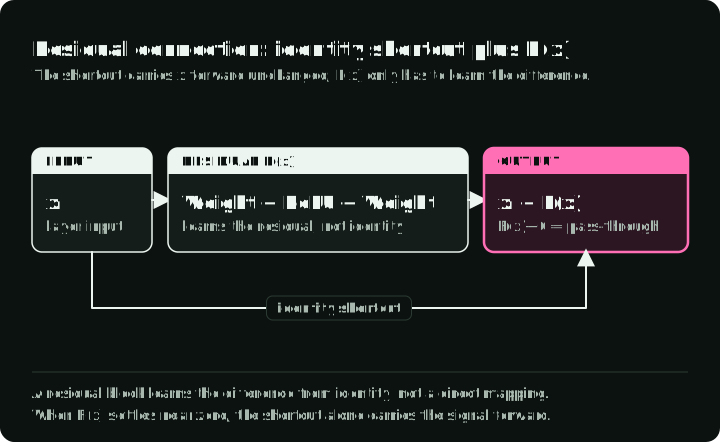
The useful property is the identity shortcut. When the residual function outputs zero, the layer becomes a pass-through. Two consequences follow:
- A direct gradient term: backpropagation includes a path through the identity component.
- A simple fallback mapping: the residual branch can stay near zero when a layer does not need to change the state much.
This does not eliminate every optimization problem, but it made substantially deeper networks practical.
How layer normalization changes the residual path
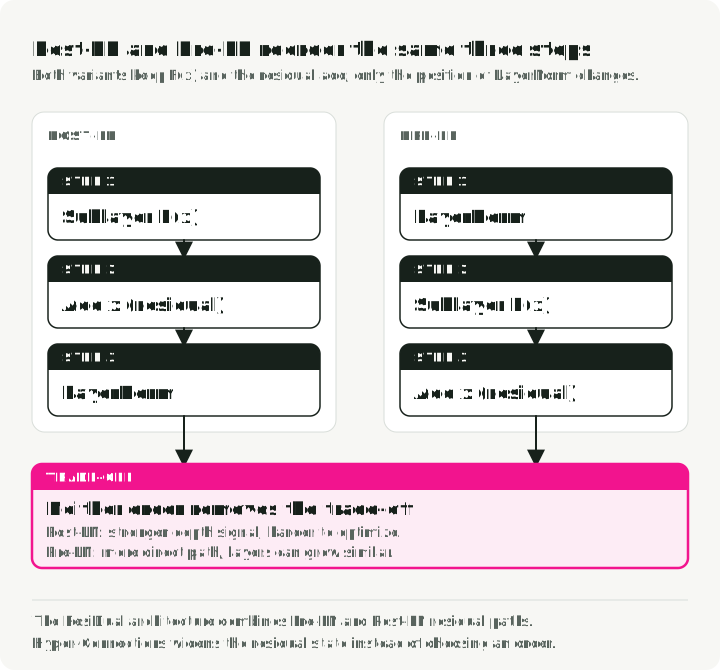
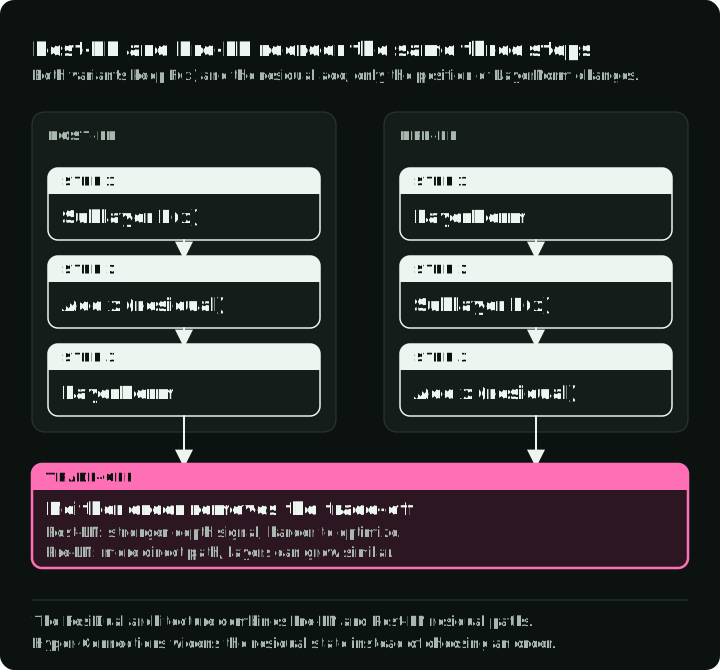
Transformers added a new variable: where to put Layer Normalization (LN). It changes whether the residual path stays an identity.
| Variant | LN Placement | Advantage | Key Limitation |
|---|---|---|---|
| Post-LN | After residual block | Strong depth contribution | Can be harder to optimize at depth |
| Pre-LN | Before residual block | More direct residual path | Adjacent-layer representations can become increasingly similar |
ResiDual combines a Post-LN-like residual path with a second path that accumulates block outputs. Their representations are added at the model output. The HC paper starts from this same trade-off and makes the connection strengths learnable, across several streams.
Hyper-Connections add parallel residual streams
Hyper-Connections (HC) expands the residual stream’s width rather than adding depth.
What a stream means
In a standard Transformer, each token has a -dimensional state that passes through the blocks. At the start of the network, HC replicates that input embedding times, where is the “expansion rate”, typically 4. The -dimensional hidden state becomes an “hyper hidden matrix”.
In Hyper-Connections, a stream is one of those parallel instantiations of the state.
The copies begin identically, then diverge as learned maps read from, write to, and mix the streams. The paper interprets them as multiple connection patterns across depth; it does not require each stream to acquire a fixed human-readable role.
Core mechanisms
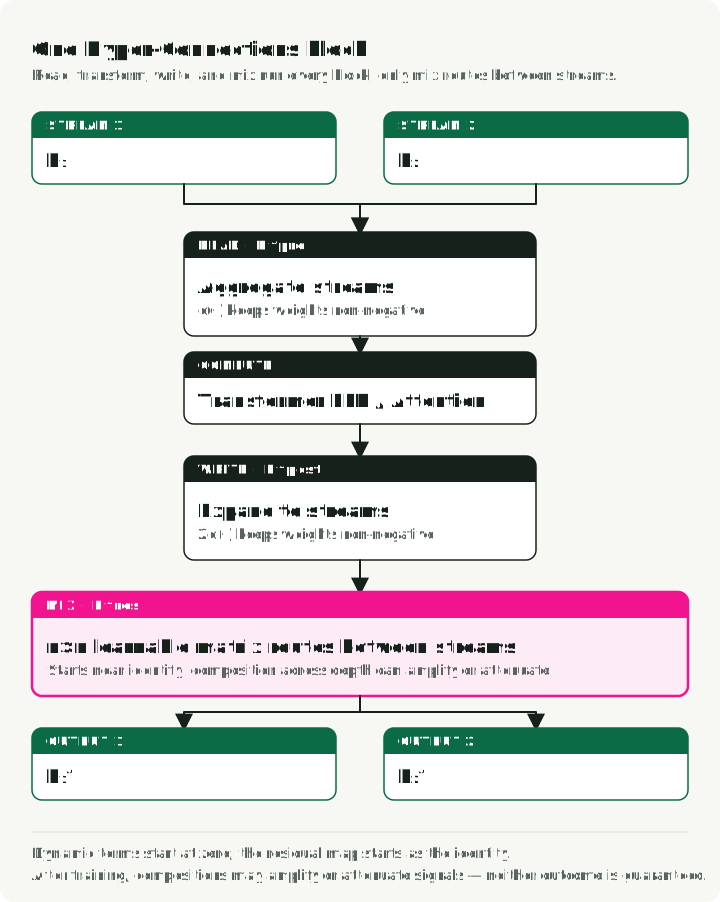
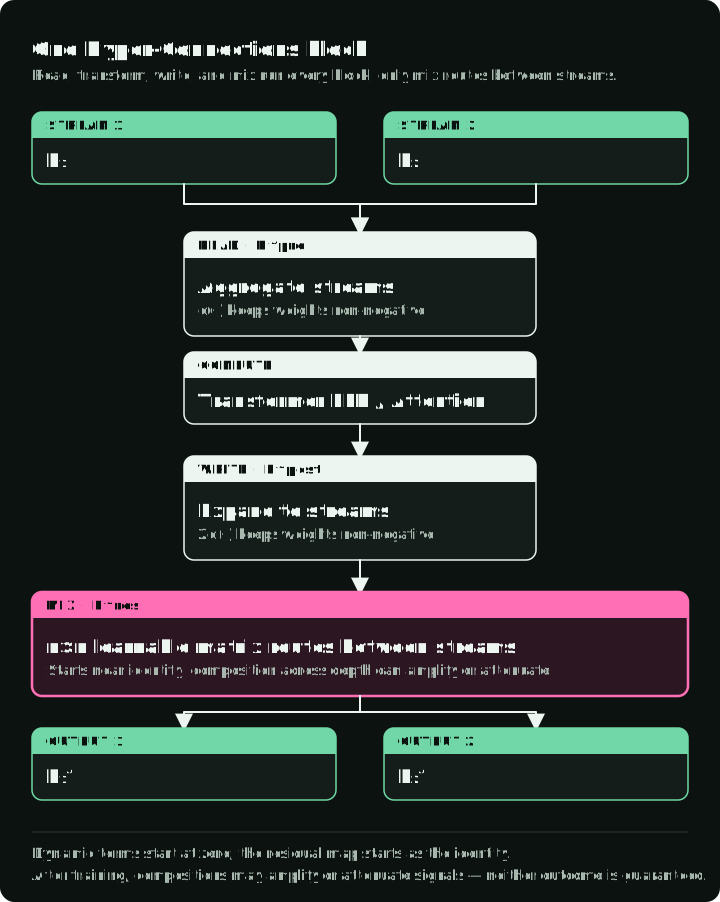
Instead of one residual pathway, HC keeps parallel streams flowing through the entire network. At each transformer block, three operations run, each controlled by small learnable weights:
- Read (): aggregate the streams into the -dimensional input consumed by the attention or feed-forward block.
- Write (): map that block’s output back into updates for the streams.
- Mix (): apply an residual map to the incoming streams before adding the block update.
In HC, each map is a learned static part (a bias) plus an input-dependent term passed through , so its entries can take any sign. The HC paper calls the version with input-dependent terms dynamic HC (DHC); DHC×4 means DHC with four streams. The residual map is the stability-critical part because it is multiplied repeatedly across depth.
Together, the three maps give the per-layer update (Eq. 3 of the mHC paper, which writes the width as ):
Here is the stream matrix, and are , and is . The first term is the residual path. The second term is the block’s update: read, compute, write. With and all three maps equal to 1, the equation is the standard residual .
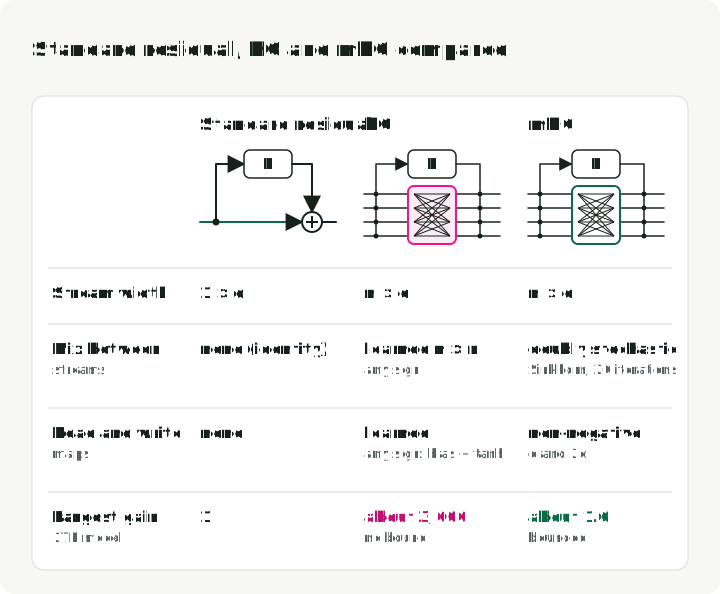
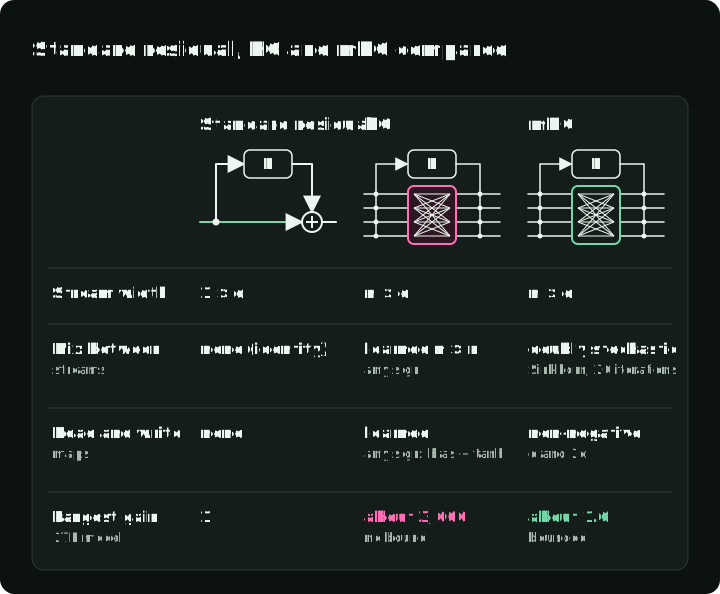
The figure draws this update for four streams: read, compute, and write above the streams, the 4 × 4 mix on the streams, and an add on each stream.
What the HC paper reports
The HC paper reports 1.8× faster convergence for its OLMoE-1B-7B DHC×4 configuration relative to its baseline, plus downstream gains at 500B tokens (Section 1). That is one evaluated configuration, not a general speed multiplier for four streams.
Why unconstrained HC can become unstable
The mHC paper reports instability when it scales unconstrained HC to its 27B setup: the training loss surges around step 12k, together with a jump in the gradient norm (Section 3.1). The same unconstrained maps that make HC flexible also remove the guaranteed identity path that makes residuals easy to train.
The composite-map problem
In standard residuals:
When , this is identity: . Signal passes through unchanged.
In Hyper-Connections, the residual term of the update above is a matrix product, . Following only that path over layers, the signal becomes:
The behavior depends on the composite matrix, not on whether individual entries sit above or below 1. If the maps keep stretching the same direction by more than 1, the product grows exponentially with depth. If they keep shrinking it, the signal fades. Negative entries can also cancel signals.
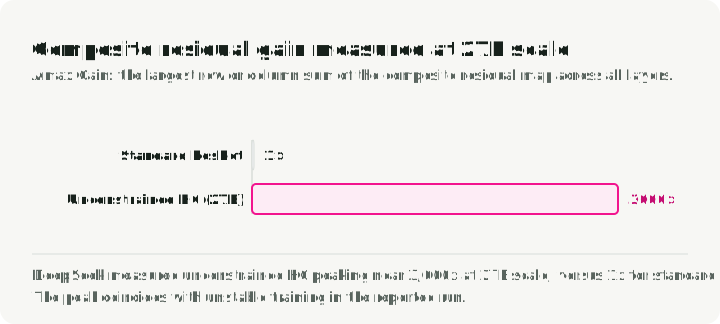
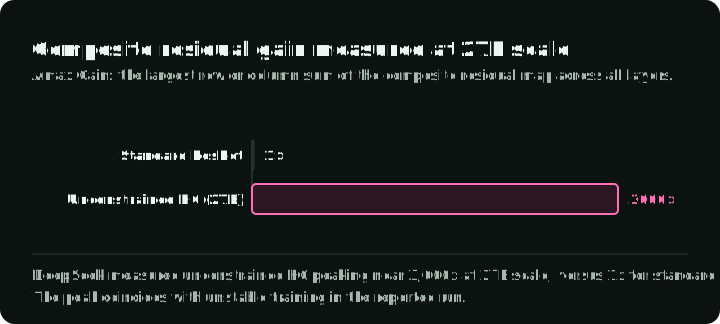
The mHC paper measures that gain with Amax Gain Magnitude: the maximum absolute row sum for forward propagation and column sum for backward propagation in a composite residual map. In its 27B HC experiment, the peak approaches 3,000 and coincides with unstable training behavior (Section 3.1).
The chart puts the paper’s three values on one log axis: 1 for a standard residual, about 1.6 for mHC (the constrained version described next), and about 3,000 for unconstrained HC. A mark under the axis shows the from the example above.
The design goal is therefore narrower than forcing every map to be the identity: allow inter-stream mixing while bounding amplification across compositions.
The mHC constraint
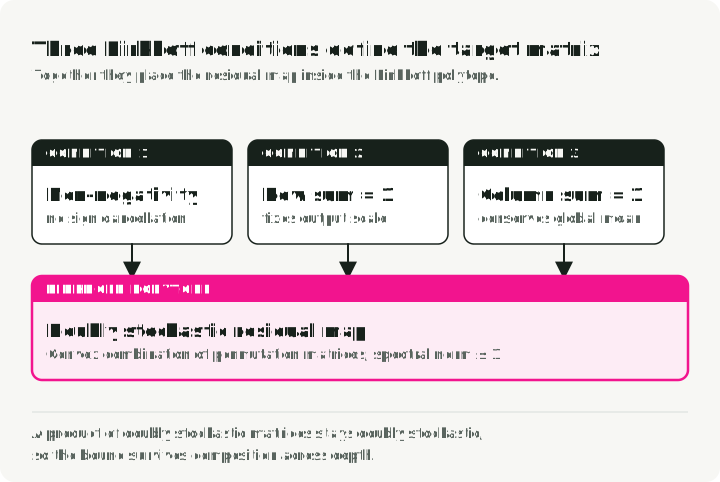
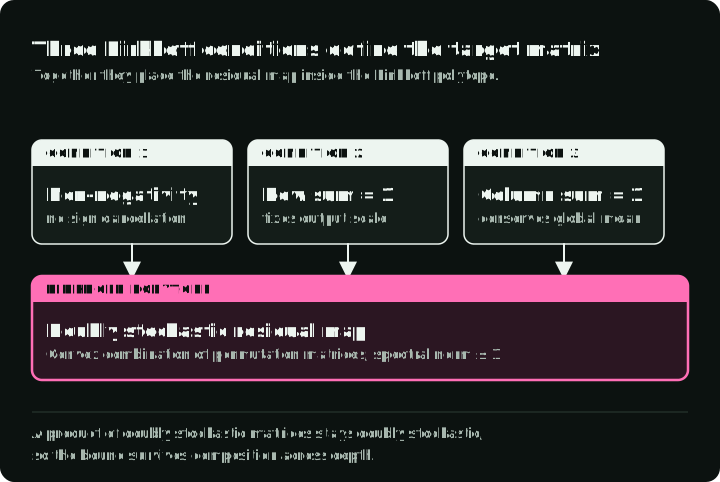
mHC keeps inter-stream routing but constrains each residual mixing matrix to the Birkhoff polytope, the set of doubly stochastic matrices. Such a matrix has non-negative entries, and each of its rows and columns sums to one.
The figure sketches the residual path of each design this article covers and compares them. The gain row shows the peak composite gain the mHC paper reports for its 27B model. With and all maps equal to 1, HC and mHC reduce to the standard residual.
What double stochasticity guarantees
The figure checks the three conditions on two 3×3 matrices from the Sinkhorn example below: the unconstrained logits , which break all three, and after 20 Sinkhorn passes, which meets all three. The table gives the consequence of each condition.
| Constraint | Consequence |
|---|---|
| Non-negativity | Coefficients do not cancel through opposite signs |
| Row sum = 1 | A constant signal across streams remains constant |
| Column sum = 1 | The global mean across streams is conserved |
Non-negativity together with unit row sums makes each output a convex combination of the input streams. The constraint conserves the mean across streams, not the vector’s length: a doubly stochastic map can average streams toward each other.
Three more properties follow (Section 4.1):
- Spectral norm ≤ 1: the spectral norm is the largest factor by which a matrix can stretch any vector. A bound of one means the residual routing map cannot amplify the Euclidean norm.
- Closed under multiplication: a product of doubly stochastic matrices remains doubly stochastic, so the constraint survives composition across depth.
- Convex mixing: by the Birkhoff-von Neumann theorem, the map lies in the convex hull of permutation matrices.
Sinkhorn-Knopp projection
The learnable residual logits are unconstrained. mHC first exponentiates them to obtain a positive matrix, then alternates column and row normalization. With enough iterations, this Sinkhorn-Knopp process approaches a doubly stochastic matrix; the paper uses 20 iterations as a practical, approximate differentiable projection rather than an exact constraint.
The figure runs the first pass on the 3×3 example below one step at a time, then plots the largest column-sum error over 20 passes.
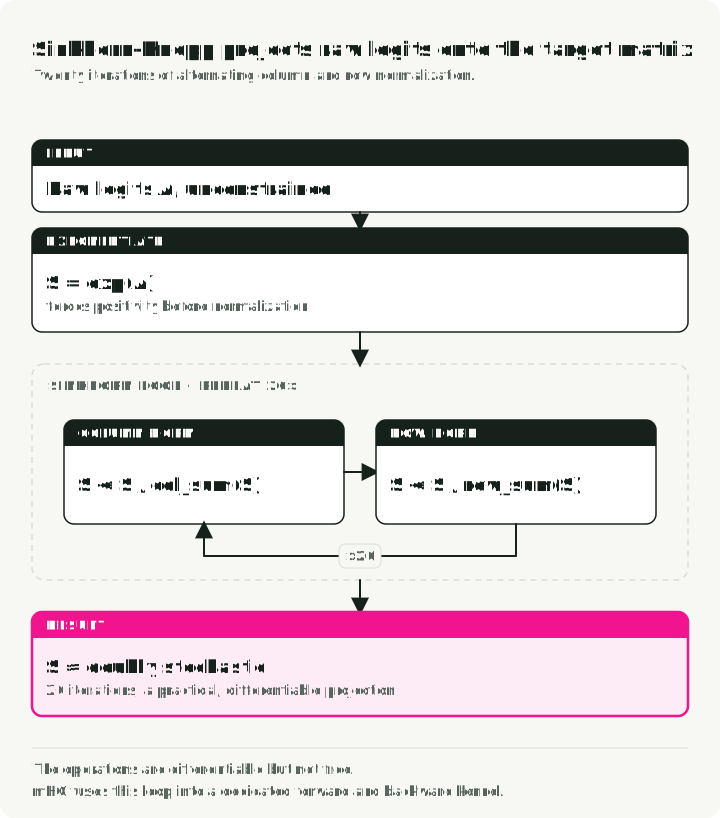
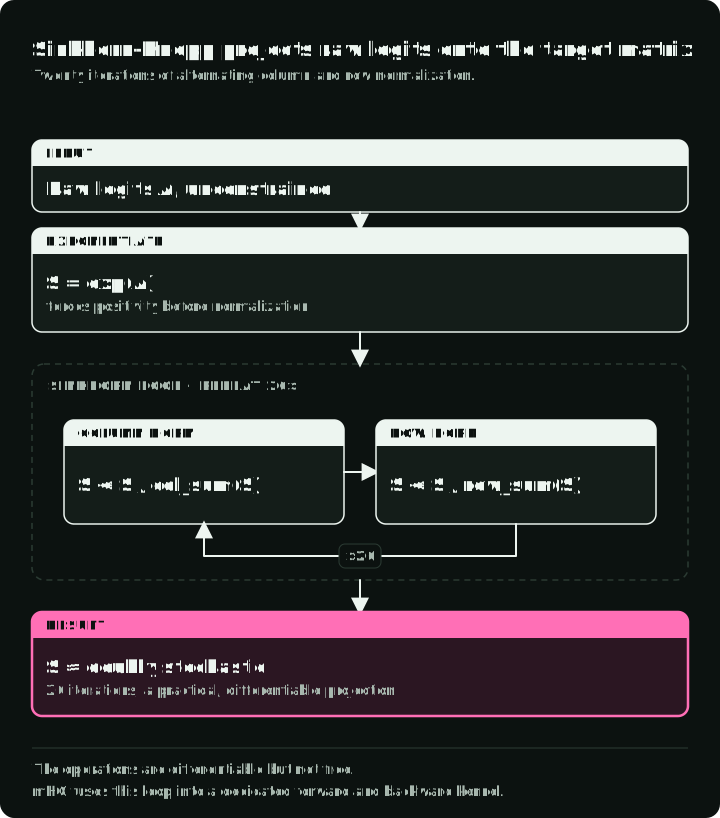
For raw logits , the procedure is:
S = exp(A)
repeat 20 times:
    S = S / column_sum(S)
    S = S / row_sum(S)
return S
A 3×3 example shows what “approximate” means. One pass fixes the row sums, because rows are normalized last, but leaves the column sums off by up to 12%. Twenty passes bring both to 1.000 at three decimals.
Raw logits A           [[-0.5,   2.1,   0.8  ],
                        [ 1.3,  -4.0,   1.9  ],
                        [ 0.1,   0.6,  -0.2  ]]

S = exp(A)             [[ 0.607, 8.166, 2.226],
                        [ 3.669, 0.018, 6.686],
                        [ 1.105, 1.822, 0.819]]

After 1 pass           [[ 0.097, 0.705, 0.198],
(columns, then rows)    [ 0.497, 0.001, 0.501],
                        [ 0.435, 0.386, 0.178]]
                       row sums     1.000 1.000 1.000
                       column sums  1.030 1.092 0.877

After 20 passes        [[ 0.102, 0.653, 0.244],
                        [ 0.457, 0.001, 0.542],
                        [ 0.441, 0.346, 0.213]]
                       row and column sums 1.000
The next script tests the claim behind the whole method. It multiplies 60 random 4×4 mixing matrices, once used directly as HC would use them and once after Sinkhorn as mHC does, and prints the Amax gain of each product.
import numpy as np

rng = np.random.default_rng(0)
n, layers = 4, 60

def sinkhorn(logits, iters=20):
    s = np.exp(logits)
    for _ in range(iters):
        s = s / s.sum(axis=0, keepdims=True)  # columns sum to 1
        s = s / s.sum(axis=1, keepdims=True)  # rows sum to 1
    return s

def amax_gain(m):
    return max(np.abs(m).sum(axis=1).max(), np.abs(m).sum(axis=0).max())

hc, mhc = np.eye(n), np.eye(n)
for _ in range(layers):
    a = np.eye(n) + 0.3 * rng.standard_normal((n, n))
    hc = a @ hc
    mhc = sinkhorn(a) @ mhc

print(f"HC  Amax gain: {amax_gain(hc):.1f}")
print(f"mHC Amax gain: {amax_gain(mhc):.1f}")
With seed 0 it prints 1906.8 for HC and 1.0 for mHC. Each random matrix is close to the identity, so none of them looks large on its own. The paper measures about 1.6 for mHC in its 27B model, not 1.0. It uses only 20 iterations, so the trained matrices are not exactly doubly stochastic, and the small errors grow across layers but stay bounded (Section 5.4).
The Sinkhorn iterations are differentiable, but they are not free. mHC relies on a fused forward kernel and a custom backward kernel that recomputes the intermediate normalization states on chip.
Parameterization details
- Residual map: exponentiation plus Sinkhorn normalization produces the approximately doubly stochastic .
- Read and write maps: mHC replaces HC’s with a sigmoid: and . Both maps are non-negative, which removes cancellation between positive and negative coefficients (Sections 4.1 and 4.2). Read weights fall in (0, 1) and write weights in (0, 2). A zero logit gives a write weight of , the weight a standard residual add uses. The paper does not state its reason for the factor 2.
Complete mHC architecture
The figure shows one mHC layer with each map’s parameterization. It has the same two paths as the HC block; what changes is how each map is parameterized.
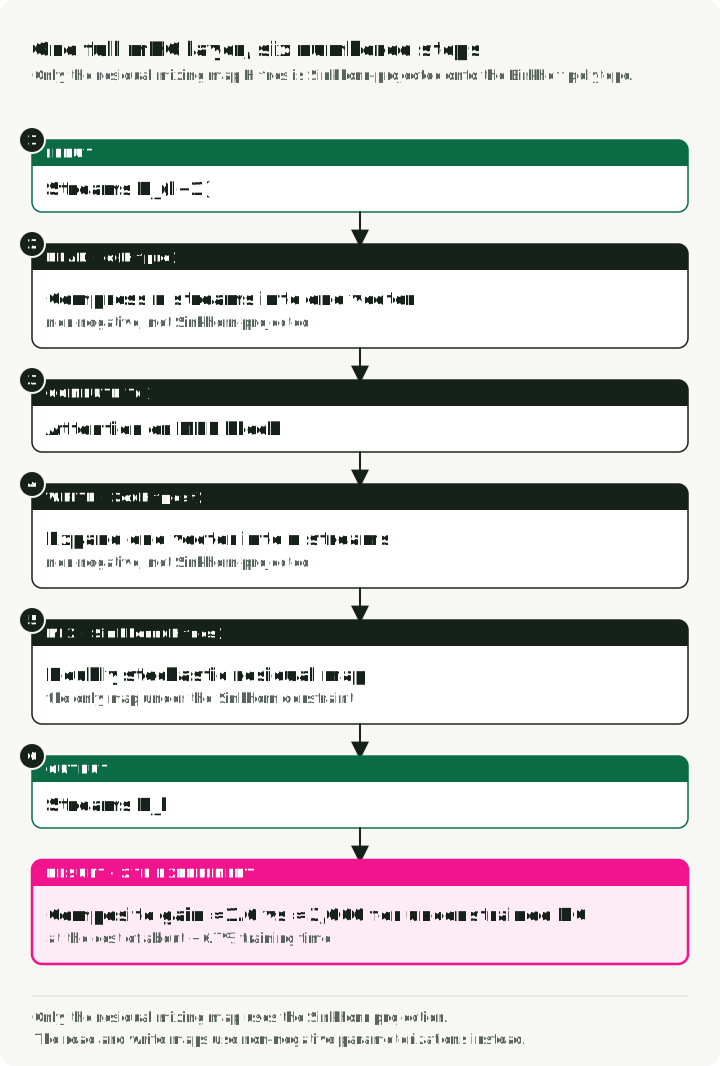
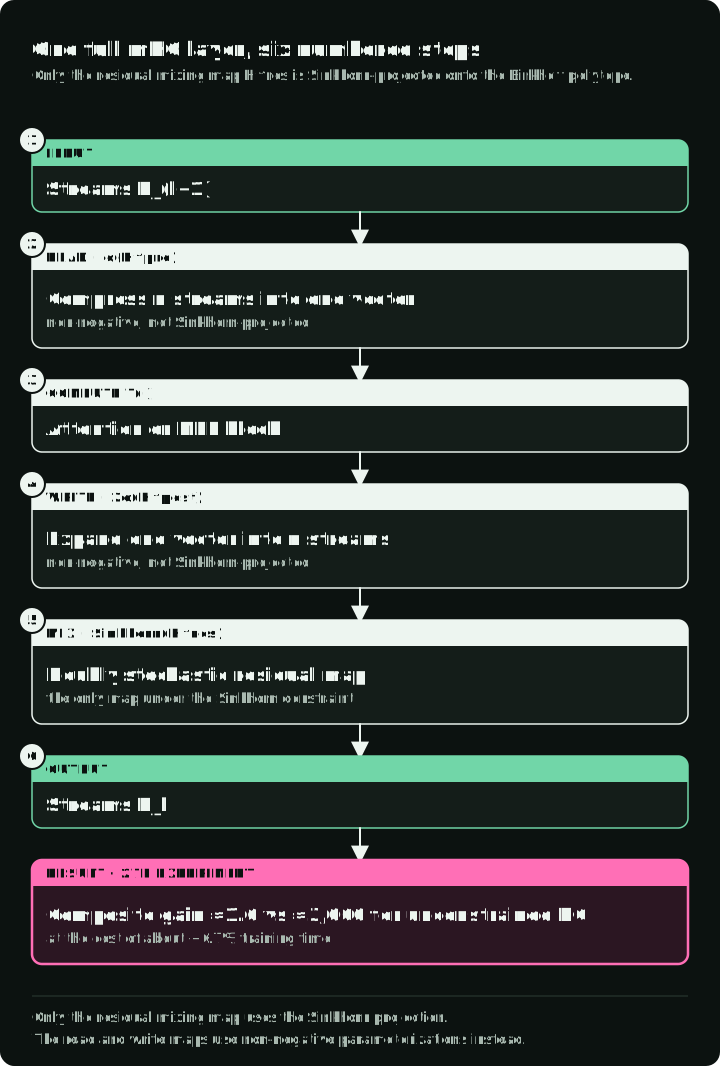
In terms of the update equation:
- Input: parallel residual streams enter the layer.
- Block path: the read map combines the streams into one -dimensional input. The attention or MLP block processes it. The write map turns the output into updates for the streams.
- Residual path: the approximately doubly stochastic mixes the incoming streams.
- Add: the two paths are summed into , which moves to the next layer.
Only the residual mixing map uses the Sinkhorn projection. The read and write maps use non-negative parameterizations. That distinction matters because the paper’s composition guarantee applies to .
Infrastructure required for the reported overhead
Four streams increase residual-state memory access, activation storage, and pipeline communication. The paper’s timing result depends on three co-designed changes, described below.
Kernel fusion
The implementation fuses operations that share memory access, uses mixed precision where appropriate, and implements most custom kernels with TileLang. The Sinkhorn loop and its custom backward pass run inside dedicated kernels to reduce memory traffic and launch overhead.
Selective recomputation
The streams add activation memory (Section 4.3.2). Instead of storing every intermediate result, mHC:
- Frees the intermediate activations of its own kernels after the forward pass.
- Recomputes them in the backward pass, without re-running the attention or FFN block.
- Stores the expanded-stream input of each group of consecutive layers and every layer’s attention or FFN output. The paper aligns these groups with pipeline stages.
An extended DualPipe schedule overlaps parts of communication, recomputation, and layer work at pipeline boundaries. The achieved overlap is specific to this training system.
Reported system result
For the paper’s large-scale setup, expansion rate adds 6.7% training time relative to its baseline (Section 4.3). This is a system result, not the overhead of a plain framework implementation.
What the experiments establish
The authors train 3B, 9B, and 27B DeepSeek-V3-inspired MoE variants (Section 5.3). At 27B, mHC beats the standard residual baseline on all eight reported downstream benchmarks, and beats HC on seven of eight (Table 4). HC is slightly higher on MATH (26.4 against 26.0). These are in-house pretraining experiments from the proposing team, so independent replication and comparisons on other architectures remain open.
When to try mHC
The paper’s results point to three conditions:
- You pretrain from scratch. mHC changes the architecture, and the paper evaluates it only in pretraining. If not, skip mHC.
- You need more residual width than one stream. You already use HC or plan to, and you see loss spikes or growing activations and gradient norms as you scale depth or size. If one stream is enough, keep the standard residual.
- You can do the systems work, or accept a larger cost. The 6.7% figure needs fused kernels and pipeline schedule changes. A plain framework implementation will cost more. If you cannot do that work, a plain-code mHC is possible, but measure the overhead first.
Three questions remain:
- System overhead: the reported overhead is the optimized paper result; another runtime, device topology, or model shape may see a different cost.
- Mixing bias: double stochasticity preserves the cross-stream mean and prevents expansion through , but it can smooth differences between streams. The block update still changes the overall representation.
- Evidence scope: the strongest evidence is language-model pretraining on DeepSeek-V3-inspired MoE architectures. Generalization to other model families is not yet established by this paper.
mHC is a promising way to study wider residual topology while keeping the repeated residual map well conditioned. Whether it is worthwhile for another model depends on independent quality gains and the cost of reproducing its systems stack.
References
- mHC: Manifold-Constrained Hyper-Connections - Xie et al. (DeepSeek)
- Deep Residual Learning for Image Recognition - He et al. (ResNet)
- Hyper-Connections - Original HC paper
- TileLang - CUDA kernel optimization framework
- DualPipe - Pipeline parallelism scheduler for DeepSeek-V3
- ResiDual - Dual residual path architecture