NER Guide 2026: GLiNER, spaCy, Transformers, and LLMs

This guide is for engineers choosing named entity recognition (NER) for retrieval, privacy, or document-processing pipelines. It explains how to choose between span recognizers and structured LLM extraction, evaluate their errors, and test deployment options against the latency and cost your workload permits.
NER turns text into labeled pieces that a program can use. Given “Bill Gates founded Microsoft on April 4, 1975,” it can return the contiguous text spans Bill Gates, Microsoft, and April 4, 1975 with the types person, organization, and date. In a span-based encoder such as GLiNER, the model reads the text once and scores candidate spans against the labels you supply.
For a retrieval or privacy pipeline, I would first ask whether the output must be a literal mention. That decision separates a span recognizer from systems that also normalize values, link records, or infer facts. LLMs remain useful for proposing training annotations and handling cases that require inference or normalization.
Companion repo: ner-field-guide provides exact span scoring, GLiNER examples, reviewed annotation conversion, ONNX FP32 and INT8 checks, and a streaming PII demo.
For the short model comparison, see Best NER Models in 2026.
What is named entity recognition?
Named entity recognition finds spans in text and assigns types such as person, organization, date, product, or domain-specific labels. A span is a contiguous piece of the original text. NER identifies the mention; entity linking is the separate step that resolves it to a canonical record or ontology concept.
| Workload | First model to test | Escalate when |
|---|---|---|
| IDs or controlled dictionaries | Rules or spaCy EntityRuler | Recall outside known patterns matters. |
| Stable labels and ample training data | spaCy or a fine-tuned encoder | The label set changes or recall stalls on rare types. |
| Changing labels; small type inventory | GLiNER cross-encoder | The inventory grows or labels are reused across many documents. |
| Large, reusable type inventory | GLiNER bi-encoder | The domain set shows a quality or calibration regression. |
| Several extraction tasks in one text pipeline | GLiNER2.5 | Joint-task quality misses the per-task target. |
| Implicit facts or schema reasoning | Structured LLM extraction | Latency, cost, or unsupported claims exceed the product budget. |
A GLiNER cross-encoder reads the label names and the text together, so every document re-encodes every label. A bi-encoder encodes labels separately and can cache them. GLiNER2.5 is a separate model family that extracts entities, classes, relations, and structured fields from one schema. Each gets its own section below.
The first match wins when you go down this list, in the order I would ask the questions:
- The output is not a literal span: use structured LLM output.
- IDs or a fixed dictionary: use rules or an EntityRuler.
- Fixed labels and enough training data: use spaCy or BERT-NER.
- A large label set reused across documents: use the GLiNER bi-encoder.
- Otherwise: use the GLiNER cross-encoder, and try GLiNER2.5 when you need several tasks in one pass.
Where modern systems use NER
NER still finds spans of text and assigns labels to them. What changed is its position in the system. It now supplies filters for RAG, structured arguments for agent tools, and fields for document-processing pipelines. Those uses make latency, cost, and schema flexibility as important as benchmark accuracy.
RAG: better retrieval through entity extraction
Similarity search alone struggles when a question contains exact entities. For “what did Anthropic say about model safety in Q4 2024?”, entity extraction can propose “Anthropic” and “Q4 2024” as filters. Apply a hard filter only when the indexed metadata and date semantics support it; otherwise use it as a ranking signal or retain an unfiltered retrieval path. A missed alias or an incorrectly inferred date range can exclude the answer.
During indexing, you extract entities from each chunk and store them as metadata: {"organizations": ["Anthropic"], "dates": ["Q4 2024"], ...}. This lets you filter by entity before running vector search. Knowledge graph RAG (GraphRAG, LlamaIndex property graphs) adds named relationships that retrieval can follow across several hops.
The diagram works through an example index of four chunks. Compare the two panels at the bottom: the hard filter never searches the chunk whose stored date has no year, while the ranking boost still searches it.
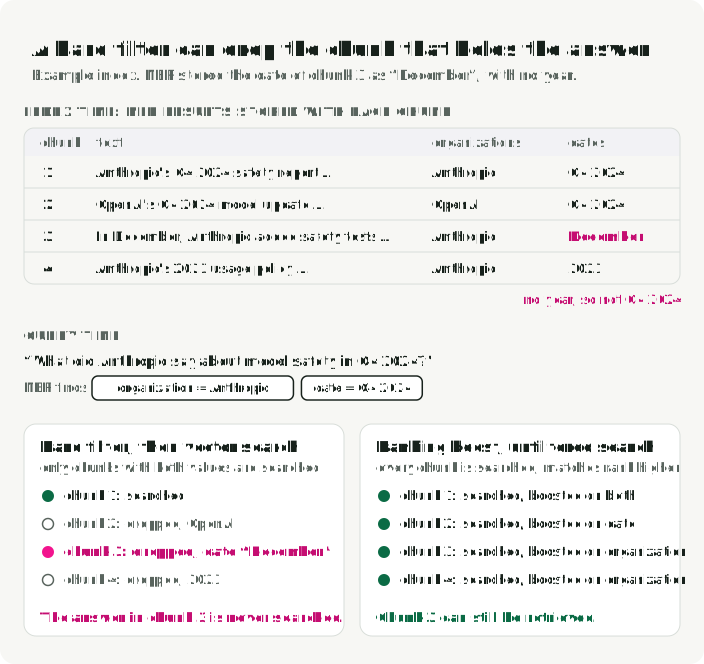
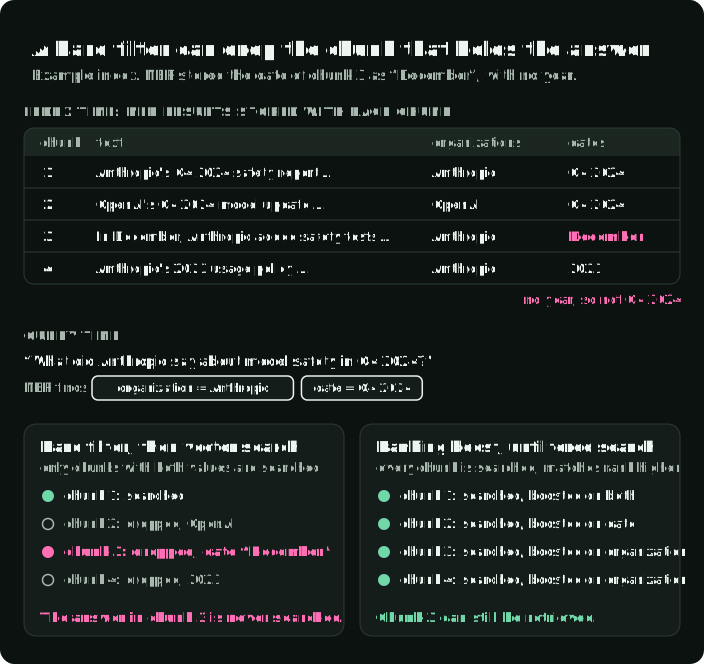
At query time, entities extracted from the user’s question drive routing. A question mentioning a company name goes to a finance index; one mentioning drug names goes to a clinical knowledge base. GLiNER is useful when the query-time schema or entity types change. Unseen company or drug names alone do not require open-vocabulary labels; a closed-label model can still recognize new mentions of known types.
AI agents: turning text into structured facts
Agents receive unstructured text such as web pages, API responses, and user messages. NER converts that text into structured facts the agent can reason over, store, or pass to tools.
For tool routing, a request such as “schedule a meeting with Sarah Chen from Accenture on Thursday at 2pm” can yield PERSON: Sarah Chen, ORGANIZATION: Accenture, DATE: Thursday, and TIME: 2pm. A calendar resolver then combines the date and time into the API’s required timestamp. A local encoder avoids the API round trip, but its latency depends on the model, runtime, hardware, batch size, and label count.
NER also supports entity tracking across conversations. Agent memory systems need to know that “Sarah” in turn 3 and “Ms. Chen” in turn 12 are the same person. NER identifies the spans; coreference resolution decides whether the mentions refer to the same person in context. Entity linking then maps that person to a canonical record, when one exists.
The constraint in both cases is latency. If each of ten sequential steps makes a 200 ms NER call, those NER calls add 2 seconds of perceived delay. One call adds 200 ms. Encoder models usually fit entity work inside agent loops better than LLM-based extraction.
Document intelligence: from images to structured data
OCR turns images into text. NER turns that text into structured fields.
A standard pipeline first uses OCR, such as Tesseract, Azure Document Intelligence, or AWS Textract, to produce text and bounding boxes. NER then finds spans for fields such as invoice_number, vendor_name, total, and due_date. A schema or relation-extraction step must group line-item descriptions, quantities, and prices into line_items. The same sequence applies to contracts, medical records, and regulatory filings.
Each stage has its own score. An OCR error that drops a digit looks like an NER miss if you only score the final record.
| Stage | What it produces | Score |
|---|---|---|
| OCR and layout | Text, reading order, boxes | Character error rate |
| NER | invoice_number, vendor_name, total | Exact-span F1 |
| Grouping | Line items (description, quantity, price per row) | Record F1 |
| Linking and normalization | Vendor ID, ISO dates, amounts | Linking or normalization accuracy |
Modern document pipelines may combine layout understanding, entity extraction, and relation extraction. OCR or a layout-aware document model still supplies text, reading order, tables, and bounding boxes. Current GLiNER2.5 exposes entities, relations, classification, and structured records through one schema interface; score each output separately.
Cost decides most of these pipelines. Price yours at the actual monthly document volume, including retries and review. A compact encoder can run on CPU, while an API-based LLM adds per-document inference cost and latency. A practical test is to label a representative invoice set with an LLM. Fine-tune GLiNER on the reviewed records, then compare both paths on field-level F1, latency, and total cost.
PII detection and LLM guardrails
Privacy laws such as GDPR, HIPAA, and CCPA require safeguards for personal data but do not require NER. NER can find personal data for redaction or minimization; its recall must be checked on your data before it counts as a control.
De-identification models find PERSON, SSN, PHONE, EMAIL, and ADDRESS spans and either redact them or replace them with synthetic equivalents. Microsoft Presidio combines recognizers with anonymization operators, and its samples include GLiNER as a recognizer. The 0.3B-parameter GLiNER2-PII is another candidate: its paper covers 42 PII types at character-span resolution.
In John Snow Labs’ vendor-run comparison, 48 expert-annotated documents cover six PHI classes. Provider labels were remapped and unmappable predictions excluded, which limits cross-provider interpretation. The Providence report describes 281 leaked PHI events in a review of 1,000 notes containing 34,701 sentences. Events are not distinct affected sentences: count both leaked instances and affected documents in a privacy evaluation.
For LLM guardrails, NER works as a pre-screening layer: scan user input for PII before sending it to an external API, then block or anonymize.
A local detector can be faster than asking the LLM to self-moderate, but false negatives remain possible, so add another control for the PII exposure your system cannot accept. GLiNER is useful here because PII categories vary by jurisdiction. An API can accept a new label such as “genetic information” without retraining. Recall for that new label is unknown until you check it on reviewed examples.
GLiNER: span-to-label matching for open-vocabulary NER
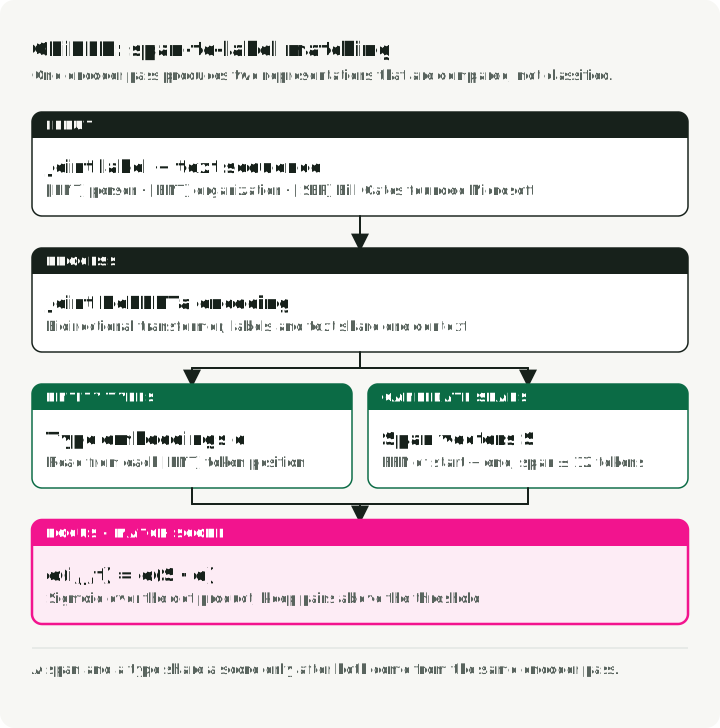
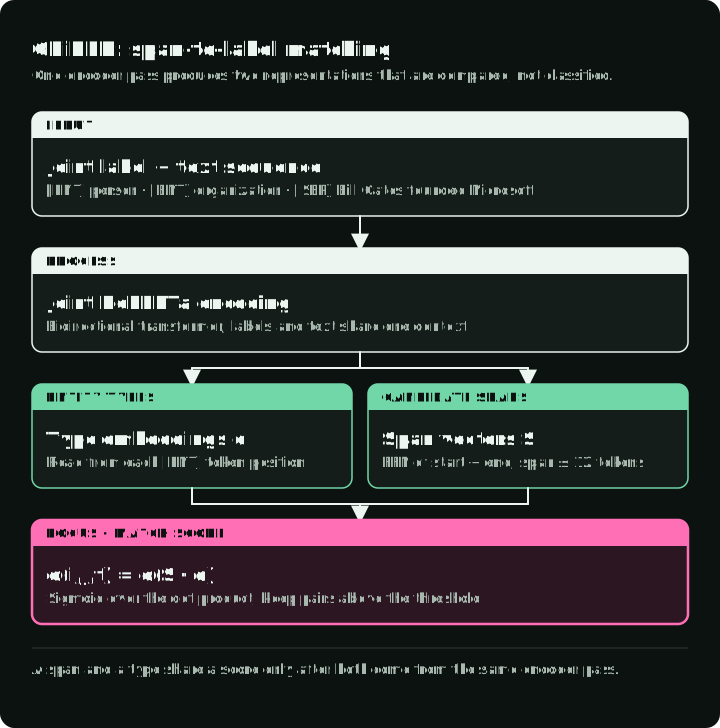
GLiNER (NAACL 2024, Zaratiana et al.) made encoder-based NER competitive with LLMs at a fraction of the cost. Instead of treating NER as sequence labeling or text generation, GLiNER treats it as a matching problem. It scores every candidate text span (each contiguous sequence of words like “Bill Gates” or “Microsoft”) against every entity type label, then keeps the high-scoring pairs.
The model takes entity type labels and input text as a single sequence: [ENT] person [ENT] organization [ENT] date [SEP] Bill Gates founded Microsoft.... A bidirectional transformer (DeBERTa-v3) encodes everything together.
From the output, the model builds two sets of representations. One refines each entity-type representation from an [ENT] token position through a small feed-forward network (FFN) that transforms the encoder’s vector. The other represents text spans by combining start and end word vectors through another FFN. A dot product between a span representation and an entity type representation gives a score.
Apply sigmoid and you get the probability that the span from word position to word position belongs to entity type : . Here is the span vector produced by the FFN and is the FFN-refined entity type embedding from the corresponding [ENT] token (Zaratiana et al., 2024, Eqs. 1–2). Candidate spans are capped at 12 words; the tokenizer may split a word into several subword tokens.
GLiNER accepts natural-language label descriptions at inference time without retraining, but extraction quality depends on label wording and domain fit. You pass in entity types such as “person,” “adverse drug reaction,” or “financial instrument,” and the model scores spans against them. The 50M, 90M, and 300M configurations below are the original paper models. The v2.1 model card instead lists 166M, 209M, and 459M English checkpoints, plus a 209M multilingual checkpoint, all under Apache 2.0. Do not compare latency or memory across those generations as if the parameter names were identical (GLiNER v2.1 model card).
For a true hard zero-shot test, hold out target types as well as target examples: the model has no labeled examples for the target task. A type description such as “a medically confirmed adverse effect caused by a treatment” gives the model more information than adverse event alone. That is not a guarantee of transfer, but description-driven ZeroNER outperformed name-only baselines on its held-out-type benchmarks (Cocchieri et al., 2025).
Training data for the original model came from the Pile-NER dataset: 44,889 passages with 240K entity spans across 13K entity types, all labeled by ChatGPT. Training GLiNER-L took about 5 hours on a single A100 (Zaratiana et al., 2024).
Benchmark results
Zero-shot results from Zaratiana et al. (2024), Tables 1 and 2. F1 combines precision and recall into one score; a higher score is better only under the same task and evaluation rules. The seven-dataset average combines five CrossNER datasets with MIT Movie and MIT Restaurant:
| Model | Params | Avg F1 (CrossNER + MIT) | Avg F1 (20 datasets) |
|---|---|---|---|
| GLiNER-L | 300M | 60.9% | 47.8% |
| GoLLIE | 7B | 58.0% | — |
| UniNER-13B | 13B | 55.6% | — |
| GLiNER-M | 90M | 55.4% | — |
| UniNER-7B | 7B | 53.7% | 45.7% |
| GLiNER-S | 50M | 52.7% | — |
| ChatGPT (GPT-3.5) | — | 47.5% | 36.5% |
GLiNER-M at 90M parameters nearly matches UniNER-13B in the paper’s seven-dataset average (55.4% vs. 55.6% F1) while using roughly 140 times fewer parameters. The 50M GLiNER-S exceeds the reported ChatGPT (GPT-3.5) result by 5 F1 points. The multilingual variant, trained only on English data, exceeds that same ChatGPT baseline in 8 of 10 non-English languages (Zaratiana et al., 2024). These comparisons use the paper’s model versions and evaluation harness; they say nothing about newer LLMs.
A minimal GLiNER call
For a new cross-encoder comparison, include the maintained GLiNER v2.5 checkpoints next to v2.1. In the companion’s check on 32 sentences from Few-NERD, a public NER dataset, gliner_small-v2.5 found 44 of 54 gold spans and gliner_medium-v2.1 found 39. That sample is too small to rank the two, but it is a reason to include v2.5 in your own run. GLiNER v2.5 and Fastino GLiNER2.5 (below) are different model families.
The call below loads the v2.1 medium checkpoint and prints each span with its score. The companion’s version is ner_demo/quickstart.py.
from gliner import GLiNER

model = GLiNER.from_pretrained("urchade/gliner_medium-v2.1")
text = "Bill Gates founded Microsoft on April 4, 1975."
labels = ["person", "organization", "date"]
entities = model.predict_entities(text, labels, threshold=0.5)

for entity in entities:
    print(f"{entity['text']} => {entity['label']} ({entity['score']:.3f})")
# Bill Gates => person (0.994)
# Microsoft => organization (0.973)
# April 4, 1975 => date (0.951)The bi-encoder: scaling to million-label NER
The original GLiNER encodes labels and text together. Joint encoding becomes progressively more expensive as label text consumes the context and must be re-encoded with every document. The crossover depends on the checkpoint, label descriptions, and hardware. When the same large type inventory is reused across many documents, make the GLiNER bi-encoder the default comparison. It splits text and label encoding into two separate transformers (Stepanov et al., 2026).
The figure compares the two designs over three documents. In the cross-encoder lane, all labels enter the encoder with every document. In the bi-encoder lane, a label encoder runs once, its vectors are cached, and only the text encoder runs per document. The chart below them shows the throughput cost at 1,024 labels.
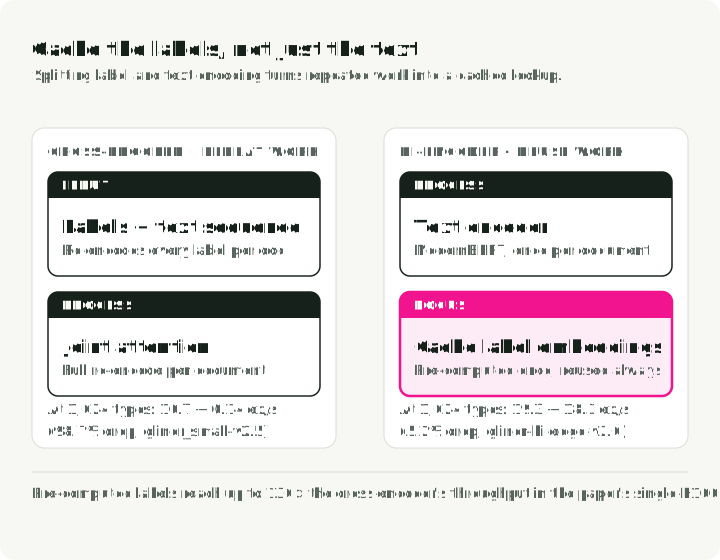
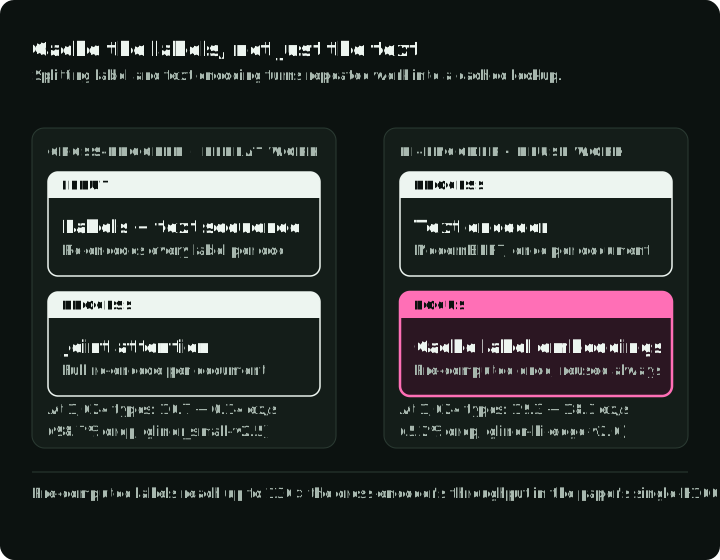
The text encoder uses ModernBERT (Ettin family), the label encoder uses sentence transformers (BGE or MiniLM). Spans and labels are scored via dot product. That split means entity type embeddings can be pre-computed once and cached. At inference, cached labels avoid repeated label encoding. Scoring candidate spans against those labels still takes compute and memory; a million-label application also needs bounded candidate retrieval or batching, with recall measured for labels excluded before scoring.
Four model sizes are available, all benchmarked on CrossNER (Stepanov et al., 2026, Table 1):
| Model | Parameters | Avg F1 (CrossNER + MIT) | Throughput (H100) | With Pre-computed Labels |
|---|---|---|---|---|
| gliner-bi-edge-v2.0 | 60M | 54.0% | 13.64 ex/s | 24.62 ex/s |
| gliner-bi-small-v2.0 | 108M | 57.2% | 7.99 ex/s | 15.22 ex/s |
| gliner-bi-base-v2.0 | 194M | 60.3% | 5.91 ex/s | 9.51 ex/s |
| gliner-bi-large-v2.0 | 530M | 61.5% | 2.68 ex/s | 3.60 ex/s |
At 1,024 entity types, the pre-computed gliner-bi-edge-v2.0 bi-encoder loses only 5.2% throughput versus a single label (19.3 → 18.3 ex/s). The comparable gliner_small-v2.5 cross-encoder loses 98.7% (10.7 → 0.14 ex/s). In the paper’s single-H100, batch-size-1 tests across 64-, 256-, and 512-token inputs, the pre-computed bi-encoder reaches an up to 130× throughput advantage over gliner_small-v2.5. With 100 entity types on a single H100, the bi-encoder processes 1.96 million predictions per day versus 368K for the cross-encoder (Stepanov et al., 2026).
The bi-encoder paper reports 61.5% for gliner-bi-large-v2.0 versus 60.9% for gliner_large-v2.5 on the same CrossNER-plus-MIT average, so the bi-encoder does not trade accuracy for speed on that benchmark. The authors recommend bi-base-v2.0 (194M) as the best size trade-off: 98% of the large model’s accuracy at 2.6x the speed (Stepanov et al., 2026).
The timing sweep stops at 1,024 labels, using an H100, batch size one, and ten forward passes per configuration. It does not measure a deployed million-label service. The paper names entity linking across large knowledge bases such as Wikidata as one use; entity linking is available through Knowledgator’s GLiNKER framework.
The code encodes the label set once and reuses the embeddings for every text. With the three labels below, it returns the same three spans as the cross-encoder call above.
from gliner import GLiNER

model = GLiNER.from_pretrained("knowledgator/gliner-bi-base-v2.0")

# Pre-compute embeddings for a reused label set; rebuild this cache when labels or the checkpoint change.
entity_types = ["person", "organization", "date"]  # Small example; large inventories need bounded candidate selection
entity_embeddings = model.encode_labels(entity_types, batch_size=8)

# Encode text and score spans against the cached labels
texts = ["Bill Gates founded Microsoft on April 4, 1975."]
outputs = model.batch_predict_with_embeds(texts, entity_embeddings, entity_types)GLiNER2 and GLiNER2.5: one schema for several tasks
The original GLiNER ecosystem split NER, relation extraction, classification, and document-level extraction across separate models. The EMNLP 2025 GLiNER2 paper unified NER, classification, and hierarchical extraction in one 205M-parameter model; current releases later added relation extraction to the same schema interface.
That 2025 architecture keeps the cross-encoder design but extends context to 2,048 tokens (4x the original) and adds declarative schemas for defining extraction tasks. Training uses 135,698 real documents annotated with GPT-4o plus 118,636 synthetic examples (Zaratiana et al., 2025).
On zero-shot CrossNER, GLiNER 2 scores 0.590 F1, close to GPT-4o’s 0.599 in the paper’s mid-2025 benchmark. For classification, it averages 0.72 across 7 benchmarks, compared with 0.69 for DeBERTa-v3-large. On CPU, the paper reports 130-208 ms classification latency across its tested label counts. The zero-shot DeBERTa baseline needs a forward pass per candidate label and rises from 1,714 ms for 5 labels to 16,897 ms for 50; this is not the runtime of a supervised DeBERTa classifier (Zaratiana et al., 2025).
The example below loads GLiNER2.5, a later checkpoint, so the 2025 scores above do not describe it. GLiNER2.5 (194M parameters) predicts span start and end positions instead of scoring every span. Its window is 4,096 tokens, so split longer documents into overlapping chunks with the library’s helper and check that the returned offsets map back to the full text. Load it with AutoExtractor, as below.
from gliner2 import AutoExtractor

# Requires `pip install gliner2[local]` and downloads the checkpoint.
extractor = AutoExtractor.from_pretrained("fastino/gliner2.5-base-v1")

# Compose tasks through the current schema interface
schema = (extractor.create_schema()
    .entities({"person": "Names of people", "company": "Organization names"})
    .classification("sentiment", ["positive", "negative", "neutral"])
    .relations(["works_for", "founded", "located_in"])
    .structure("product_info")
        .field("name", dtype="str")
        .field("price", dtype="str"))
text = "Acme launched a $19 widget in Berlin."
results = extractor.extract(text, schema)
The EMNLP paper evaluates NER and classification only. It reports no hierarchical-extraction benchmark and does not cover the later relation API. One model that runs four tasks may still score lower on each than four specialized models, so compare each task against its own baseline.
Other GLiNER variants for specific needs
The GLiNER family now has several architectures beyond the cross-encoder, bi-encoder, and GLiNER2.5. Each targets one need:
| Need | Candidate | What to verify |
|---|---|---|
| Entities and relations in one pass | GLiNER-Relex | Both span and relation F1 on the same documents. |
| Local PII candidate | GLiNER2-PII | Recall by language, document format, and PII type. |
| Multilingual open-vocabulary candidate | GLiNER-X | Per-language quality; its card lists 23 languages. |
| Generated or changing types | GLiNER Decoder | Whether generated types are stable and useful downstream. |
| Streaming PII redaction | GLiNER Streaming PII | Leaked characters before release, not only final-span recall. |
The GLiNER-Relex and GLiNER2-PII results come from their own papers and harnesses. GLiNER-X and GLiNER Decoder have model cards, not peer-reviewed benchmarks, so their numbers are not comparable with the papers above.
Streaming PII changes when you can release text
GLiNER Streaming PII adds incremental detection with a Qwen3-0.6B causal backbone and cached session state. Its API returns the whole current session snapshot, with offsets into accumulated text. Preserve chunk boundaries, keep labels fixed until a full recompute, and clear finished sessions.
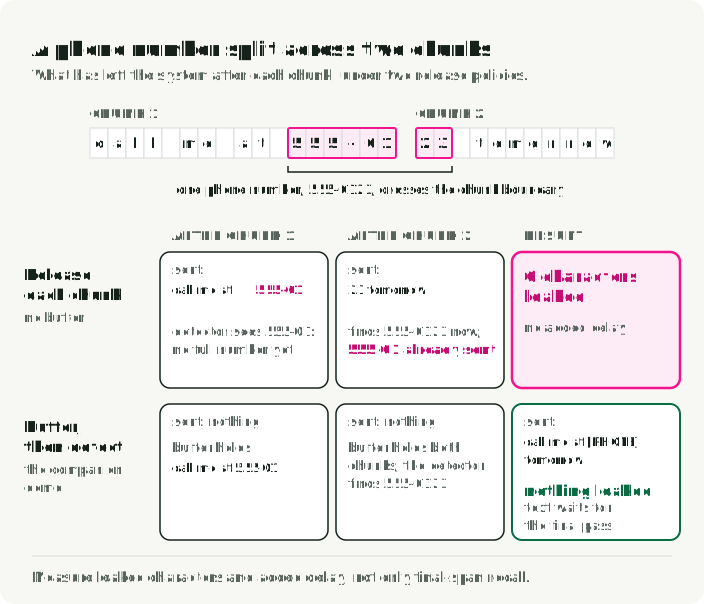
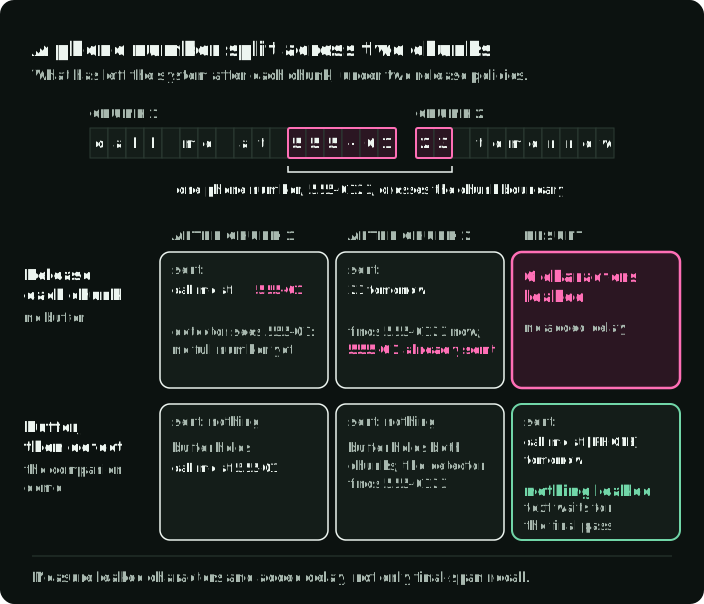
For streaming redaction, I would buffer unreleased text and test entities split across chunks. Finding a phone number after sending its first half cannot retract those bytes. Measure leaked characters before release and added delay, as well as final-span recall. The model card reports PIIMB masking F2 separately from strict typed-span F1; they answer different questions. The model card also reports weaker multilingual results, so the released checkpoint is not a universal privacy filter.
The figure splits one phone number across two chunks. Released chunk by chunk, the first half has already left when the second half arrives. Buffered, the detector sees the whole number and only masked text leaves. The companion’s ner_demo.streaming holds all text until a final detection pass, then releases it with detected spans masked.
Closed-label alternatives: spaCy and a fine-tuned token classifier
When the label set is stable and you have annotated data, you do not need GLiNER’s open labels. A model trained on that label set is the baseline to beat.
spaCy’s trained pipelines (en_core_web_sm, en_core_web_trf) recognize a fixed set of entity types (PERSON, ORG, GPE, DATE, and others) defined at training time. Expanding the trained ner component requires labeled examples and training. For identifiers or a controlled dictionary, EntityRuler adds custom labels through patterns without retraining; its recall outside those patterns is zero. The en_core_web_trf 3.8.0 model card reports 90.19 NER F1 on OntoNotes 5.0, but only for its 18 predefined types (spaCy model card).
The example adds a ticker pattern before the trained ner component, so the rule claims $AAPL first and the model labels the rest:
import spacy

nlp = spacy.load("en_core_web_trf")
ruler = nlp.add_pipe("entity_ruler", before="ner")
ruler.add_patterns([{"label": "TICKER", "pattern": [{"TEXT": "$"}, {"TEXT": {"REGEX": r"^[A-Z]{1,5}$"}}]}])

doc = nlp("Tim Cook said Apple ($AAPL) will open an office in Berlin in March 2027.")
print([(ent.text, ent.label_) for ent in doc.ents])
# [('Tim Cook', 'PERSON'), ('Apple', 'ORG'), ('$AAPL', 'TICKER'), ('Berlin', 'GPE'), ('March 2027', 'DATE')]
For stable labels with representative annotated spans, a fine-tuned token classifier such as BERT, RoBERTa, or DeBERTa is the supervised baseline. The Hugging Face pipeline loads one in a line. dslim/bert-base-NER, the fixed encoder in the companion’s evaluation, was trained on CoNLL-2003, so its labels are fixed to PER, ORG, LOC, and MISC. The date in the same sentence is not found because the model has no date label:
from transformers import pipeline

ner = pipeline("token-classification", model="dslim/bert-base-NER", aggregation_strategy="simple")
for ent in ner("Tim Cook said Apple will open an office in Berlin in March 2027."):
    print(ent["word"], ent["entity_group"], round(float(ent["score"]), 3))
# Tim Cook PER 1.0
# Apple ORG 0.998
# Berlin LOC 0.999
To get your own labels, fine-tune such a model on your annotated spans. Compare it with spaCy and GLiNER on exact-span F1, per-label recall, calibration, latency, and cost on the same domain set.
My recommendation: use spaCy or a fine-tuned token classifier for standard or stable entity types where you have training data. Use GLiNER when you need flexible, zero-shot types or when your pipeline must adapt without retraining. They can share a pipeline, with spaCy handling tokenization and sentence splitting and GLiNER handling entity extraction.
Checkpoint licenses are part of the model choice
The models in this guide do not share one license. Check the code, weight, and dataset terms of the exact checkpoint before deployment:
| Release | Published license | Practical consequence |
|---|---|---|
| GLiNER v2.1, GLiNER v2.5, and GLiNER bi | Apache 2.0 | Permissive model-card terms; still review dependencies and data. |
| GLiNER2, GLiNER2.5, and GLiNER2-PII | Apache 2.0 | Confirm the selected checkpoint, not only the library. |
spaCy en_core_web_trf and dslim/bert-base-NER | MIT | Permissive; the training corpora have their own terms. |
| UniNER-7B-all | CC BY-NC 4.0 | Do not use for a commercial path without separate permission. |
| NuNER | MIT | The released model and dataset state MIT terms. |
License labels are not legal advice. A production review must include base-model, training-data, and provider terms.
LLMs as teachers: a $70 case study and a deployable pipeline
The LLM-as-teacher pattern separates expensive annotation from cheaper inference: an LLM labels training data once, and a small encoder trained on those labels serves every request. Two research papers established that small models can learn NER from LLM labels, and two published case studies show how teams applied it.
The research behind this pattern: UniNER and NuNER
UniNER (ICLR 2024, Zhou et al.) and NuNER (EMNLP 2024, Bogdanov et al.) both distill LLM annotations into smaller NER models, but they disagree on how small you can go.
UniNER fine-tunes LLaMA-7B/13B on 45,889 input-output pairs generated by ChatGPT. For each entity type, the model answers “What describes [type] in the text?” and outputs JSON lists. A key training trick: frequency-based negative sampling boosts F1 from 31.5% to 53.4% (Zhou et al., 2024).
UniNER-7B hits 41.7% zero-shot F1 across 43 datasets, beating ChatGPT’s 34.9% by 7 points. The 13B variant reaches 43.4%, only 1.7 points more for nearly double the parameters (Zhou et al., 2024).
The production trade-off: the paper’s higher-scoring UniNER-type setup queries each entity type sequentially. Its all-in-one variant uses one response but averaged 3.3% lower. At FP16, a 7B checkpoint needs roughly 14GB just for weights; lower-bit quantization can reduce that footprint. The UniNER-7B-all checkpoint is non-commercial (see the license table above).
NuNER starts from RoBERTa-base (125M parameters) and uses contrastive training with 4.38 million GPT-3.5 annotations across 200K concepts. After training, the concept encoder is thrown away; the text encoder slots into any standard NER pipeline as a RoBERTa replacement (Bogdanov et al., 2024).
NuNER’s Table 3 reports roughly 6.1–16.2 points over RoBERTa in macro-average token-classification F1 with frozen encoders and linear heads, across four datasets and sampled training sizes (Bogdanov et al., 2024).
Both papers show that a smaller model can learn from LLM annotations. Neither shows that the student beats its teacher on a new domain, which is why the pipeline below keeps a separately reviewed test set.
The CFM case study
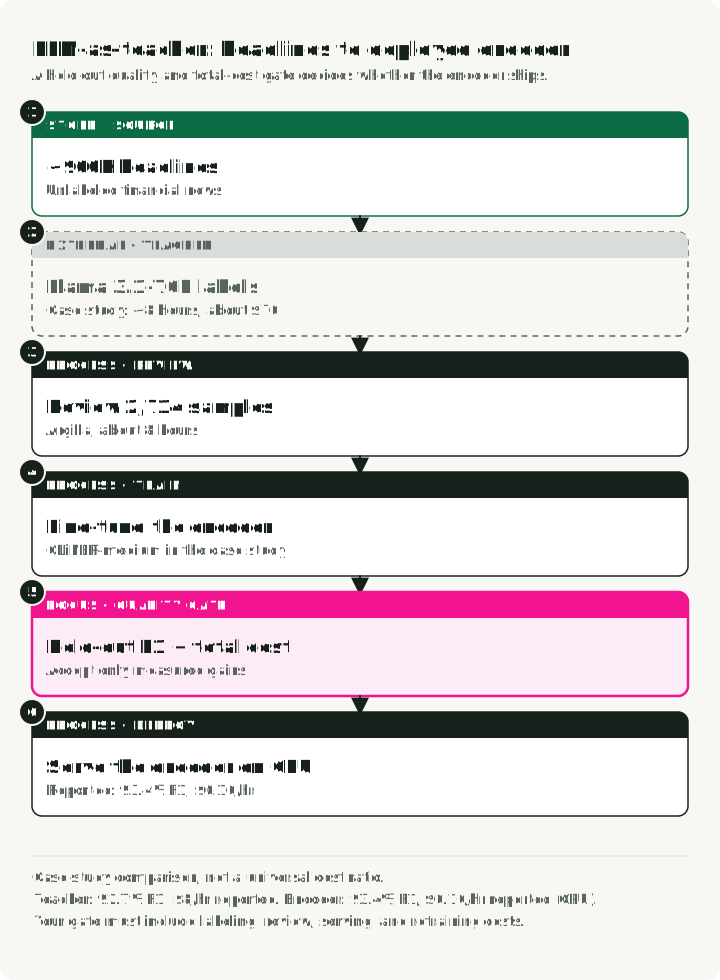
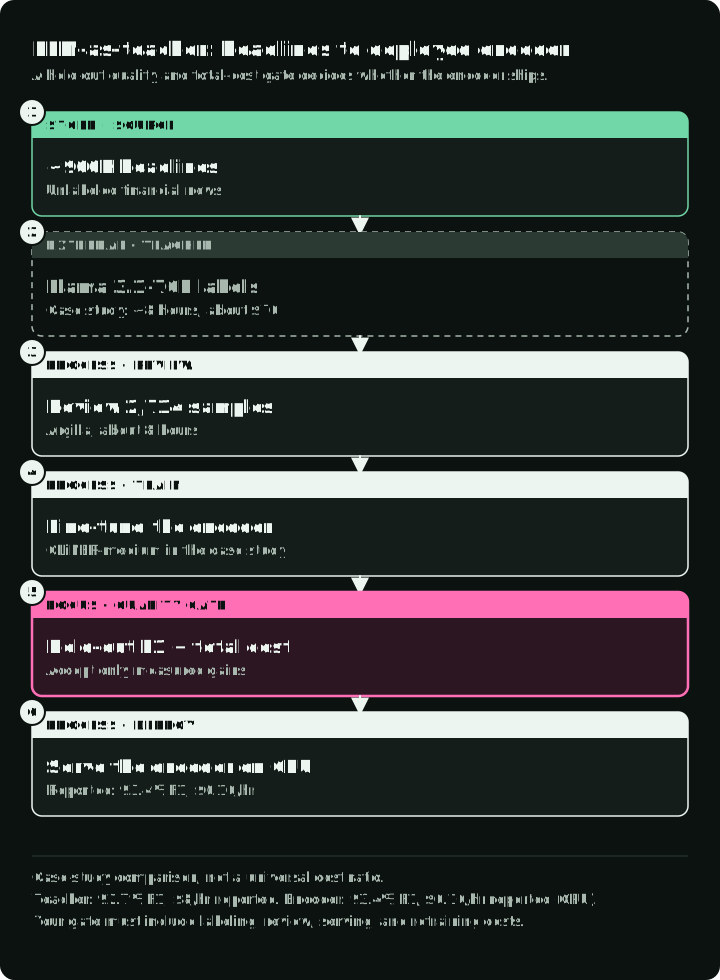
In a Hugging Face case study, Capital Fund Management extracted company names from roughly 900,000 financial news headlines. Zero-shot GLiNER scored 87.0% F1. The team used Llama 3.1-70B to annotate the dataset in roughly 8 hours for about $70, then reviewed 2,714 samples through Argilla in another 8 hours.
Fine-tuning GLiNER on this data reached 93.4% F1 in the case study, compared with the Llama-70B teacher’s 92.7%. The authors report $0.10 per hour on CPU for the fine-tuned model and $8 per hour for the teacher (CFM case study). Those figures describe one financial-news task and one infrastructure setup.
The Refuel AI study
Refuel AI’s vendor technical report benchmarks LLM labeling across 8 NLP datasets, including CoNLL-2003. It reports 88.4% agreement with ground truth for GPT-4 (March 2023) and 86.2% for the human annotators in its setup, along with 20 times faster and 7 times cheaper labeling. A separate proprietary-data ensemble experiment exceeded 95% agreement, with its best individual LLM at 89%. Confidence-based routing to cheaper or stronger models is a proposed use, not the measured mechanism behind the eight-dataset result (Refuel AI technical report).
A production pipeline
A practical production flow has six steps. The diagram places each step in the lane of whoever does it, with the CFM figures and the loop back to review when the student misses its target. The chart below it compares CFM’s F1 and hourly cost for the teacher and the student.
- Write annotation guidelines in natural language.
- Create human-labeled development and held-out test sets. The evaluation section below gives a procedure for sizing them.
- Use an LLM with a versioned prompt and explicit output schema to propose bulk training labels. Retain the requested and actual model, prompt, and source text. Reject unknown types and spans that cannot be aligned to the source.
- Review a subset via Argilla or Label Studio.
- Fine-tune a compact encoder (GLiNER, SpanMarker, RoBERTa). For GLiNER, use the repository’s
train.py(python train.py --config configs/config.yaml) or the model’strain_model()method, with the reviewed train file as training data and the development file for evaluation during training. - Deploy only after the encoder passes a held-out quality and total-cost check. CFM reported 16-80x lower hourly infrastructure cost in its setup; include annotation, review, serving, and retraining costs in your comparison.
The LLM can reduce the volume of manual annotation, but the team still owns the validation set, annotation guidelines, targeted review, and error analysis.
The companion demonstrates one teacher proposal and converts reviewed annotations for step 5 (README section). Run these commands in the companion repository with Python 3.11+, uv, and dependencies installed through uv sync --locked --all-extras. Set OPENAI_API_KEY for the paid teacher call. Conversion needs the pinned GLiNER model and backbone files cached; uv run --all-extras python -m ner_demo.quickstart --download fetches them once.
-
Run the one-document teacher demo. It makes one paid request for a fixed sentence about NVIDIA’s proposed acquisition of Arm and writes one unreviewed record to
artifacts/teacher_annotations.jsonl:uv run --all-extras python -m ner_demo.teacher --allow-paid -
Review the proposal by hand and resolve rejected annotations. Prepare
artifacts/reviewed.jsonlwith reviewed training documents and the separately human-labeled development and test documents from the production flow above. All three splits must be nonempty, document IDs must be unique, and no source text may occur in more than one split. Do not copy the demo sentence across splits. Setreviewed: true, areviewer,status: "ok", and asplit(train,development, ortest) on each record, and keep itssource_sha256matched to the source text. One demo record cannot supply all three splits. -
Convert that complete reviewed file. This writes
train.json,development.json, andtest.jsonunderartifacts/training/in GLiNER’s training format, after passing every row through GLiNER’s own data collator:uv run --all-extras python -m ner_demo.training artifacts/reviewed.jsonl
Pass train.json and development.json to the GLiNER fine-tuning run in step 5, and keep test.json for the final check.
Where GLiNER fails and LLMs remain useful
The Sease benchmark (October 2025) tested GLiNER against GPT-4.1-mini on 30 query-parsing tasks. GPT-4.1-mini got 100% fully correct. GLiNER got 53% (16 of 30). But GLiNER responded in 0.08 seconds versus the LLM’s 1.21 seconds, 15x faster.
In this 30-task benchmark, GLiNER failed in three recurring patterns:
- Implicit entities: extracting “event” from “Elton John performed at Madison Square Garden”. No text literally says “event,” but the LLM infers “concert”.
- Label phrasing sensitivity: “2022” scores 0.388 against “date” but 0.958 against “year”. Small label changes cause large score swings.
- Value mapping: GLiNER returns the exact surface text (“family houses”) instead of the canonical value (“Single family house”). An LLM can perform that normalization when its prompt and schema define the target values.
Nested and overlapping entities
A nested entity sits inside another one. In “New York University,” “New York” is a location inside an organization name. Biomedical text (“acute myeloid leukemia” inside a longer diagnosis) and legal text (a department inside a named authority) have the same pattern.
GLiNER defaults to flat decoding, which suppresses overlapping spans. Its API also supports flat_ner=False, which allows overlapping predictions:
entities = model.predict_entities(
    "She studied at New York University.", ["organization", "location"],
    flat_ner=False, threshold=0.3)
# [{'text': 'New York University', 'label': 'organization', 'score': 0.855, ...}]
With urchade/gliner_medium-v2.1, this call returned only the organization, even at a threshold of 0.05. Turning off flat decoding allows nested output, but the checkpoint still has to score the inner span above the threshold. If your data has nested entities, build a nested test set and check whether the inner spans appear at all before choosing GLiNER over a specialized nested NER model.
Use GLiNER for explicit entity extraction and route cases requiring inference, reasoning, or mapping to predefined ontologies to an LLM. The routing threshold should come from a labeled domain set.
Evaluating NER: metrics, pitfalls, and test sets
Every number in this guide comes from its source’s model, data, and hardware. Rerun the comparison on your own labeled set before you choose. This section explains how to build that set and score it.
A model can score 95% F1 on a curated test set and still fail on the document mix it sees after deployment. Build the evaluation set from the production distribution and keep slices for the rare formats and entity types that aggregate F1 can hide.
The core metrics
Identify each occurrence by document ID, half-open start/end offsets, and type, and verify that text[start:end] recovers the mention. Two occurrences of “John” are two targets. The figure scores three predictions for one sentence.
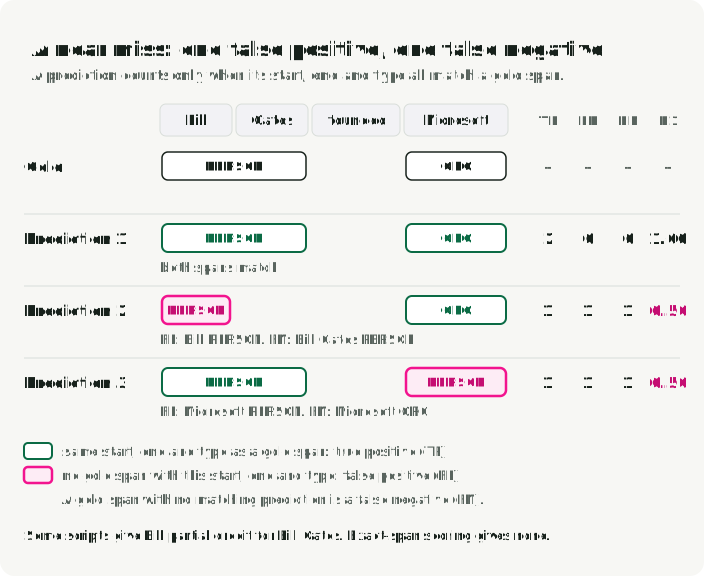
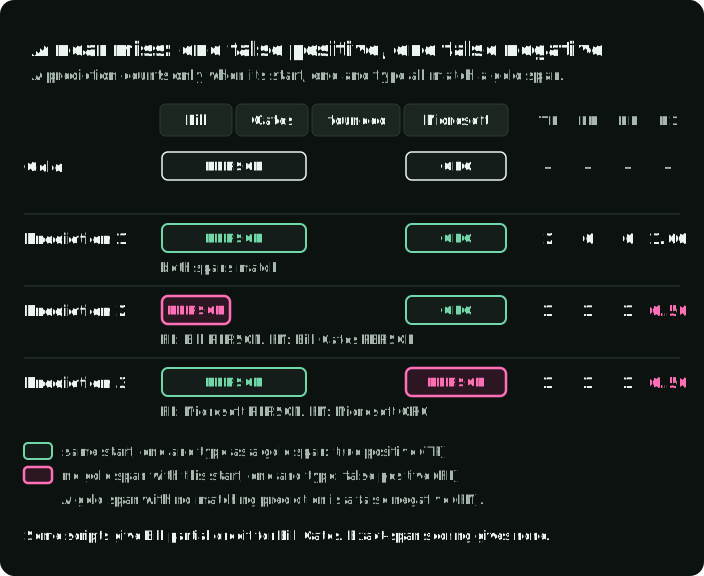
Validate document counts before matching: missing predictions must create false negatives, not disappear through zip(). Count wrong types or offsets as an unmatched prediction and an unmatched gold span. Report micro precision, recall and F1, per-type support and recall, and define macro aggregation and empty cases. The companion’s exact evaluator implements these rules and keeps missing, failed, and skipped documents in the gold denominator.
- Entity-level F1: The standard metric. A prediction is correct only if both the span boundaries and the type match ground truth exactly. This is what most papers report.
- Token-level F1: Scores each token independently. It can make a partial boundary look better than an exact-span score, so report exact-span F1 when boundary correctness matters; use token-level metrics only when the downstream decision is token-level.
- Precision vs Recall: These often have asymmetric costs. For de-identification, recall matters more: missing a name is worse than over-redacting. For database extraction, precision matters more: false entries corrupt downstream analysis.
Common evaluation pitfalls
- Partial match inflation: “Bill” extracted when the gold label is “Bill Gates”. Some scripts count this as a partial match. Use exact span matching unless you have a reason not to.
- Type confusion: “Microsoft” correctly identified as a span but labeled PERSON instead of ORG should score zero. Check your evaluation code handles this.
- Test set leakage: Keep duplicate and near-duplicate records, documents, and annotations out of the test set. For a hard zero-shot claim, also keep target entity types out of training; repeated surface strings alone are not leakage.
- Uncontrolled label prompts: A short type name and a tested type description are different inputs. Version label descriptions, thresholds, checkpoint revisions, and decoding mode with the score.
- One-language zero-shot claims: Do not infer multilingual quality from English. OpenNER spans 36 corpora and 52 languages, and its baselines found no single model best in every language (Palen-Michel et al., 2025). In FiNERweb experiments, switching from English to target-language labels changed F1 by 0.02–0.09 depending on the setting (Golde et al., 2026). Test both label languages when the product uses local terminology.
- One run as the final result: Report variation across random seeds where applicable, threshold sweeps, and repeated production samples. Small slice counts make a model ranking unstable.
Keep normalization, entity linking, record grouping and relation endpoints separate from extractive F1. For privacy, report leaked instances and affected auto-accepted documents, false redactions, and review fraction. For serving, report completion rate, p50/p95 document latency, cold and warm runs, batch and label sizes, peak memory, and cost per accepted document.
Building a domain test set
For production evaluation, I recommend:
- Sample from production data, not curated examples. Include the messy documents your model will actually see.
- Size the test set from a pilot. Label a pilot of about 50 documents, count gold spans per label, and bootstrap per-label recall. Add documents until the 95% interval for the rarest label you care about is narrower than the difference you need to detect.
- Use at least two annotators on a calibration subset. Adjudicate disagreements and report exact-span F1 between the two annotators’ spans. Agreement shows where the guidelines are ambiguous; it is not an upper limit on model performance.
- Stratify by difficulty: easy cases (clean text, standard types) and hard cases (ambiguous entities, jargon, noisy text).
- Keep privacy and fairness slices. For PII, report recall by PII type, language, locale, document format, and relevant demographic or name-origin slices. Minimize evaluator access to raw sensitive text, set retention limits, and review false negatives.
Continual NER needs an immutable regression set
Production taxonomies change. Add new types without silently changing what an old type means. Keep a versioned, immutable regression set for existing types, a separate test set for the new type, and a changelog for annotation-guideline changes. Report old-type and new-type scores separately before replacing a checkpoint. This is the simplest way to detect forgetting and taxonomy drift.
Production NER across four industries
Each domain extracts different things and has a different published starting point. The last column names the caveat that changes what you test first.
| Domain | What is extracted | Starting point | Caveat that changes a choice |
|---|---|---|---|
| Healthcare | Names, dates, IDs, and other PHI for de-identification | The John Snow Labs and Providence evaluations above; OpenMed’s open medical NER models | Report leaked instances and affected documents, not only F1. |
| Finance | Company mentions in news; fields in filings | The CFM case study for news; FinBERT-MRC for filings (92.78 F1 on ChFinAnn, 96.80 on AdminPunish) | FinBERT-MRC results are on Chinese filings; test English SEC filings, long documents, and nested entities separately. |
| E-commerce | Product type, brand, and attributes in search queries | Walmart’s EAMT (about 60 query NER labels); Home Depot’s TripleLearn (held-out F1 69.5 → 93.3, in production 9+ months) | TripleLearn’s method is repeated rounds of domain supervision; the paper does not compare current architectures. |
| Cybersecurity | Malware, threat actors, and indicators of compromise | CyNER (76.66 span micro-F1, XLM-RoBERTa-large); CyberNER (21 STIX 2.1 labels, RoBERTa 0.736 F1) | Research datasets only; label sets differ, so map them to STIX before comparing models. |
Deployment optimization: from Python to lower-latency inference
Once a model passes the domain test set, the next question is how to serve it. This is the order I would try the runtimes, with a check after each step. Change one thing at a time, so a quality drop has one cause.
- Serve with PyTorch and Ray Serve.
- Export ONNX FP32, or run it with gline-rs. If the spans differ from PyTorch, fix the export.
- Quantize to dynamic INT8, keeping FFN down-projections in FP32.
- Deploy INT8 only if per-label recall stays within target. Otherwise keep FP32.
Native GLiNER serving
Before moving to a new runtime, test the project’s Ray Serve path. gliner[serve] provides dynamic batching, memory-aware batch sizing, multi-replica scaling, and an HTTP client. Batching and replicas can improve throughput while keeping the model code. Batching also adds waiting time, so measure queue latency and warm latency under your request mix.
ONNX export
GLiNER has native ONNX conversion, and pre-converted models exist on Hugging Face (onnx-community/gliner_small-v2.1). Export writes the graph, config, and tokenizer into one directory, and the same GLiNER class loads it back with the same predict_entities call:
from gliner import GLiNER

model = GLiNER.from_pretrained("urchade/gliner_medium-v2.1")
model.export_to_onnx("onnx/fp32")

onnx_model = GLiNER.from_pretrained("onnx/fp32", load_onnx_model=True)
entities = onnx_model.predict_entities(text, labels, threshold=0.5)
The companion’s ONNX comparison runs PyTorch, ONNX FP32, and ONNX INT8 on the same inputs and compares their spans. It needs Python 3.11+ and uv. The data command downloads a pinned Few-NERD shard and keeps its first 32 sentences, enough to check the export, not to rank models. The quickstart with --download fetches the pinned checkpoint once:
uv sync --locked --all-extras
# Run once if the pinned model files are not cached:
uv run --all-extras python -m ner_demo.quickstart --download
uv run --all-extras python -m ner_demo.data --split test --limit 32
uv run --all-extras python -m ner_demo.onnx_check \
  --dataset artifacts/few-nerd-test.json --output artifacts/onnx-comparison
Use a new output directory, or --reuse to check existing packages. The command fails when FP32 spans differ from PyTorch, or when INT8 loses more than 0.02 micro recall. On an Apple M5 Max CPU, FP32 ONNX returned exactly the PyTorch spans with a p50 latency of 16-19 ms per sentence, against 64-66 ms for PyTorch.
INT8 quantization
Dynamic INT8 quantization stores weights as 8-bit integers and makes the ONNX file smaller. For GLiNER’s DeBERTa encoder, quantizing every layer does not work. In the companion, quantizing all MatMul layers returned no entities at all. Quantizing layers one group at a time showed the cause: the twelve FFN down-projections (layer.N/output/dense, the second linear layer of each encoder block’s feed-forward network) alone push every score below the threshold. Keeping those twelve layers in FP32 fixes it. The code copies the FP32 package (for its config and tokenizer files), then quantizes everything else:
import shutil

import onnx
from onnxruntime.quantization import QuantType, quantize_dynamic

shutil.copytree("onnx/fp32", "onnx/int8")
graph = onnx.load("onnx/fp32/model.onnx", load_external_data=False).graph
keep_fp32 = [n.name for n in graph.node if n.op_type == "MatMul" and "/output/dense/" in n.name and "/attention/" not in n.name]

quantize_dynamic("onnx/fp32/model.onnx", "onnx/int8/model.onnx",
                 weight_type=QuantType.QInt8,
                 op_types_to_quantize=["MatMul", "Gemm", "Gather"],
                 nodes_to_exclude=keep_fp32)
Load onnx/int8 with load_onnx_model=True, as for FP32. The companion’s quantize_package does the same and then validates the package. On the 32 Few-NERD sentences (Apple M5 Max, ONNX Runtime 1.24.4), the measured results were:
| Path | Package | p50 latency | Micro precision | Micro recall |
|---|---|---|---|---|
| PyTorch | - | 64-66 ms | 0.506 | 0.722 |
| ONNX FP32 | 790 MB | 16-19 ms | 0.506 | 0.722 |
| ONNX INT8 | 353 MB | 13-15 ms | 0.487 | 0.722 |
INT8 cut the package by more than half and kept recall, but it changed the spans in 4 of 32 sentences and added 3 false positives. On this run, INT8 is worth it when memory or package size is the limit; for latency alone, most of the gain came from the FP32 ONNX export. Check per-label recall against FP32 on your own data before you deploy it: a smaller file says nothing about extraction quality. Current GLiNER guidance recommends quantization-aware training when INT8 accuracy must match FP32.
gline-rs: Rust reimplementation
gline-rs (Apache 2.0) removes the Python runtime from the inference path. The project reports about four times Python’s CPU throughput in its own benchmark. It supports span and token models, GPU/NPU via ONNX Runtime, and ships as a crate on crates.io. It loads an ONNX export and its tokenizer.json, such as the package written above; the project README shows the Rust call.
The fast-gliner package provides Python bindings via PyO3.
Which runtime to use when
| Path | Use when | Evidence available | Measure before deployment |
|---|---|---|---|
| Native Ray Serve | You want to keep Python and add batching, replicas | GLiNER project documentation | Queue latency, warm latency, throughput |
| ONNX FP32 | First runtime change on any hardware | Companion: same spans as PyTorch, 3.4-4x lower latency | Warm latency, throughput, and exact-span F1 |
| ONNX INT8 | Memory or package size is the limit on CPU | Companion: 353 MB vs 790 MB, same recall, 3 extra FPs | Per-label recall and precision against FP32 |
| gline-rs | You need to remove the Python runtime | Project benchmark under its documented hardware/setup | Your model mode, labels, hardware, and batch |
Structured extraction: native schemas, Instructor, and local decoders
When you need more flexibility than encoder models offer (implicit entities, reasoning, ontology mapping), begin with the provider’s native schema mechanism. OpenAI supports strict json_schema response formats, Anthropic structured outputs supports JSON outputs and strict tool inputs, and the Gemini API supports a JSON Schema subset. A shared Pydantic or Zod model can describe the contract, but each provider accepts a different schema subset and has different refusal and complexity behavior.
Schema conformance makes parsing reliable. It does not prove that an extracted span exists in the source text or that a normalized value is correct. Validate field values, preserve offsets or quotations when possible, and score semantic accuracy on a labeled set.
The three libraries below enforce structure in different ways. The figure runs one sentence through each: Instructor validates and retries, Outlines blocks an invalid label while decoding, and LangExtract returns character offsets for each field.
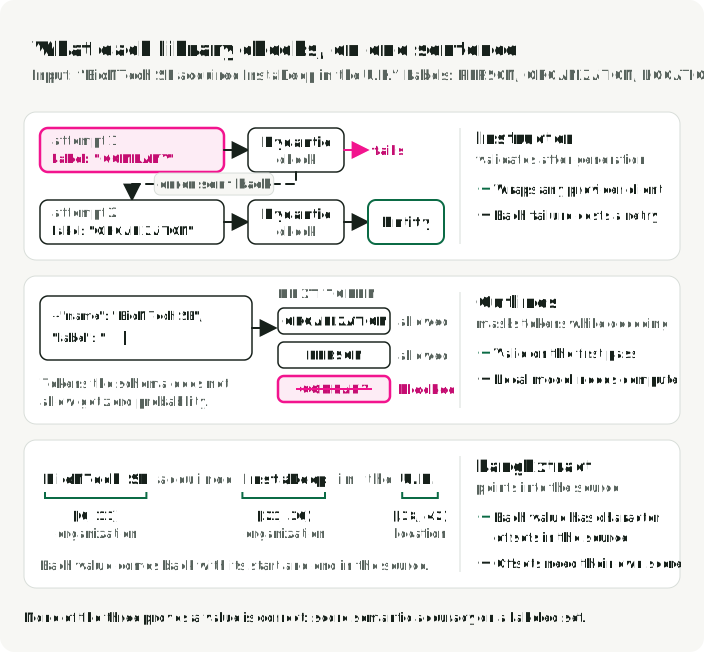
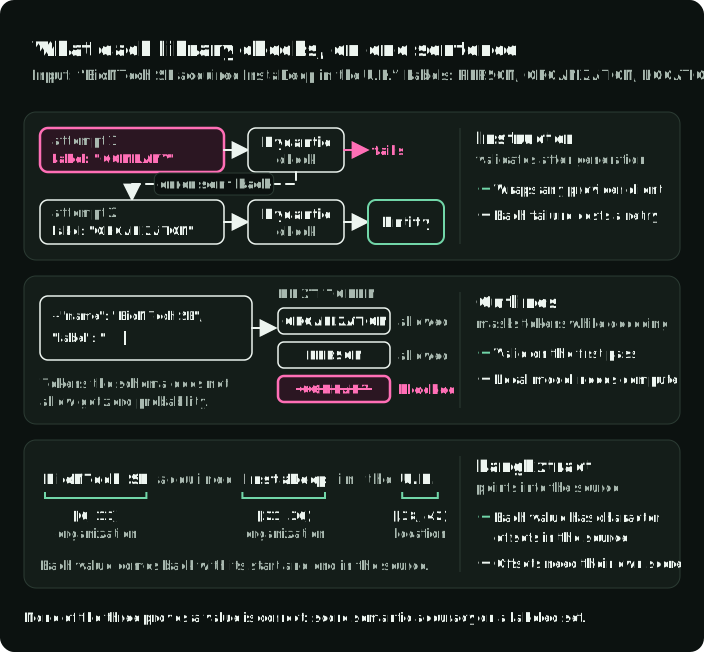
Instructor wraps provider clients with Pydantic validation and optional retries after validation failures.
This standalone example requires pip install instructor openai pydantic, an OPENAI_API_KEY, and a paid provider request. Any model with structured-output support works here; the example uses gpt-5.4-mini, the same default as the companion’s teacher.
import instructor
from pydantic import BaseModel
from typing import List, Literal
from openai import OpenAI

class Entity(BaseModel):
    name: str
    label: Literal["PERSON", "ORGANIZATION", "LOCATION"]

class ExtractEntities(BaseModel):
    entities: List[Entity]

client = instructor.from_openai(OpenAI())
result = client.chat.completions.create(
    model="gpt-5.4-mini", reasoning_effort="none",
    response_model=ExtractEntities,
    messages=[{"role": "user", "content": "BioNTech SE acquired InstaDeep in the U.K."}])
# entities=[Entity(name='BioNTech SE', label='ORGANIZATION'), ...]
Outlines by dottxt takes a different approach: constrained token generation through finite-state machines. The decoder masks tokens that would violate the target grammar instead of waiting for a validation failure and retrying. An AWS overview cites 98% schema adherence versus 76% for post-generation validation. It also repeats .txt Engineering’s claim of up to 5 times faster generation, without enough method detail to compare the two figures.
In Outlines, outlines.from_transformers wraps a Hugging Face model and its tokenizer. Calling that model with a prompt and a Pydantic class such as ExtractEntities above returns JSON that matches the class. For a new self-hosted extraction comparison, include current Qwen3.8-27B or the smaller Qwen3.5 checkpoints. Load them with their documented model loader, chat template, and serving backend; a multimodal architecture or a reasoning format may need more than a new model ID.
LangExtract is useful when a generated field must be grounded in the source: it returns character intervals and supports hosted or local LLM backends. For self-hosted document extraction, NuExtract converts JSON schemas to templates and includes multimodal document models. Both are structured-extraction systems, not drop-in replacements for span NER: their field, offset, and layout outputs need their own scores.
The choice depends on where you run your models. Native schemas are the lowest-friction path for a supported provider. Instructor adds a provider-agnostic Pydantic validation and retry layer. Outlines constrains local generation against a schema. LangExtract prioritizes source grounding, while NuExtract targets self-hosted document extraction. All LLM paths still include autoregressive generation, so they usually take longer per document than an encoder on the same hardware.
The three-tier production architecture
I would route production NER by task shape rather than by one model ranking. Each row of the figure shows an example request, what comes back, and the models to test. Reviewed Tier 3 cases return to Tier 1 only as spans found in the source.
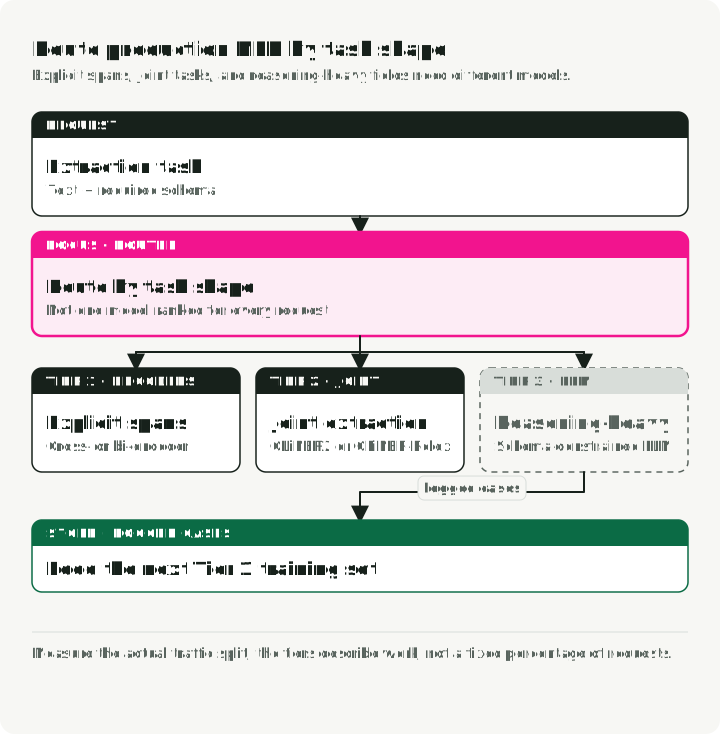
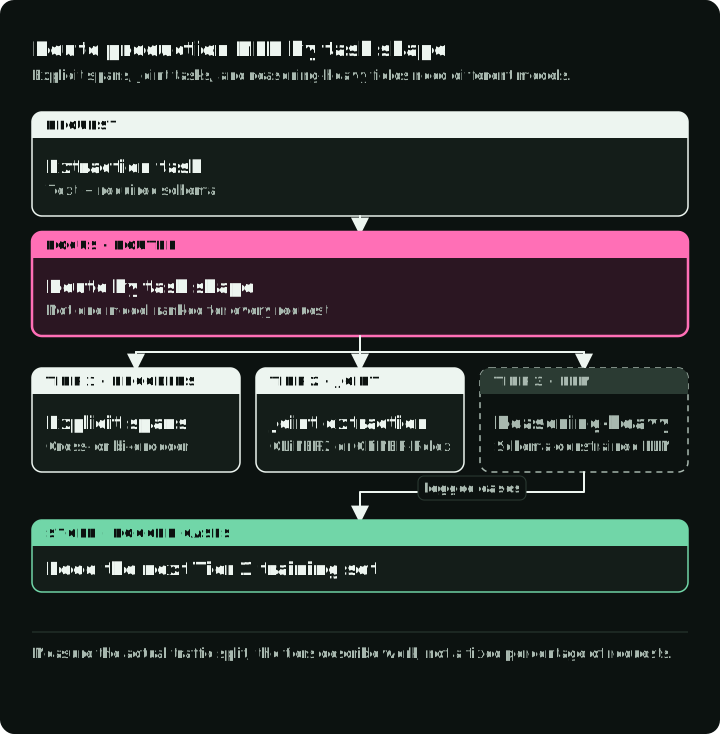
Tier 1: encoder models for explicit spans. Use a GLiNER cross-encoder for a small type inventory. When a large inventory is reused, compare the bi-encoder with cached type embeddings. Fine-tune through the LLM-as-teacher pipeline, then deploy with native serving, ONNX, INT8, or gline-rs only when that path passes the domain benchmark.
Tier 2: multi-task or relation extraction. When one request needs NER, classification, and hierarchical fields, test the current 194M-parameter GLiNER2.5 checkpoint against separate per-task baselines. When the central requirement is joint spans plus relations, test GLiNER-Relex. The GLiNER2 paper reports 130-208 ms CPU classification latency across its tested label counts; it did not measure the later relation API.
Tier 3: LLMs for reasoning-heavy extraction. Route implicit entities, contextual inference, and ontology mapping to a native schema API or Instructor for cloud APIs, and to Outlines for local constrained output. Use LangExtract when source intervals are essential and NuExtract when the document itself is the input. Log these cases for review. Only explicit, source-aligned spans can become ordinary Tier 1 training targets; inferred facts and normalized values need their own targets and evaluation.
The CFM case study gives one cost reference for Tier 1: 93.4% F1 at a reported $0.10 per hour on CPU, compared with 92.7% F1 and $8 per hour for its Llama-70B teacher. Hourly instance prices do not determine cost per document without throughput. Recalculate with your hardware, teacher model, label set, utilization, and review cost.
Trade-offs and limitations
LLM-as-teacher errors propagate. If the LLM consistently gets a specific entity type wrong (e.g., confusing subsidiary names with parent companies), the fine-tuned encoder inherits that bias. Review low-confidence or inconsistent types heavily, and keep a stratified random sample to catch confident systematic errors.
A valid schema can contain false facts. Native structured output, Instructor, and constrained decoders can make a response parseable. They cannot ensure that every field is grounded, that a span boundary is correct, or that a normalized value maps to the right record. Retain source evidence and validate semantics separately.
Quantization losses depend on the checkpoint and the layers you quantize. Quantizing every MatMul layer of the companion’s GLiNER returned no entities; keeping the FFN down-projections in FP32 kept recall on its 32-sentence check. Another checkpoint can have different sensitive layers. Compare the quantized and original models on exact-span F1 and per-label recall before deployment.
When the three-tier architecture is overkill. A single domain with stable entity types and enough labeled examples may need only a fine-tuned RoBERTa or spaCy pipeline. The three-tier pattern fits multiple domains, evolving entity types, or a measured mix of explicit and reasoning-heavy extraction. A narrow invoice pipeline that extracts names and dates may stop at Tier 1.
Bi-encoder quality varies by dataset and checkpoint size. On CoNLL-2003, gliner_small-v2.5 scores 65.4% F1, above the bi-encoder edge/small models at 61.6%/64.2% but below bi-base/large at 65.6%/66.5% (Stepanov et al., 2026, Tables 2–3). Choose from measured exact-span quality, calibration, label count, and throughput on your domain set.
PII and multilingual claims require slices. A high aggregate score can hide a dangerous recall loss for a locale, name form, document layout, or rare PII class. Use a privacy model as one of several controls, set a false-negative response process, and re-evaluate when the taxonomy, language mix, or data source changes.
Key takeaways
- Use a compact encoder for explicit spans only after it passes a domain test set with per-type support and confidence intervals.
- Use GLiNER for changing label vocabularies. Compare its bi-encoder first when a large type inventory is reused; enable
flat_ner=Falseonly after checking that the checkpoint finds the inner spans. - Use spaCy or a fine-tuned token classifier when the labels are stable and you have training data.
- Use tested type descriptions for hard zero-shot claims, and test English and localized label wording separately for multilingual products.
- Keep OCR, NER, relation extraction, and entity linking as distinct evaluation stages even when one model exposes several tasks.
- Treat an LLM teacher as an annotation proposal system. Human guidelines, adjudication, immutable regression sets, and a held-out test set remain required.
- Use native schemas for supported LLM providers, but validate semantic correctness and source grounding separately from JSON validity.
- Change one runtime step at a time: ONNX FP32 first, then INT8 with the sensitive layers kept in FP32, with a span comparison after each step.
References
Papers
- GLiNER: Generalist Model for Named Entity Recognition using Bidirectional Transformer - Zaratiana et al., NAACL 2024. The foundational span-entity matching architecture.
- GLiNER2: An Efficient Multi-Task Information Extraction System with Schema-Driven Interface - Zaratiana et al., EMNLP 2025 System Demonstrations. Unifies NER, classification, and hierarchical extraction; current releases later added relation extraction.
- GLiNER Bi-Encoder: Scalable Named Entity Recognition with Bi-Encoder Architecture - Stepanov et al., February 2026. Decoupled encoding for million-label scale.
- GLiNER-Relex: A Unified Framework for Joint Named Entity Recognition and Relation Extraction - Stepanov et al., 2026. Joint, zero-shot entity and relation extraction.
- GLiNER2-PII: A Multilingual Model for Personally Identifiable Information Extraction - Zaratiana et al., 2026. 42 PII types at character-span resolution.
- ZeroNER: Fueling Zero-Shot Named Entity Recognition via Entity Type Descriptions - Cocchieri et al., ACL 2025. Hard zero-shot evaluation with type descriptions.
- OpenNER 1.0: Standardized Open-Access Named Entity Recognition Datasets in 50+ Languages - Palen-Michel et al., EMNLP 2025. 36 corpora, 52 languages, and multi-ontology baselines.
- FiNERweb: Datasets and Artifacts for Scalable Multilingual Named Entity Recognition - Golde et al., EACL 2026. Multilingual labels and transfer evaluation.
- UniversalNER: Targeted Distillation from Large Language Models for Open Named Entity Recognition - Zhou et al., ICLR 2024. LLM-based universal NER via distillation from ChatGPT.
- NuNER: Entity Recognition Encoder Pre-training via LLM-Annotated Data - Bogdanov et al., EMNLP 2024. Studies a 125M encoder pretrained on LLM annotations.
Industry papers
- EAMT: Entity-Aware Multi-Task Learning for Query Understanding - Walmart, KDD 2023. Multitask query understanding with about 60 NER labels.
- TripleLearn: End-to-End NER for E-Commerce Search - Home Depot, AAAI 2021. F1 from 69.5 to 93.3.
- CyNER: A Python Library for Cybersecurity Named Entity Recognition - Neural recognition combined with other extraction sources.
- CyberNER: A Harmonized STIX Corpus for Cybersecurity NER - 21 STIX 2.1-aligned entity types.
- FinBERT-MRC: Financial NER via Machine Reading Comprehension - MRC formulation evaluated on Chinese financial datasets.
Case studies
- CFM Case Study: Fine-tuning GLiNER for Financial NER - Capital Fund Management’s $70 LLM labeling pipeline achieving 93.4% F1.
- Refuel AI: LLM Labeling Technical Report - GPT-4 achieving 88.4% annotation agreement, exceeding human annotators.
- Sease: GLiNER as an Alternative to LLMs for Query Parsing - Where GLiNER fails and LLMs are still needed.
- John Snow Labs: Medical Text De-Identification Benchmark - Vendor study with label remapping and exclusions.
- OpenMed: Year in Review 2025 - Open medical NER models; January 2026 retrospective.
Tools and frameworks
- ner-field-guide demo repo - Companion code for this article: exact span scoring, GLiNER examples, reviewed annotation conversion, ONNX FP32 and INT8 checks, and a streaming PII demo.
- GLiNER - Library, training script, and Ray Serve path with dynamic batching and multi-replica deployment.
- gline-rs: Rust reimplementation of GLiNER - Rust inference over GLiNER ONNX files; Apache 2.0 code.
- spaCy English pipelines - Versioned closed-label pipeline metrics.
- dslim/bert-base-NER - BERT token classifier fine-tuned on CoNLL-2003.
- Microsoft Presidio - PII analysis and anonymization with custom recognizers.
- Instructor - Structured LLM extraction via Pydantic models.
- Outlines - Constrained token generation via FSMs, with a reported schema-adherence benchmark.
- LangExtract - Source-grounded structured extraction with character intervals.
- NuExtract - Self-hosted, schema-to-template document extraction.
- OpenAI Structured Outputs - Strict JSON-schema response format reference.
- Anthropic Structured Outputs - JSON outputs and strict tool inputs.
- Gemini Structured Outputs - JSON Schema subset for structured responses.
- ONNX Runtime quantization - Dynamic and static INT8 quantization reference.
- AWS: Structured Output with Outlines - 98% schema adherence benchmark.