AI Agent Memory: Schema-Guided State and Provenance

This article is for engineers building long-running or multi-tenant agents. Plain semantic memory has no rule for which value of a fact is current, so agents return stale facts. When a user changes a passport deadline from July 15 to June 30, vector search can retrieve both statements. A stateful memory layer must record that the June 30 value supersedes the earlier one.
You will learn how to store memory as typed records with validity windows, tenant scope, and source links, write a correction without losing history, and test current and point-in-time reads.
Why context and vector recall return stale facts
The context window is the input available to one model call. An application may carry messages into later calls, but application policy must decide which old facts remain true and who may see them.
Long-running agents need to remember preferences, task status, customer facts, tool decisions, compliance notes, and prior mistakes. The easy version is to append summaries or dump old notes into a vector store. That works until one of the remembered facts changes.
Now the agent has two passport deadlines, two preferred formats, or two project decisions. Semantic search may retrieve both. A summary may overwrite one. A long context may include the stale one next to the active one. These designs return text but cannot say which value is current.
The memory contract has to answer concrete questions:
- What is true now?
- What was true on June 2?
- Who said it?
- Which tenant does it belong to?
- Which older fact did this fact replace?
- Can I delete or expire it?
Schema-Guided Agent Memory (SGAM) stores those answers as fields and relations instead of leaving them implicit in prose.
What SGAM means
Two similarly named research ideas set the scope of SGAM.
Schema-Guided Memory (SGM) is the research term used by Mei et al. in According to Me: Long-Term Personalized Referential Memory QA. The paper compares free-text Descriptive Memory (DM) with fixed-schema key-value memory items. Both representations contain the same source information in different structures. An earlier use of the name, the Schema-Guided Dialogue dataset, tracks dialogue state for service APIs and is unrelated to long-term memory.
In this article, I use Schema-Guided Agent Memory (SGAM) to mean an engineering pattern in which schemas govern writes, updates, retrieval, and deletion. The schema defines application state and its lifecycle.
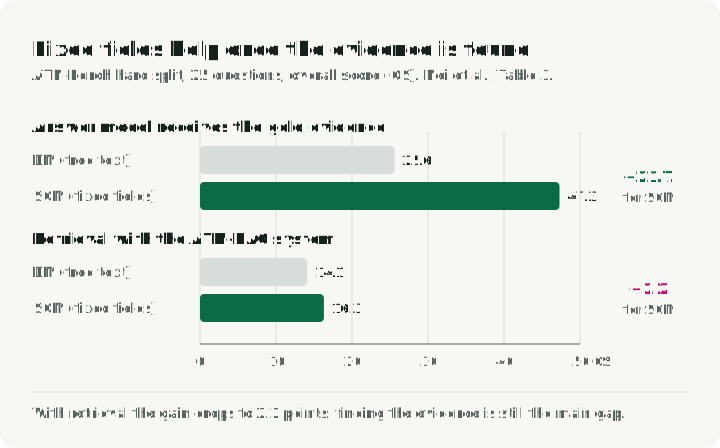
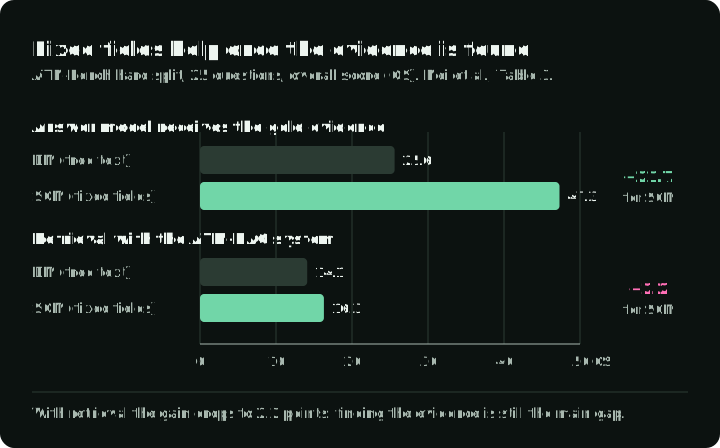
ATM-Bench shows why the representation matters. It uses roughly four years of personal data from emails, images, and videos. The questions require personal references, location, multiple pieces of evidence, and updates over time. SGM exposes fields such as time, source, location, entities, and tags in a fixed representation. On the 25-question hard split, Table 3 of the paper reports the overall score (QS) rising from 25.6 with DM to 47.3 with SGM when the answer model receives the gold evidence. With retrieval in the authors’ ATM-RAG system, the hard-split score rises only from 14.1 to 16.3, so finding the evidence is still the main gap.
The chart puts the four hard-split scores side by side. Compare the gain from fixed fields with gold evidence and with retrieval.
SGM versus DM answers a storage question: should memory remain free text, or should it use named fields? A production agent has another problem before storage. It must turn an unstructured conversation into a proposed memory update. The next section shows how Schema-Guided Reasoning (SGR) shapes that model call and where SGAM takes over.
Separate model extraction from memory ownership
The memory write crosses three layers. Structured Output (SO) enforces the candidate object’s shape. Schema-Guided Reasoning (SGR) makes the model’s intended fields and decision intent inspectable in a structured response. Schema-Guided Agent Memory (SGAM) manages the candidate as durable state after the model call. Separate calls, validators, and application policy enforce dependencies, order, and lifecycle rules.
Earlier articles apply SGR to structured judges, planners and routers, and RAG rubrics. In each one, a verdict, route, or plan usually expires with the current request. Another run may read a memory candidate days later or use it to choose a tool call. That longer lifetime demands storage rules that SGR doesn’t provide.
SGR lays out the fields of one model response in the order the model should fill them. For a memory write, the response might include source evidence, a normalized subject and attribute, a comparison with current state, and a proposed update. Pydantic or JSON Schema describes those fields. Provider-native Structured Output or a guided decoding runtime such as XGrammar keeps the response in that shape. The shape cannot guarantee a correct conclusion or prove that the model used those fields in order.
SGAM decides what happens after that object exists. Should it be stored? Does it supersede an older fact? Which tenant can see it? Is it current or historical? Which source episode backs it?
The table sets out the ownership and failure mode of each layer:
| Dimension | SO | SGR | SGAM |
|---|---|---|---|
| Purpose | Return an object that conforms to a schema | Make intended fields and decision intent inspectable | Manage durable memory after the model call |
| Scope | One generated response | One model response; cross-step policy may span calls | Records used between calls, sessions, and runs |
| Schema role | Defines output fields, types, and allowed values | Describes evidence, intermediate fields, and candidate decision | Defines stored records, relations, and lifecycle |
| Enforcement | Constrained decoding blocks schema-invalid output | Shape only; separate calls, validators, and policy enforce dependencies and order | Application validation, database constraints, and conflict rules enforce lifecycle |
| Lifetime | Current call unless the application stores the object | Reasoning trace is usually discarded after the decision | Persists until updated, expired, or deleted |
| Failure mode | Valid shape with the wrong meaning | Fields are present, but reasoning or dependency handling may still be wrong | Stale, polluted, unscoped, or unauditable state |
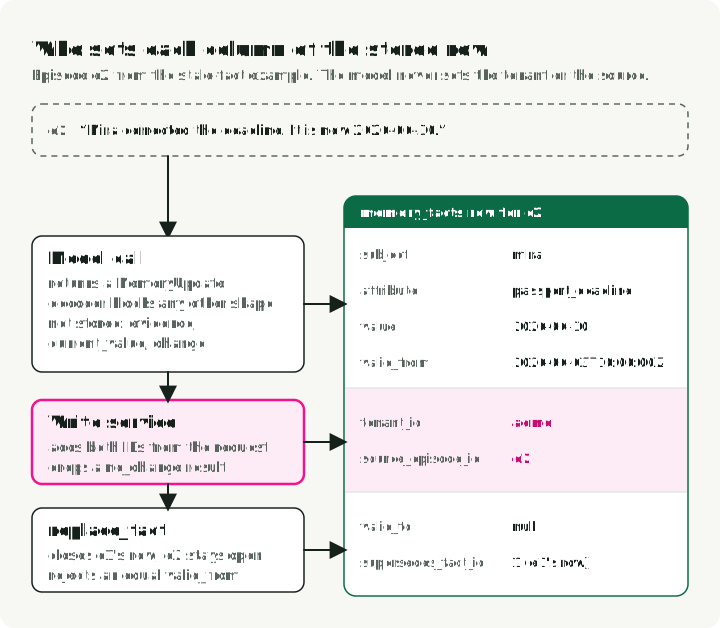
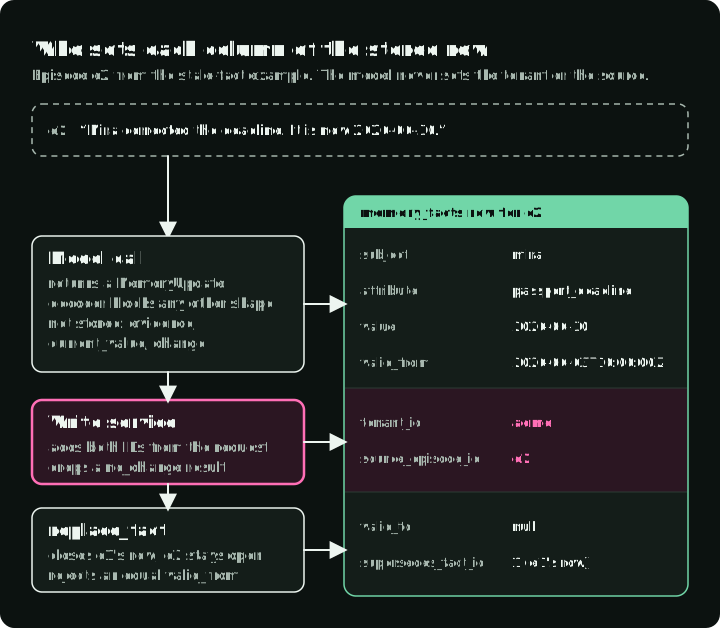
The diagram follows the correction from the example below into one stored row and shows who sets each column: the model, the write service from the request, or replace_fact.
The following schema defines the object passed from extraction to the SGAM write service. It requires Pydantic. The application puts the currently stored value into the prompt, so the model can compare it with the new evidence:
from datetime import datetime
from typing import Literal

from pydantic import BaseModel, Field

class MemoryUpdate(BaseModel):
    evidence: str = Field(description="Exact quote from the episode")
    subject: str = Field(description="Normalized entity ID, e.g. mira")
    attribute: str = Field(description="Property being updated")
    current_value: str | None = Field(description="Stored value shown in the prompt")
    change: Literal["new", "update", "no_change"]
    value: str | None = Field(description="New value; None when change is no_change")
    valid_from: datetime = Field(description="When the new value starts to apply")
The write service drops no_change results, adds tenant_id and source_episode_id from the request, and passes the rest to replace_fact in the example below. The model never chooses the tenant or the source episode.
Write and read paths have different jobs
Only the write path changes stored state. The read path selects records for the current request.
The ingestion flow is the write path:
- Capture a raw episode from messages, tool results, or business events. Record its tenant and retention class.
- Extract typed candidates with structured output.
- Validate the payload with Pydantic or the schema layer your stack already uses, and reject malformed writes.
- Resolve conflicts before insert: decide whether the new record supersedes an old one, and close the stale fact.
- Keep a source pointer to the raw episode, tool result, file, ticket, or user confirmation that produced the record.
- Commit the record to the SGAM store with its
schema_version, instead of leaving the version only in application code.
The request flow is the read path:
- Start with the user question.
- Decide whether the question needs current state or point-in-time state.
- Filter by tenant, memory type, subject, attribute, and validity window.
- Add vector or graph expansion only if the exact state lookup is not enough. Use it for supporting evidence, related entities, and examples, not as the authority for current facts.
- Assemble the smallest cited context for the model.
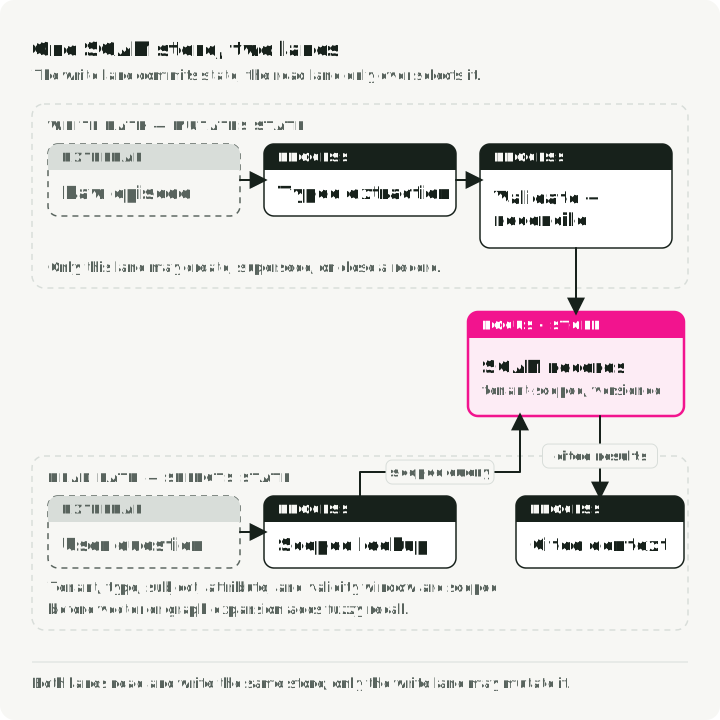
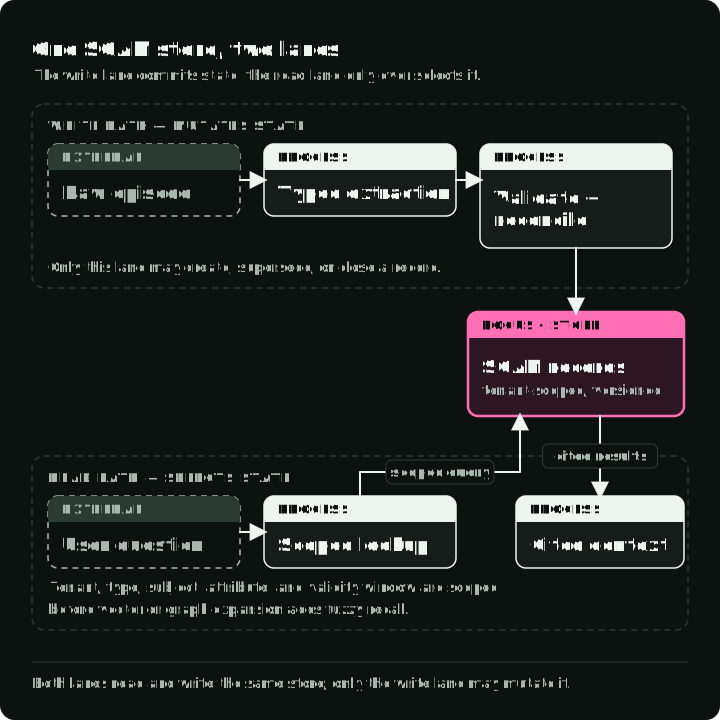
Read that diagram from top to bottom. The write path closes e1 and inserts e2 in one store. The read path picks a current or point-in-time filter, then selects rows from that same store.
What belongs in a memory schema
A minimal SGAM record needs more than text. Each field answers one of the questions from the first section or does one job in the lifecycle:
| Field | Question it answers or job it does |
|---|---|
tenant_id | Which tenant does it belong to? Every read and write filters on it. |
memory_id | A stable ID that other records and deletion jobs point to. |
subject, attribute | The key: which entity and which property, such as mira and passport_deadline. |
value | The stored value. |
memory_type | The kind of memory: semantic (stable facts and profiles), episodic (past events and traces), or procedural (instructions and prompt rules), as LangGraph describes them. |
schema_version | Which schema wrote the record, so a migration can find and convert old records. |
valid_from, valid_to | What is true now? valid_from <= now and (valid_to is null or now < valid_to). What was true on June 2? The interval contains that time. |
supersedes_memory_id | Which older fact did this fact replace? |
source_episode_id | Who said it? It points to the raw episode. |
confidence | A score the write service compares with a threshold: promote the candidate to current state, or ask the user to confirm it. |
retention_policy | Can I delete or expire it? It tells deletion jobs what else they must remove. |
With these fields, a new passport deadline can close the previous deadline without erasing history. The same table can answer current and point-in-time queries, then trace the result to its source episode.
Use RAG to retrieve documents and SGAM to maintain mutable state. Vector search still belongs in the system for fuzzy recall, clustering, and expansion. The current value of mira.passport_deadline should come from a scoped memory record rather than whichever chunk happened to rank first.
A stale-fact example
Consider a synthetic two-episode trace represented as a DM baseline and an SGAM ledger:
e1: Mira prefers concise answers. Her passport deadline is 2026-07-15.
e2: Mira corrected the deadline. It is now 2026-06-30.
A DM baseline keeps both episodes as free text, so text search can return e1 because it contains the right words. SGAM extracts a typed fact from each episode, keyed by tenant, subject, and attribute. It should return e2 as current state and keep e1 for a historical query.
The script below answers two of the earlier questions: what is true now, and what was true on June 2. Look at replace_fact: it closes the old row instead of deleting it, and it records which row the new one replaces. The caller must normalize every stored and query timestamp to one UTC string format with fixed second precision: YYYY-MM-DDTHH:MM:SSZ. SQLite compares these TEXT values lexically, so mixed offsets or precision can put facts in the wrong order. Each row is valid from valid_from up to, but not including, valid_to. The table rejects invalid intervals and has a partial unique index for one open fact per tenant, subject, and attribute. replace_fact owns one transaction and starts it with BEGIN IMMEDIATE before reading any rows. Call it on a connection with no active transaction. SQLite serializes concurrent writers, so callers should retry the whole transaction after a lock or uniqueness error. A keyword match stands in for vector search at the end. Any ranking that does not know about the correction can return e1.
import sqlite3
from dataclasses import dataclass

@dataclass(frozen=True)
class MemoryFact:
    tenant_id: str
    subject: str
    attribute: str
    value: str
    valid_from: str
    source_episode_id: str

def open_db() -> sqlite3.Connection:
    db = sqlite3.connect(":memory:")
    db.row_factory = sqlite3.Row
    db.executescript(
        """
        create table memory_facts (
            fact_id integer primary key,
            tenant_id text not null,
            subject text not null,
            attribute text not null,
            value text not null,
            valid_from text not null,
            valid_to text,
            supersedes_fact_id integer references memory_facts (fact_id),
            source_episode_id text not null,
            check (valid_to is null or valid_from < valid_to)
        );
        create unique index one_open_fact
        on memory_facts (tenant_id, subject, attribute)
        where valid_to is null;
        """
    )
    return db

def replace_fact(db: sqlite3.Connection, fact: MemoryFact) -> None:
    with db:
        db.execute("BEGIN IMMEDIATE")
        exact = db.execute(
            """
            select fact_id
            from memory_facts
            where tenant_id = ? and subject = ? and attribute = ? and valid_from = ?
            """,
            (fact.tenant_id, fact.subject, fact.attribute, fact.valid_from),
        ).fetchone()
        if exact:
            raise ValueError("equal valid_from requires an application conflict policy")

        containing = db.execute(
            """
            select fact_id, valid_to
            from memory_facts
            where tenant_id = ?
              and subject = ?
              and attribute = ?
              and valid_from < ?
              and (valid_to is null or valid_to > ?)
            limit 1
            """,
            (
                fact.tenant_id,
                fact.subject,
                fact.attribute,
                fact.valid_from,
                fact.valid_from,
            ),
        ).fetchone()
        if containing:
            db.execute(
                "update memory_facts set valid_to = ? where fact_id = ?",
                (fact.valid_from, containing["fact_id"]),
            )
            successor_boundary = containing["valid_to"]
        else:
            successor = db.execute(
                """
                select valid_from
                from memory_facts
                where tenant_id = ? and subject = ? and attribute = ? and valid_from > ?
                order by valid_from
                limit 1
                """,
                (fact.tenant_id, fact.subject, fact.attribute, fact.valid_from),
            ).fetchone()
            successor_boundary = successor["valid_from"] if successor else None

        db.execute(
            """
            insert into memory_facts
                (tenant_id, subject, attribute, value, valid_from, valid_to,
                 supersedes_fact_id, source_episode_id)
            values (?, ?, ?, ?, ?, ?, ?, ?)
            """,
            (
                fact.tenant_id,
                fact.subject,
                fact.attribute,
                fact.value,
                fact.valid_from,
                successor_boundary,
                containing["fact_id"] if containing else None,
                fact.source_episode_id,
            ),
        )

def fact_at(
    db: sqlite3.Connection, tenant_id: str, subject: str, attribute: str, timestamp: str
) -> sqlite3.Row | None:
    return db.execute(
        """
        select fact_id, value, valid_from, supersedes_fact_id, source_episode_id
        from memory_facts
        where tenant_id = ?
          and subject = ?
          and attribute = ?
          and valid_from <= ?
          and (valid_to is null or valid_to > ?)
        limit 1
        """,
        (tenant_id, subject, attribute, timestamp, timestamp),
    ).fetchone()

KEY = ("acme", "mira", "passport_deadline")

db = open_db()
replace_fact(db, MemoryFact(*KEY, "2026-07-15", "2026-06-01T09:00:00Z", "e1"))
replace_fact(db, MemoryFact(*KEY, "2026-06-30", "2026-06-03T10:00:00Z", "e2"))
current = fact_at(db, *KEY, "2026-06-04T00:00:00Z")
assert (current["value"], current["source_episode_id"]) == ("2026-06-30", "e2")

historical = fact_at(db, *KEY, "2026-06-02T00:00:00Z")
assert (historical["value"], historical["source_episode_id"]) == ("2026-07-15", "e1")
assert current["supersedes_fact_id"] == historical["fact_id"]

# A delayed extraction predates e1. It ends at e1's existing boundary,
# rather than closing e2, which remains current.
replace_fact(db, MemoryFact(*KEY, "2026-08-01", "2026-05-30T08:00:00Z", "e0"))
delayed = fact_at(db, *KEY, "2026-05-31T00:00:00Z")
assert (delayed["value"], delayed["source_episode_id"]) == ("2026-08-01", "e0")
current = fact_at(db, *KEY, "2026-06-04T00:00:00Z")
assert (current["value"], current["source_episode_id"]) == ("2026-06-30", "e2")
intervals = db.execute("select valid_from, valid_to from memory_facts").fetchall()
assert all(row["valid_to"] is None or row["valid_from"] < row["valid_to"] for row in intervals)

episodes = (
    "e1: Mira prefers concise answers. Her passport deadline is 2026-07-15.",
    "e2: Mira corrected the deadline. It is now 2026-06-30.",
)
naive_match = next(episode for episode in episodes if "passport deadline" in episode)
assert naive_match.startswith("e1:")

print("Naive text memory:")
print(f"  returned episode: {naive_match}")
print()
print("SGAM current state:")
print(f"  mira.passport_deadline = {current['value']}")
print(f"  valid_from={current['valid_from']}, source={current['source_episode_id']}")
print()
print("SGAM point-in-time state:")
print(f"  on 2026-06-02, mira.passport_deadline = {historical['value']}")
Running the script prints:
Naive text memory:
  returned episode: e1: Mira prefers concise answers. Her passport deadline is 2026-07-15.

SGAM current state:
  mira.passport_deadline = 2026-06-30
  valid_from=2026-06-03T10:00:00Z, source=e2

SGAM point-in-time state:
  on 2026-06-02, mira.passport_deadline = 2026-07-15
replace_fact first rejects an equal valid_from: that conflict needs an application policy, such as source precedence or a user-confirmed revision, rather than a silent overwrite. Otherwise it finds the interval containing the incoming timestamp. If it finds one, it closes that predecessor at the incoming boundary, gives the inserted row the predecessor’s former end, and records the predecessor in supersedes_fact_id. If the timestamp is before every stored interval, it uses the next interval’s valid_from as the new row’s end. Thus a delayed fact before e1 becomes [2026-05-30, 2026-06-01) and leaves e1 and current e2 intact. The partial unique index is the database guard for one open row. DM has no equivalent update step, so the old text can still outrank the correction.
The timeline shows the rows after each replace_fact call in the script, then the three reads. Look at step 2, where e2 closes e1, and at step 3, where the delayed e0 ends where e1 starts.
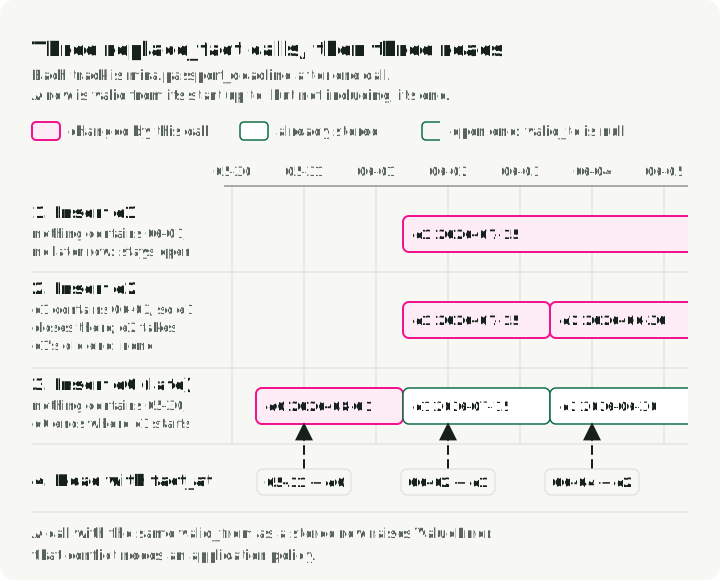
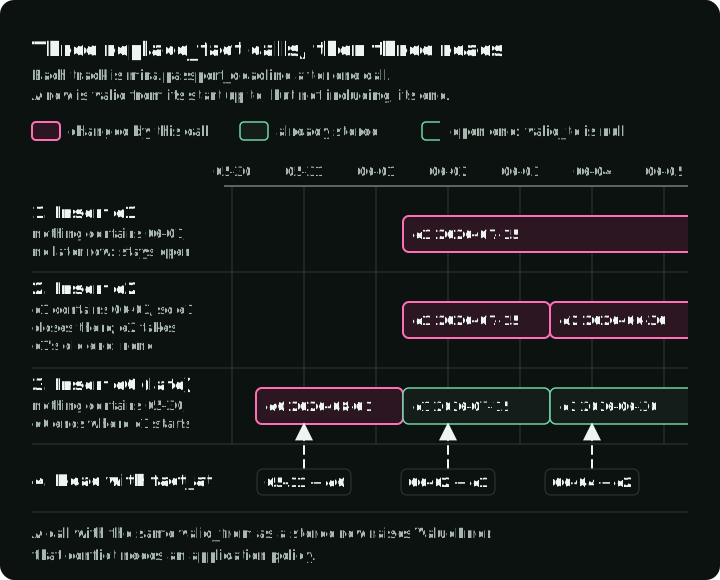
In production, pair this transaction with structured extraction on the write path. The database transaction updates temporal validity. The model extracts a candidate fact but doesn’t decide which stored row remains current.
Storage choices follow the retrieval pattern
Projects use several names for parts of this pattern: memory stores, context graphs, profiles, long-term stores, graph RAG, and stateful agents.
| Tool or framework | Main storage layer | Temporal state mechanism | Schema mechanism | Use when |
|---|---|---|---|---|
| Graphiti | Neo4j, FalkorDB, and Amazon Neptune; Kuzu is deprecated | Fact validity intervals plus source-episode provenance | Pydantic entity and edge types, temporal edges, provenance | You need validity intervals and graph traversal, and you will run the graph database |
| Zep | Proprietary Context Graph Engine | Managed temporal Context Graphs that retain changing facts | Default and custom entity and edge types | You want the same temporal graph model as a managed service |
| LangGraph / LangMem | LangGraph stores, Postgres-backed stores | Application-owned timestamps and fields in store records | JSON stores plus Pydantic profile or collection extraction | You already use LangGraph and accept owning timestamps and conflict rules |
| Mem0 | Managed stack, Valkey / Redis / vector backends in OSS setups | Memory updates; temporal policy remains application-owned | Memory types, custom categories, extraction prompts | You want managed add, search, update, and delete, scoped by user, agent, app, or run, and you will own temporal policy |
| Letta / MemGPT | Database-backed agent state and memory blocks | Editable blocks without field-level validity intervals | Editable labeled memory blocks | The agent edits its own memory blocks, or several agents need one shared block that all of them see |
| Cognee | Graph plus vector and relational backends | History depends on the ontology and selected backend | Ontology-oriented extraction and validation | You validate extraction against a domain ontology |
| LlamaIndex property graph | Property graph stores plus vector stores | Time fields depend on the graph schema and store | SchemaLLMPathExtractor with allowed entities and relations | You extract a property graph from documents or traces |
LangGraph separates thread checkpoints, which resume one conversation, from cross-thread stores, which hold data that later threads read. The Zep paper reports gains on Deep Memory Retrieval and LongMemEval, and the Mem0 paper reports gains on LoCoMo. Each vendor wrote its own paper, so read the numbers as vendor results, not guarantees for your workload.
Start with the data model. If exact fact lookup is the main operation, a relational table with JSON payloads, validity columns, tenant indexes, and a vector sidecar is usually enough. Add a graph when the product’s queries follow relationships.
Build the write path before the graph
First decide what the product is allowed to remember. The graph-versus-vector choice comes later.
A support agent might remember account tier, open cases, and durable contact preferences. It shouldn’t promote every frustrated aside into profile state. A coding agent might remember repo conventions and unresolved tasks. It shouldn’t keep a private note forever because that note happened to be retrieved once.
The first SGAM store can be a relational table with a JSON column and a few indexes, written by the six-step write path above. A graph becomes useful when the product needs to traverse relationships such as customer-to-account, account-to-policy, task-to-artifact, or project-to-decision.
Hot path and background writes
Immediate extraction is worth it when the next turn depends on the new memory. If the user says “remember that I prefer short answers,” the system should not need a nightly job before it behaves differently.
Most turns don’t need an immediate write. Save the raw episode with tenant, session, and tool metadata, then let a background worker extract candidates later. With recurrence-based consolidation, the worker buffers weak signals and promotes a fact only after similar evidence repeats or the user confirms it. This adds freshness lag. That is acceptable for “user often asks for CSV exports” and risky for “customer changed the delivery address.”
Treat schema migration as a product change because it alters what the agent can recall, cite, or delete. It can also change which historical facts count as current. Plan migration scripts, backfills, dual-read windows, and deletion behavior in the same release.
When SGAM is worth the complexity
Use SGAM when facts can change over time:
- user preferences that can be updated or revoked
- customer or account facts with audit requirements
- task state for long-running assistants
- coding-agent project memory
- multi-agent shared state
- compliance notes where provenance matters
- temporal questions such as “what did we believe before the migration?”
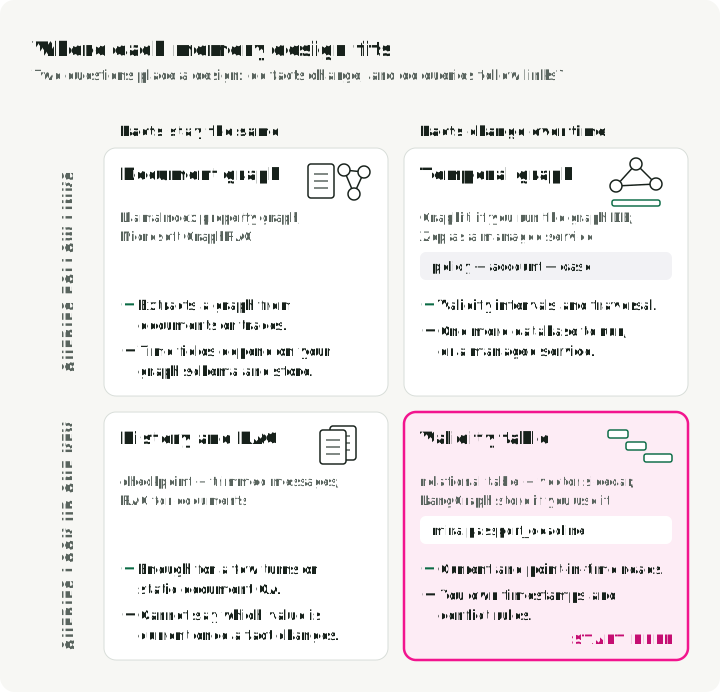
SGAM is overkill when memory is short-lived, exploratory, or cheap to recompute. If the agent only needs a few turns of continuity, a checkpoint and trimmed message history are enough. Static document QA may need only RAG. And if the domain is so unsettled that the schema changes every day, typed memory will slow the team down.
The grid places each design by two questions: do your facts change, and do your queries follow links between records?
Evaluation checklist
Evaluate the memory lifecycle as well as the final answer. A system can produce a plausible response after it wrote the wrong fact, retrieved a stale one, or crossed a tenant boundary.
I use the same stage-by-stage split as my RAG evaluation article. Measure the stage where a failure can happen rather than limiting evaluation to the generated text. The trace discipline from the agent evaluation article also applies because a memory bug often appears in the run history before it reaches the answer.
I would test SGAM with replay. Feed a fixed sequence of episodes into the memory writer and inspect the ledger after each meaningful turn. Then ask current-state and point-in-time questions against the resulting store.
| Layer | Failure you are looking for | Measures |
|---|---|---|
| Write extraction | The agent missed a fact, invented one, or produced invalid shape | Schema-valid write rate, extraction precision/recall, source episode coverage |
| Conflict handling | A stale fact stayed current or a valid old fact was overwritten | Supersession correctness, duplicate rate, stale-fact invalidation correctness |
| Isolation and policy | Memory leaked between users or survived past its policy window | Tenant isolation failures, deletion correctness, retention compliance |
| Read retrieval | The right record exists but the reader did not fetch it | Current-state accuracy, point-in-time accuracy, recall@k over memory records |
| Answer grounding | The answer used memory without support or cited the wrong source | Claim support against source episodes, citation accuracy, conflict-resolution correctness |
| Operations | The memory path is too slow, too stale, or too expensive | p95 write latency, freshness lag, read latency, cost per query |
Benchmarks such as LoCoMo, LongMemEval, and ATM-Bench provide public test cases. They don’t replace a domain test suite. A coding assistant, customer support bot, and compliance copilot need different schemas, filters, retention rules, and failure tests.
From traces to better memory runs an improvement loop on a memory tool that stores facts with an owner, a source event, and a validity interval, following these rules.
Caveats
SGAM is my label for a pattern, not a standard. The tools in the table above use other names for parts of it: memory stores, temporal context graphs, memory blocks, and knowledge graphs. Microsoft GraphRAG frames a related part of the problem as graph-based retrieval over documents.
A user profile, an episode log, a document graph, and an agent-editable memory block solve different retrieval and update problems. I reserve SGAM for durable memory that represents current application state and therefore needs schema, validity, provenance, conflict handling, retention, and migration.
Typed memory can still be wrong. A schema makes bad writes easier to inspect; it does not make them trustworthy. You still need source trust, user confirmation for sensitive facts, conflict policy, deletion, and monitoring.
References
- According to Me: Long-Term Personalized Referential Memory QA - Mei et al. paper introducing ATM-Bench and Schema-Guided Memory.
- Towards Scalable Multi-Domain Conversational Agents: The Schema-Guided Dialogue Dataset - Rastogi et al. paper on the SGD dataset.
- Evaluating Very Long-Term Conversational Memory of LLM Agents - Maharana et al. paper introducing LoCoMo.
- LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory - Wu et al. benchmark for long-term memory abilities.
- Graphiti: Build Temporal Context Graphs for AI Agents
- Zep: A Temporal Knowledge Graph Architecture for Agent Memory
- Mem0 Platform Overview
- Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
- LangGraph Memory Overview
- LangGraph Persistence
- LangMem documentation
- Letta: Introduction to Stateful Agents
- Letta: Shared memory
- Microsoft GraphRAG documentation
- LlamaIndex: Using a Property Graph Index
- Cognee Documentation
- Pydantic model validation docs
- Python sqlite3 documentation