Harness Engineering for AI Agents: Verifying Completion

An agent can finish its turn while the work is still incomplete. This article is for engineers building or reviewing coding agents who need to decide when to accept a result, retry an uncertain operation, or resume work in another session. It also shows how to measure whether an extra harness component improves those outcomes enough to justify its cost.
The harness is the application code around the model’s reasoning loop. It supplies context, checks proposed actions, records what happened, and decides whether the evidence is enough to finish. The runtime executes accepted actions and keeps the session, sandbox, and checkpoint available. The earlier articles explain the reasoning loop, memory, tools, and permissions. Here the question is what the harness does after the model proposes an action or says “done.”
The store and payment examples below are fictional teaching cases. The companion lab is a deterministic simulation; it does not measure a live coding agent.
What counts as done
Suppose a coding agent is asked to lower the threshold for a 10% automatic discount from $100 to $75 in a fictional store repository. It changes src/checkout.py. An $80 cart should now receive an $8 discount. The task has two required checks:
pytest tests/test_checkout.pychecks the calculation.pnpm playwright test tests/checkout_discount.spec.tschecks the visible checkout result in a seeded local store.
A plausible final answer is not one of those checks. The harness should accept only a candidate whose complete tested snapshot is identified and whose two required checks passed on that same snapshot. A clean commit can identify it; otherwise use a digest or manifest that includes relevant untracked files. Keep the tests outside the agent’s writable scope, or independently approve changes to them before grading.
This is where the model, harness, and runtime have different jobs. Implementations may merge several of them into one process, but their failure boundaries stay different:
| Component | Job | Coding-agent example |
|---|---|---|
| Model | Proposes text, a tool call, or a final answer | Suggests an edit to src/checkout.py |
| Reasoning loop | Chooses the next move from the available context | Inspect, edit, test, inspect again |
| Harness | Supplies context, validates and authorizes proposals, dispatches accepted calls, records results, checks completion | Allows edits under src/ and requires both named tests |
| Runtime | Executes accepted calls and keeps state alive outside the worker process | Session log, sandbox, checkpoint store, trace backend |
OpenAI’s Codex loop walkthrough describes the cycle: the harness assembles a prompt, asks the model for the next action, sends an accepted tool call to the runtime, appends the result, and asks again until it accepts the result or hands control back to the user. For the discount change, one pass looks like this:
- The context builder supplies the task, repository instructions, relevant files, prior tool results, and the current plan.
- The model proposes an
edit_filecall with a path and replacement text. - The tool boundary validates the arguments, checks the path against the allowed scope, and asks for approval if the operation needs it.
- The runtime applies the edit in the sandbox and returns a structured result.
- The harness runs
pytest tests/test_checkout.py, thenpnpm playwright test tests/checkout_discount.spec.ts, and reads both exit codes. - A failed check becomes new context for the next model turn; two passing checks make the change a completion candidate.
- The harness durably records the commands, exit codes, tested snapshot, grader, and environment versions; a trace can link to that record.
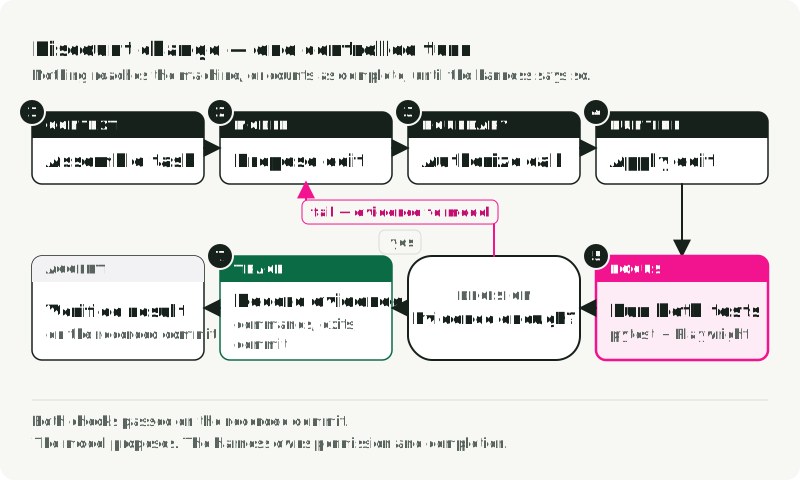
After step 2, no file has changed. The harness can still reject ../../secrets.env, require approval for a destructive command, or stop a run that has used its budget. After step 5, the harness reads the exit codes itself, so the model cannot mark its own edit as passing.
A completion record for this task needs the candidate snapshot, both commands and exit codes, and the test environment and grader versions. It should be durable and outside the candidate’s control. A trace can link the proposal, approved call, runtime result, and acceptance record for diagnosis. A trace alone is not the acceptance decision.
A trace does not necessarily contain the request either. It may record the source document or a middleware event without showing what the assembled request finally held. If you need to establish what the model received, capture it at the last point before the call leaves, after every transformation.
OpenAI’s harness-engineering case study describes a bootable application per worktree plus browser access, logs, metrics, and traces. That setup made a user-journey latency objective inspectable by the agent. It illustrates the prerequisite behind an acceptance rule: the relevant application and signals must be available in the test environment. Lopopolo, the author of that case study, keeps a field guide for harness engineering with the same two levers: hold the model fixed, and engineer the context and tools around it. An organization’s quality bar, procedures, and approval rules sit outside what a general model knows; the harness supplies them as repository instructions, permission rules, and acceptance checks.
Consider three superficially similar outcomes:
| Evidence at the end of the run | Harness decision | Why |
|---|---|---|
| Unit test passes; browser result is missing | Continue or stop as incomplete | One required check has no result |
| Both tests pass, then the agent edits a file | Run both checks again | The recorded passes belong to an older snapshot |
| Both tests pass on the same identified snapshot | Eligible for acceptance | The required evidence matches the candidate |
“Eligible” leaves room for a human approval or another required rule; it does not let the model certify its own work. A fresh-context evaluator can review a visual result against a rubric when an exit code cannot express the criterion. Compare that evaluator with human reviews before allowing it to decide completion. It cannot replace a required deterministic check.
For the research agent in this series, a proposed deterministic completion rule would check the report schema and confirm that the requested tickers appear. Those checks cannot establish that the analysis is factually sound; that still needs source review. Anthropic’s evaluation guidance recommends stable environments and thorough tests for coding tasks, with human calibration for model graders.
Where each rule is enforced
The requirement that tests/checkout_discount.spec.ts passes belongs in deterministic code, not in the prompt. A prompt can remind the model to run the test. It cannot stop the model from declaring success without evidence. Other rules fit other places:
| Put the rule in | Good fit | Example |
|---|---|---|
| Prompt or skill | Search order, coding conventions, and plan format | Read AGENTS.md before editing checkout code |
| Tool boundary | Argument validation, allowed paths, approvals, and tool access | Permit writes only under src/ |
| Deterministic code | Budgets, timeouts, retries, test exit codes, and release requirements | Keep the run open while the Playwright test fails |
| Fresh-context evaluator | Visual review or criteria that need judgment | Compare a generated diagram with a written rubric |
The earlier parts of this series each decide one thing inside that walkthrough:
| Earlier part | What it decides for this turn | Where it acts in the walkthrough |
|---|---|---|
| Part 2 — memory | Which prior state enters the prompt | Step 1, the context builder |
| Part 3 — tool use | Which actions exist, and what a validated result looks like | Step 3’s validation and step 4’s result |
| Part 4 — security | Whether this specific call may run now | Step 3, the path check and approval |
| Part 6 — this article | Whether the resulting evidence ends the run | Steps 5 to 7, the acceptance checks |
The table maps responsibilities, not execution order. Parts 3 and 4 share step 3: the same harness code that rejects a malformed argument also rejects a call that is permitted but not yet approved. If validation and authorization run in separate services, pass the validated arguments across that boundary so the authorization decision applies to the call that will execute.
Treat a timeout as an unknown outcome
The discount edit is local and its tests can be rerun. A payment migration in the same fictional store introduces a different problem. Suppose the agent calls create_test_order against a staging service, and the call times out. The service may have created the order even though the harness never received its response. Retrying blindly can create a second order.
The action’s name or a model-generated tool-call ID is not enough to recover it. Before dispatch, persist an application-owned operation ID with the approved arguments. The service must deduplicate retries for that ID, or provide a status lookup that can reconcile the outcome. Reuse the same ID for the same intended order after a restart; a changed order request needs a new decision. AWS’s idempotent API guidance describes the client identifier and the server-side atomicity needed to make this safe. Check how long the provider keeps keys: Stripe’s contract, for example, permits pruning them after at least 24 hours, so a later retry needs reconciliation instead of a resend.
The figure follows one timed-out create_test_order call twice: once resent blindly, and once resent with the stored operation ID.
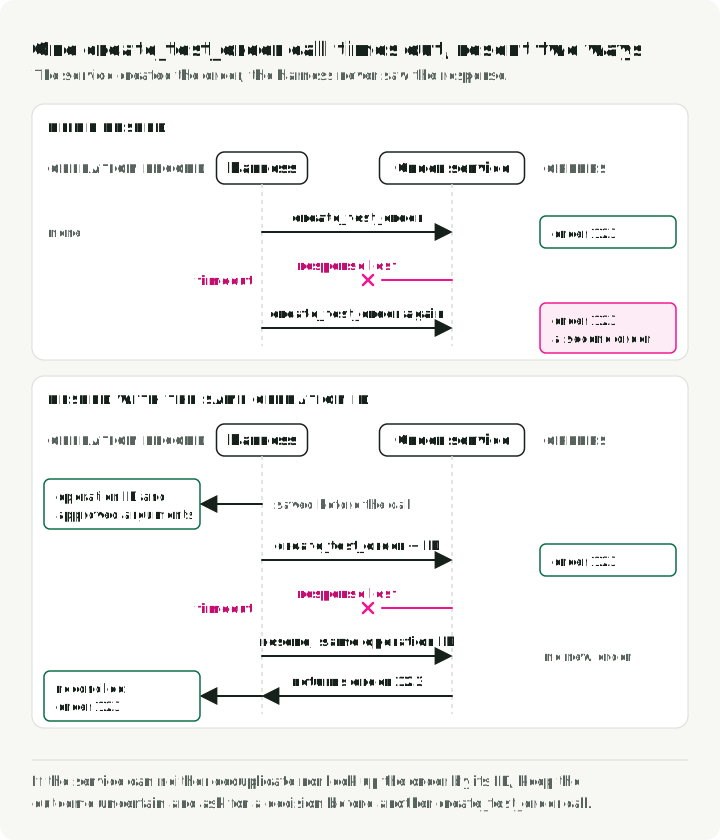
The harness can make these decisions without asking the model only if each tool has an explicit contract. For create_test_order, that contract has:
- validated arguments, so malformed input is rejected before execution;
- a structured result such as
{ "order_id": "123", "created": true }, so later checks do not parse free-form text; - an effect category: whether the call only reads, or changes a file, record, or external service, and whether repeating it is safe;
- a timeout and retry policy, so a lost response does not start an unlimited sequence of calls;
- a permission rule: reading order status may run automatically, while creating an order may need confirmation.
| Result observed by the harness | Next action |
|---|---|
A read-only get_order_status call returns 503 | Retry within a limit if that lookup is safe to repeat |
create_test_order times out; lookup finds the order under its operation ID | Use the existing order and record the reconciled result |
create_test_order times out; the service cannot deduplicate or check status | Leave the outcome uncertain and request a decision before another creation |
That last state must survive a worker crash. Calling it “failed” would be false: the order might exist. The durable operation record needs the approved payload, operation ID, dispatch status, server result or status lookup, and any approval. The trace helps find that record; the transcript only shows what the model saw.
A tool description helps the model choose an action. It does not grant permission or prove that a retry is safe. If the order service is exposed through MCP, the client must still apply its own validation and trust policy, and the server must enforce access controls. The MCP tools specification says clients must treat tool behavior annotations as untrusted unless they come from a trusted server. A server describing create_test_order as read-only cannot make it so. The specification does not prescribe one trust setting, so write an explicit policy for your deployment that says which server metadata may influence permission or retry decisions.
MCP also has a standard way to keep a handle on a long-running call. With the official Tasks extension, a server can answer tools/call with a task handle instead of a final result. The client then polls with tasks/get or stops the work with tasks/cancel. The Tasks specification says clients should persist task IDs so polling can resume after a crash, so store the task ID in the same operation record. A completed task does not mean the tool succeeded: a tool result with isError: true still completes the task, and only a protocol error moves it to failed. Client and server negotiate support for each request, so confirm that both sides implement it before relying on it.
Hand progress to the next session
Now the fictional agent must migrate checkout from payment adapter v1 to v2. It has changed the handler and client, started a local payment sandbox, and left tests/payment_migration.spec.ts failing. The task outlasts one model session. A summary of the old conversation may say the sandbox is running even after the process has died.
The next session needs three different kinds of state:
| State | What the next session must check |
|---|---|
| Conversation | The request, decisions, and relevant tool results |
| Workspace and runtime | Current files, branch, processes, and test environment |
| Task progress | Completed checks, pending approval or uncertain write, and next action |
Compaction replaces older messages with a shorter summary so the current session can continue. A progress handoff is document memory for the next session. If the old conversation carries stale assumptions, the harness can start a fresh session with the handoff and the current workspace; replacing a crashed worker and restoring its processes is a separate runtime job.
A checkpoint can preserve execution state, but it does not prove that an external payment operation committed or that a process is still alive. A progress handoff helps when the next model context lacks the usable task status. Record the branch, changed files, last command and result, pending operation IDs, and next unresolved step. On resume, verify those claims against the live workspace and service before acting. Anthropic’s long-running coding-agent experiments used git history and a progress file to help later sessions recover work. Anthropic’s later harness-design report notes that handoffs add orchestration, tokens, and wall time.
The handoff should be conditional. A small edit that finishes in one session needs none. Even a long task may not need another file if its checkpoint already contains the required progress and the next session can use it. Check whether a resumed session repeats completed work, misses a pending write, or acts on a stale environment. Fix the missing state rather than adding a summary by default.
Diagnose the failure before adding a component
The three cases above produce different traces: a missing acceptance test, an uncertain external write, and repeated work after resume. Their fixes belong in different places. A browser result missing from the acceptance record calls for a required completion check. An uncertain order calls for server-side deduplication or reconciliation. A repeated edit after a fresh session calls for usable progress state.
For the next run, record the task and harness version, proposed action, approval, tool result, tested snapshot, acceptance result, latency, and cost. Record the input token counts separately from the billed input cost, including cached reads: two harnesses that behave identically can bill differently depending on how each assembles its request and whether the provider’s cache was warm. Keep secrets and unnecessary personal data out of traces. Link external operation records by ID, since a client-side timeout cannot reveal what the server did. When a failure recurs, write a regression case that reproduces it. AI Agent Evaluation in Production develops that trace-to-test process.
Each repeated symptom suggests a small change and a measure that would show whether it helped:
| Repeated symptom | Small change to try | What to measure |
|---|---|---|
| Read-only lookups fail transiently | Bounded retry with backoff | Recovery rate, extra calls, wall time |
| Resumed sessions repeat completed work | Structured progress handoff | Duplicate tool actions after resume |
| Required tests are missing at completion | Reject completion until every required check passes | Tasks accepted without all required checks |
| Visual defects survive deterministic checks | Fresh-context evaluator with a rubric | Defects found, false rejections, review time |
| The agent edits outside its scope | Narrower tool permission | Blocked calls and manual overrides |
| Recalled memory crowds out the current task | Cap recalled facts; rank before injecting | Tokens spent on recall, tasks completed, cost |
| A stated rule or status never reaches the model | Capture the assembled request before the call leaves | Requests missing the rule; rounds until it appears again |
Before adding a retry policy, handoff, or evaluator, state the failure it should change and the metric that would show improvement. Count the cost as well: more accepted tasks are not useful if the extra calls double review time or create duplicate orders. Authorization, isolation, privacy rules, and mandatory acceptance checks are requirements; a small success benchmark is no reason to remove them. Test those constraints with explicit forbidden cases.
Measure one optional change at a time
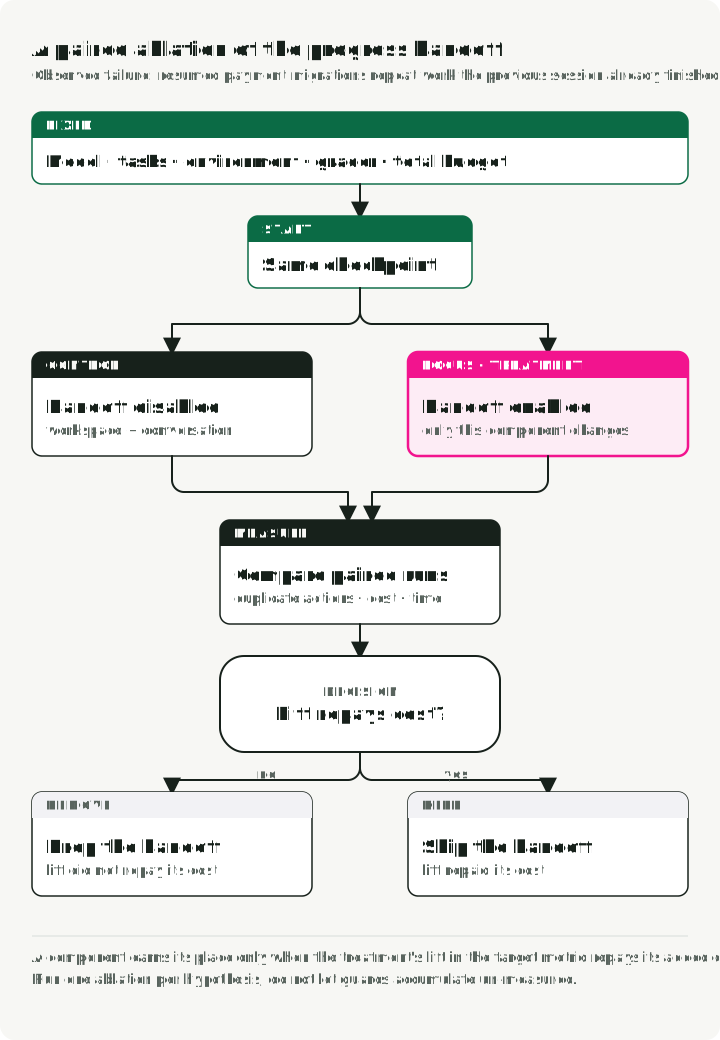
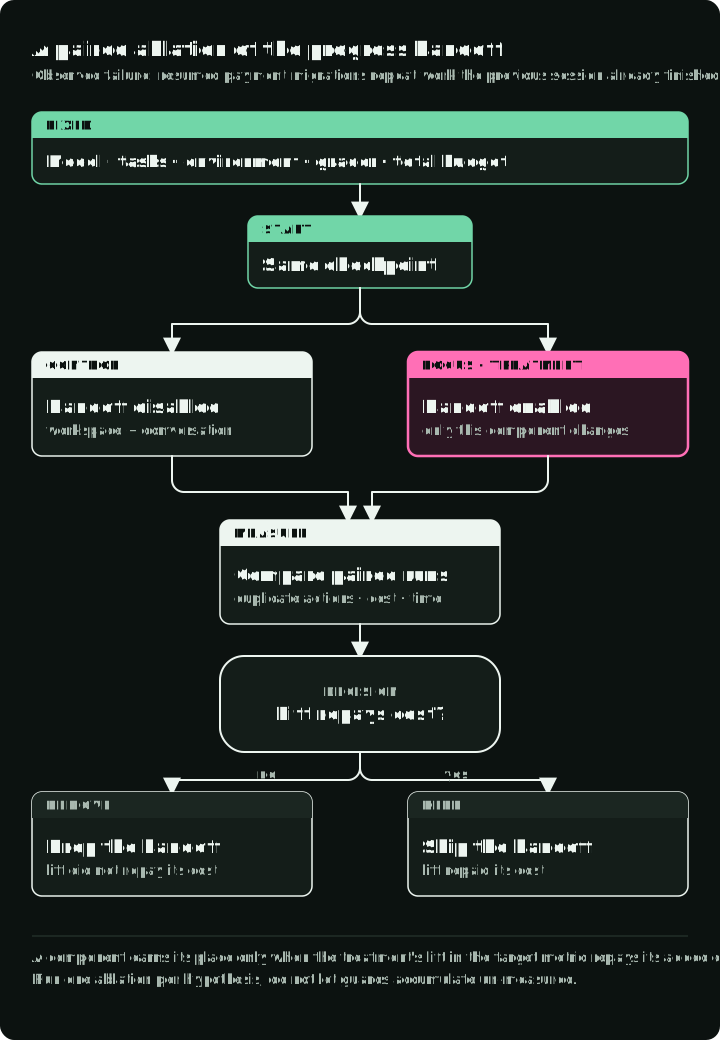
An ablation compares a harness with and without one component while holding the rest of the experiment fixed. Use this protocol:
- Freeze the model version and provider endpoint, task instances, environment and its compute limits, grader, and prompts outside the component under test. Resource limits alone can change an agent benchmark score; the evals article covers Anthropic’s measurement.
- Give both variants the same total token, time, and dollar budget.
- Choose the number of trials or the stopping rule before running the comparison.
- Run the same task instances in both variants, and repeat each task because model output varies.
- Report the mean with its spread or confidence interval.
- Count every started trial, including timeouts, policy stops, harness crashes, and evaluator failures.
For the payment migration, the optional progress handoff is a candidate. Start each control–treatment pair from the same repository commit and seeded checkpoint, with the handoff as the only switch.
The primary measure could be duplicate tool actions after resume: an operation on an artifact that the previous session had already completed. Also report accepted tasks, escaped defects, wall time, model and evaluator cost, and review minutes. Choose the number of trials and stopping rule in advance, then report the variation rather than only the mean. If the handoff reduces duplicates but costs more than it saves, that is a useful negative result.
The SWE-agent paper gives a bounded example of interface ablation. With GPT-4 Turbo on the 300-task SWE-bench Lite split and a $4 per-task cap, it changed one interface feature at a time:
| Interface change | Resolved |
|---|---|
| Full SWE-agent interface (reference) | 18.0% |
| Editor without linting | 15.0% |
| Full file instead of a 100-line viewer | 12.7% |
| Full observation history instead of the last five | 15.0% |
These are results for that model and benchmark, not expected gains for this fictional store. What carries over is the method: test a named interface choice under a fixed setup, then report the conditions with the number.
Bundled comparisons are common, and they cannot name the change that helped. LangChain reports a Terminal-Bench 2.0 gain for deepagents-cli from 52.8% to 66.5% with the model fixed, after changing the system prompt, tools, and middleware together. OpenAI’s ARC-AGI-3 report shows the reverse risk: a score nearly tripled when the harness kept reasoning and used compaction, two API settings changed together. Record the API, reasoning retention, compaction policy, and budgets with the model ID; otherwise an apparent model regression may be a missing capability in the adapter.
Testing one change at a time also catches changes that look too small to matter. Anthropic’s April 2026 Claude Code postmortem reports that the API was not affected, yet three product-layer changes lowered quality: a lower default reasoning effort, a bug that cleared earlier reasoning on every turn after an idle session, and a system-prompt line limiting the text between tool calls. When Anthropic ablated that one line on a broader set of evaluations, one of them showed a 3% drop for both Opus 4.6 and Opus 4.7. A prompt line or a default setting is a harness change; test it like one.
Revalidate components when the model changes. Anthropic’s long-running application report is a qualitative case study: when Opus 4.6 shipped, the team removed harness components one at a time and found that evaluator calls became overhead on tasks the model now completed alone, while they still helped near its limit.
Include a provider safety stop in the failure suite: it should stop dispatch and go to review, not retry. Part 4 covers the details.
Try the comparison in the companion lab
The harness-demo project at commit 517353f3 makes the ablation rule runnable. Its twelve generic synthetic tasks, such as fix-parser-edge-case, split-large-module, and wire-browser-test, each declare a difficulty and four conditions: a flaky tool, lost progress, a missed implementation gap, and ambiguous completion. The simulator derives a fifth for difficult tasks that also need a progress file: without context_reset, compaction keeps stale assumptions. A pure function marks a task as passed when the selected configuration handles every applicable condition. There is no model, external tool, or real coding task. Its outcomes and token counts are simulated teaching data, not evidence that a five-component harness improves a live agent.
Clone the pinned revision and run the checks and simulation with uv installed:
git clone https://github.com/slavadubrov/harness-demo.git
cd harness-demo
git checkout 517353f3a47541d66099983170fe90812b6ef23b
make check
make run
make failures
make check runs Ruff and seven unit tests, including a test that rejects a comparison changing two components. make run prints a cumulative teaching matrix and five leave-one-component-out pairs. make failures names each simulated failure; the full configuration ends with all synthetic tasks pass.
| Component restored to the full configuration | Without it | With it |
|---|---|---|
| Retry policy | 8/12 | 12/12 |
| Progress handoff | 7/12 | 12/12 |
| Fresh evaluator | 8/12 | 12/12 |
| Fail-closed acceptance | 7/12 | 12/12 |
| Context reset | 10/12 | 12/12 |
The rows are deterministic consequences of the task flags and grader code. They are not estimates of an effect size in a live system. The earlier cumulative matrix adds several components in one transition and cannot identify which one caused its change.
The lab’s model.py guards against calling a bundled change an ablation: it compares every component field of a pair, and its regression test supplies an invalid pair with both retry and evaluator changed. This self-contained version of the guard runs on one valid progress-handoff pair:
from dataclasses import dataclass, fields

@dataclass(frozen=True)
class Config:
    progress_handoff: bool = False
    evaluator: bool = False
    retry_policy: bool = False
    fail_closed_acceptance: bool = False
    context_reset: bool = False

def changed_components(control: Config, treatment: Config) -> tuple[str, ...]:
    return tuple(
        field.name
        for field in fields(control)
        if getattr(control, field.name) != getattr(treatment, field.name)
    )

control = Config(progress_handoff=False, evaluator=True, retry_policy=True)
treatment = Config(progress_handoff=True, evaluator=True, retry_policy=True)
assert changed_components(control, treatment) == ("progress_handoff",)
To carry the method into a live project, replace the synthetic task flags with a versioned task suite and the simulated token counts with trace measurements. Keep the acceptance rules outside the candidate’s control. A fixed model alone is not a controlled comparison if prompts, test data, permissions, or the API’s reasoning and compaction settings changed too.
Find the code behind a behavior
A harness that passes its ablations can still outlive the model it was tuned for, and changing it later needs the code that implements a behavior. A request such as “mask secrets in every capture path” names a behavior, not a file. In a production harness that behavior may span several execution stages and shared state.
A 2026 preprint by Wang et al. proposes a Harness Handbook for this search, which the paper calls behavior localization. Static analysis extracts a program graph, an LLM groups its units into execution stages, and a maintainer or coding agent descends from a system overview to source-grounded entries for a function or file. Every entry must resolve against the live repository and is resynchronized after each change.
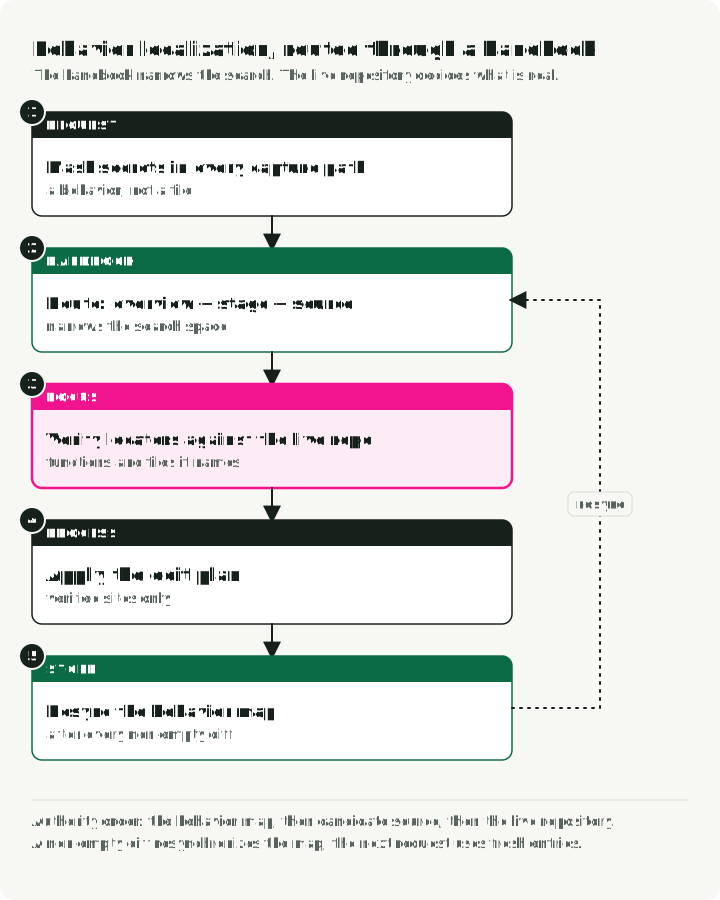
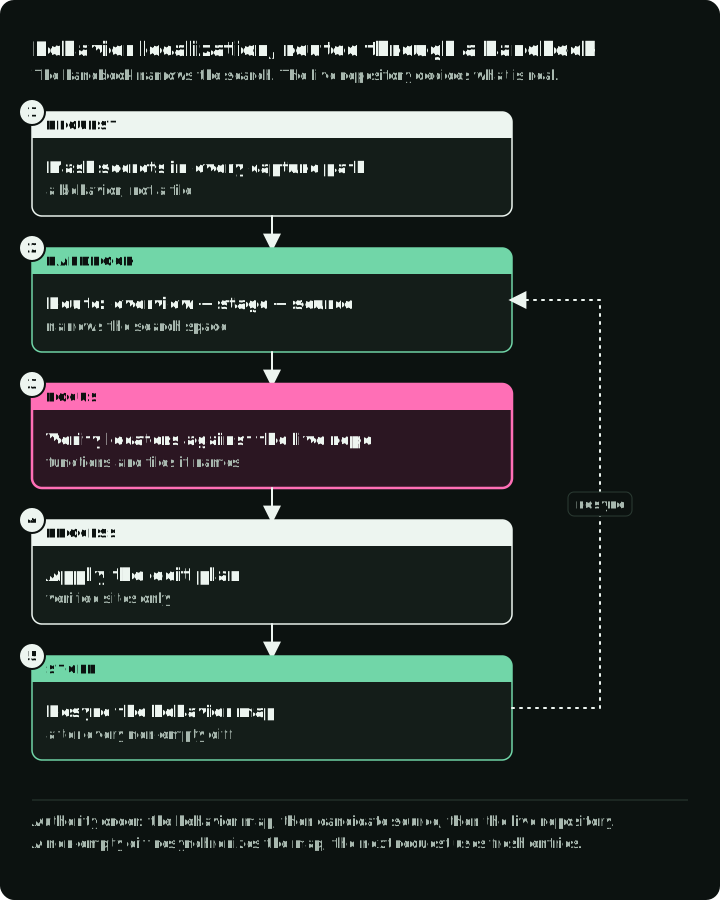
On two open-source harnesses, a planner that routed through the handbook produced edit plans that judges preferred more often, with fewer tokens. The study scored plans rather than executed changes and reported no uncertainty, so treat it as a research-stage approach.
Use the failure to find the owner
This series built outward from the reasoning loop. When a run fails, find the first responsibility that can prevent or detect it:
| What happened | Investigate |
|---|---|
| Poor next step with the right information available | Model and reasoning loop |
| Lost a prior decision or repeated completed work | Context assembly and memory |
| Could not express an action or read its result | Tool contract |
| Ran a forbidden action | Permission check and the enforcing service |
| Worker died and its environment disappeared | Runtime and checkpoint |
| Declared success without required evidence | Harness acceptance rule and tested snapshot |
I would begin with one capable model, narrow tools, a sandbox, and one explicit acceptance check. Record the first failure, add the smallest control that addresses it, and compare with that control disabled. Keep the rule and the trace together so the next model upgrade gives you a reason to retain or remove the component. For each component, record who maintains it, how many tokens or seconds it adds, and which regression test would justify removing it. Six months later, someone who sees progress_handoff=True should be able to find the failed traces that justified it and the regression cases that still keep it there.
References
- OpenAI, Unrolling the Codex agent loop.
- OpenAI, Harness engineering: leveraging Codex in an agent-first world.
- Anthropic Engineering, Demystifying evals for AI agents.
- Anthropic Engineering, Effective harnesses for long-running agents.
- Anthropic Engineering, Harness design for long-running application development.
- Lopopolo, Harness engineering: anthology, field guide, and agent context bundle.
- LangChain, Improving Deep Agents with harness engineering.
- OpenAI, How two settings tripled our ARC-AGI-3 scores.
- Wang et al., Harness Handbook: Making Evolving Agent Harnesses Readable, Navigable, and Editable, arXiv:2607.13285, 2026.
- Stripe, Idempotent requests.
- Yang et al., SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering.
- AWS, Making retries safe with idempotent APIs.
- Model Context Protocol, Tools specification.
- Model Context Protocol, Tasks extension and Tasks specification.
- Anthropic Engineering, An update on recent Claude Code quality reports.
The series’ Market Analyst Agent code is on GitHub.