LLM Engineering Guide: 45 Concepts for Production Systems

This is a reference for engineers who already know basic ML and systems concepts and need to connect a production symptom to the relevant part of the stack. It covers 45 concepts across hardware, inference, training, deployment, applications, and operations. Each entry gives the mechanism, what it changes in a running system, and the condition under which the cited result holds. If you start from a symptom, such as a slow first token or OOM under load, use the symptom table below to find the entries to read.
For a focused question, use the LLM engineering Fast Answers. Each topic has a separate answer and links back to the corresponding guide section.
| Part | Topics | Sections |
|---|---|---|
| I — Hardware foundations | Roofline model, GPU memory, hardware glossary | 1–3 |
| II — Inference fundamentals | Latency, throughput, KV cache, attention, quantization | 4–9 |
| III — Inference optimizations | CUDA kernels, FlashAttention, batching, PagedAttention, speculative decoding | 10–17 |
| IV — Model architecture | Transformer internals, decoder-only, MoE, tokenization, context windows | 18–22 |
| V — Training and alignment | Pretraining, LoRA, mixed precision, ZeRO, scaling laws, RLHF/DPO/GRPO, distillation | 23–32 |
| VI — Scaling and deployment | Parallelism, serving frameworks, GPU selection, routing | 33–36 |
| VII — Applications | Embeddings, RAG, agents, prompt engineering | 37–40 |
| VIII — Production operations | Rate limiting, failure modes, monitoring, cost, capacity planning | 41–45 |
Start from a symptom
Each row names the entries to read first and what to measure before you change the stack.
| Symptom or decision | Start with | Measure before changing the stack |
|---|---|---|
| First token is slow | Prefill and decode, TTFT | Queue time, prompt length, prefill time, and P99 TTFT |
| Tokens stream slowly | Roofline, TPOT | TPOT by concurrency, memory bandwidth, and batch shape |
| Long contexts trigger preemption or OOM | KV cache, PagedAttention | KV use, request lengths, allocator waste, and preemption count |
| A model does not fit the budget | Quantization, GPU selection | Quality, kernel throughput, memory reserve, and target-SLO goodput |
| Choosing a serving runtime | Serving frameworks, Parallelism | Throughput and P99 latency at the target SLO on your own prompts |
| Requests time out under load | Failure modes, Rate limiting | Queue depth, preemptions, retry rate, and output lengths |
| A training run does not fit | LoRA and QLoRA, ZeRO, FSDP | Model-state memory, communication, throughput, and held-out quality |
| Cost is rising | Routing, cost optimization | Traffic eligibility, quality errors, cache hit rate, and invoice data |
Deeper guides by decision
| If you are deciding… | Start with | Then read |
|---|---|---|
| How to serve many fine-tuned adapters | Inference fundamentals and deployment | LoRAX Serving Guide |
| Whether to quantize | Quantization | Model quantization guide |
| How to split a model across GPUs | Parallelism | Scaling Large Language Models |
| Whether to fine-tune | Training and alignment | LLM Fine-Tuning Guide |
| How retrieval fits into an app | Embeddings and RAG | RAG Evaluation Metrics |
| How agent systems work | Agents and prompt engineering | AI Agent Reasoning Loops |
| How to rank search results | Embeddings and reranking | Search Ranking Stack |
Part I — Hardware foundations
Arithmetic intensity, the GPU memory hierarchy, and the hardware terms in this part explain many of the choices later in the guide.
1. Memory-bound vs compute-bound and the roofline model
The starting point for LLM performance is arithmetic intensity: for every byte of data the GPU loads from memory, how many useful calculations does it perform? That ratio decides whether an operation is compute-bound (waiting on the processor) or memory-bound (waiting on data to load).
Every GPU has a “critical intensity” threshold where its peak compute throughput equals its memory bandwidth. For an NVIDIA H100 SXM using dense BF16 or FP16 Tensor Cores (989 TFLOPS; the 1,979-TFLOPS specification assumes structured sparsity):
The roofline chart below plots attainable compute against arithmetic intensity. The sloped line is the memory-bound region, where bandwidth sets the limit; the flat line is the maximum compute throughput; the intersection is the 295 FLOPs/byte threshold.
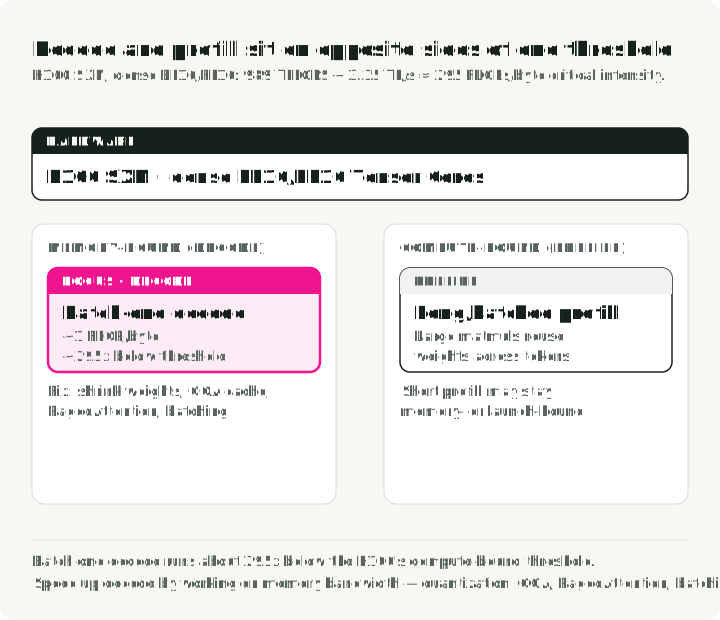
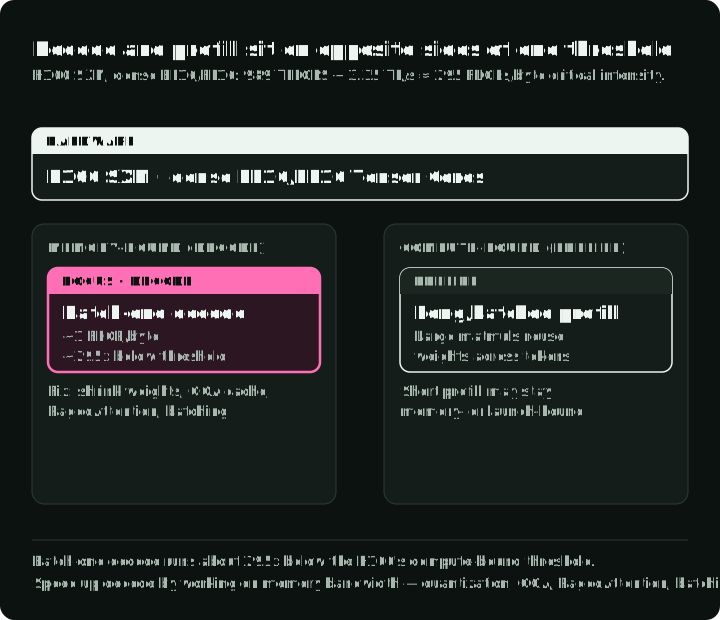
Batch-one decode and long or sufficiently batched prefill commonly sit on opposite sides of this threshold:
- Decode is memory-bound. Generating tokens one by one means loading the multi-gigabyte weight matrix from memory to multiply it against a single new token. In a simplified dense 16-bit, batch-one analysis, the operation has about 1 FLOP/byte, roughly 295x below the H100 roofline threshold. That gap explains why decode cannot approach peak compute throughput in this regime.
- Long or sufficiently batched prefill is often compute-bound. Processing many prompt tokens reuses weights across large matrix multiplications, which can push arithmetic intensity above the roofline threshold. Short prompts and small batches may instead be limited by memory traffic or kernel-launch overhead.
So to speed up decode, work on memory bandwidth: shrink the weights with quantization, reduce KV memory overhead with GQA and PagedAttention, and raise intensity with batching. For long or well-batched prefills, faster matrix computation and lower-precision compute may help; profile short-prefill workloads separately.
2. GPU memory hierarchy
A GPU has four memory layers with different capacities and access speeds. Registers are small and fast; HBM holds much more data but takes longer to access. Moving data between these layers is a major performance constraint. The figure shows an H100 SXM: registers and shared memory inside each SM, L2 on the die, and 80 GB of HBM3 in stacks beside it.
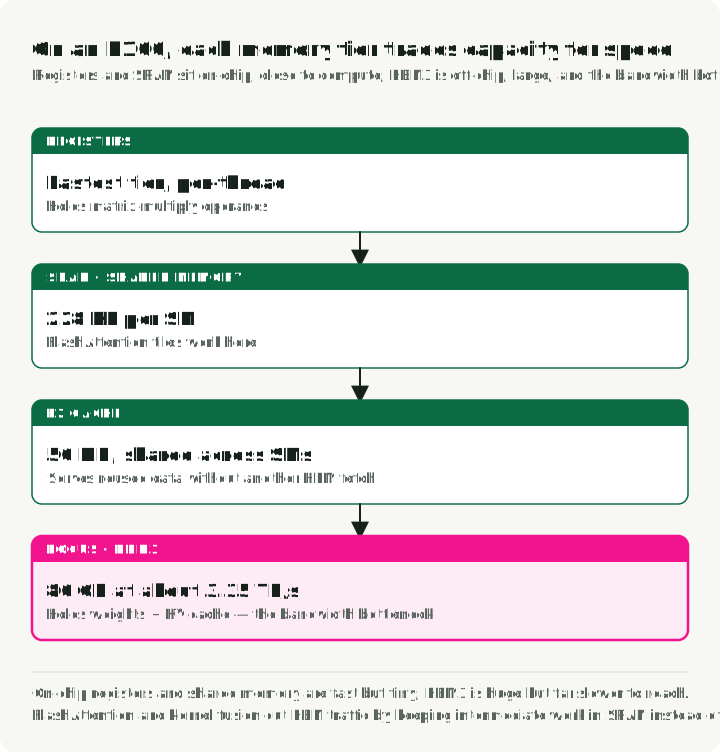
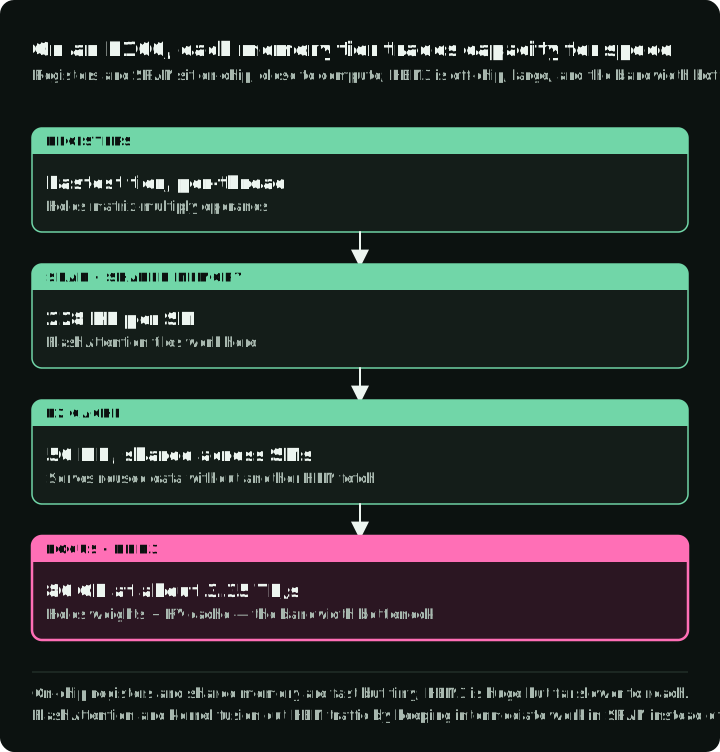
From fastest to slowest on an H100 SXM:
- Registers are the fastest memory and attach directly to processing threads. For Hopper’s WGMMA, matrix A can come from registers or shared memory, while matrix B comes from shared memory.
- SRAM (shared memory) is fast on-chip working memory local to each SM.
- L2 cache is a 50 MB shared layer. It can serve data reused across SMs without another HBM fetch.
- HBM3 is the 80 GB main memory that holds model weights and the KV cache, with ~3.35 TB/s of bandwidth.
The gap between the on-chip and off-chip tiers is large. On an A100, the FlashAttention paper estimates on-chip SRAM bandwidth at about 19 TB/s, against 1.5–2.0 TB/s for HBM (Dao et al., 2022), roughly a 10x difference. FlashAttention and kernel fusion reduce HBM traffic by retaining or combining intermediate work on chip. PagedAttention targets a different problem: it maps logical KV blocks to noncontiguous physical GPU-memory blocks, reducing fragmentation and enabling block sharing.
3. GPU hardware glossary
The terms below show up throughout the rest of the guide.
HBM (High Bandwidth Memory) stacks DRAM dies connected by through-silicon vias (TSVs) next to the GPU die. Generations include HBM2e (A100, 2 TB/s), HBM3 (H100, 3.35 TB/s), and HBM3e (H200/B200, 4.8–8 TB/s). HBM bandwidth is a direct constraint on TPOT in memory-bound decode regimes.
GDDR (Graphics DDR) is traditional graphics memory used in consumer and workstation GPUs such as the RTX 4090 and L40S. Those cards have lower memory bandwidth than the H100 SXM. GDDR6X on the RTX 4090 delivers 1,008 GB/s in NVIDIA’s Ada architecture whitepaper, versus the H100 SXM’s 3.35 TB/s of HBM3 bandwidth.
An SM (Streaming Multiprocessor) is the basic compute block in an NVIDIA GPU. Each SM contains CUDA cores, Tensor Cores, shared memory, and a warp scheduler. The H100 SXM has 132 SMs; H100 PCIe has 114. The A100 has 108.
Tensor Cores are specialized matrix-multiply-accumulate units inside each SM. They accelerate the mixed-precision matmuls that dominate transformer computation. H100 SXM Tensor Cores deliver 494.5 dense or 989 sparse TF32 TFLOPS; always include the precision and sparsity mode when comparing this figure.
CUDA Cores are general-purpose floating-point and integer units. They handle element-wise operations, activation functions, and other non-matrix work while Tensor Cores run supported matrix operations.
A warp is a group of 32 threads on an SM. Threads can diverge, and Volta and later GPUs support independent thread scheduling. Warp specialization assigns different warps to data movement and computation so the tasks can overlap.
NVLink is NVIDIA’s high-speed GPU-to-GPU interconnect within a node. NVLink 4.0 on H100 delivers 900 GB/s bidirectional bandwidth; NVLink 5.0 on B200 reaches 1.8 TB/s. This bandwidth matters for tensor parallelism because GPUs exchange partial results at every transformer layer.
InfiniBand is a high-speed network fabric for inter-node communication. ConnectX-class InfiniBand adapters provide the inter-node fabric for pipeline-parallel or distributed-training traffic; bandwidth depends on the adapter and port configuration.
RDMA (Remote Direct Memory Access) lets a device access memory on another machine without routing the data path through either CPU. GPUDirect RDMA supports direct GPU-to-GPU transfers across nodes, including KV-cache transfers in disaggregated serving.
NVMe (Non-Volatile Memory Express) is the SSD interface used for KV-cache offloading and ZeRO-Infinity parameter offloading when GPU and CPU memory are insufficient. Sequential bandwidth depends on the drive and workload, and it remains far below HBM bandwidth.
TFLOPS and PFLOPS are trillions and quadrillions of floating-point operations per second. One TFLOPS equals FLOPS. H100 reaches 989 sparse TF32 tensor TFLOPS, while FlashAttention-3 reports about 1.2 PFLOPS in FP8; those values use different formats and should not be compared as if they were one metric.
Part II — Inference fundamentals
Inference turns a model into a user-visible service. The following concepts separate work that delays the first token from work that slows every later token, and expose the memory limits behind both.
4. Latency: TTFT, TPOT, and percentiles
Time to First Token (TTFT) is the end-to-end delay from request submission to the first output token. It includes queueing, tokenization, scheduling, the prefill pass that produces the first token, and network delivery. Common serving engines sample the first output token from the logits of the prefill forward pass, so no separate decode step runs before it. Longer prompts usually increase the prefill component, but any of these stages can dominate. Targets are product-specific; MLPerf Inference v5.0 uses a P99 TTFT limit of 450 ms for its Llama 2 70B interactive scenario.
Time Per Output Token (TPOT) is the average interval between consecutive tokens after the first. It maps to the decode phase. Batch-one or low-intensity decode is usually memory-bandwidth-bound, while sufficiently large batches can become compute-bound:
This definition requires at least two output tokens; TPOT is undefined for a one-token response. For this equation, E2E latency ends at the last output token. An HTTP-completion timer can also include later metadata or connection cleanup; record that separately.
An English reading-speed estimate gives one rough reference point for streaming. Average adult English silent reading speed is about 238 words per minute for non-fiction (Brysbaert, 2019), about 4 words per second. If a token averages three quarters of a word, that is about 5 tokens per second, or 200 ms per token. This estimate is not a usability threshold: language, tokenizer, task, and client buffering change the result. MLPerf’s interactive scenario uses a much tighter P99 TPOT limit of 40 ms. Set your own target from product testing.
P50 vs P99 latency matters because the median hides the tail. A system with a good P50 and a bad P99 may have batching, preemption, queueing, or workload-skew problems; traces are needed to distinguish them.
5. Throughput: tokens per second and the latency tradeoff
Throughput is measured in output tokens per second across concurrent requests. Requests per second is weaker on its own because a 10-token response and a 1,000-token response have very different costs. Published benchmark numbers vary with model, precision, hardware, prompt and output lengths, concurrency, and SLO. Compare vLLM, SGLang, and TensorRT-LLM with one harness rather than combining their headline results.
Increasing a small decode batch can raise throughput by sharing weight reads. Larger batches or higher offered load eventually increase latency or hit memory, compute, or communication limits. Measure that curve rather than assuming linear scaling. Goodput, the rate of requests per second that meet your SLO targets, connects raw throughput to what users actually experience.
6. KV cache: memory that grows with every token
During full-attention autoregressive generation, each new token attends to the current token and previous tokens. The KV cache stores Key and Value projections so generation does not recompute earlier tokens’ projections at every step. Full-attention decode still reads a growing history; the total attention work over a generated sequence remains quadratic in its length.
For a conventional full-attention MHA or GQA cache, memory grows linearly with sequence length, batch size, and layer count. The following formula does not apply unchanged to MLA, sliding-window, recurrent, or hybrid architectures:
where:
- = number of layers
- = number of KV heads
- = head dimension
- = sequence length
- = batch size
- = bytes per cached element, set by the KV-cache precision
Concrete examples with FP16 and batch size 1: Llama 3.1 8B at 8,192 tokens uses ~1.07 GB (1 GiB) of KV cache; at 128K tokens, 16 GiB. Llama 3.1 70B at 128K tokens needs 40 GiB (about 43 GB) for a single sequence, about half of an H100’s 80 GB. At high concurrency or long context, KV cache can exceed model weight memory; the result depends on sequence length, active batch size, KV precision, and the number of KV heads. The original vLLM evaluation in 2023 reported 60–80% waste from fragmentation and pre-allocation in the systems it compared.
The main optimizations are GQA (fewer KV heads), KV cache quantization (FP8/INT8), PagedAttention (block-based allocation), and offloading reusable KV data to CPU or NVMe. Their benefits depend on workload and implementation.
To answer “how many sequences fit in my KV budget?” for another model, read three numbers from its config.json: num_hidden_layers, num_key_value_heads, and head_dim when present. For the Llama examples, head dimension is hidden_size / num_attention_heads. Per-device memory also depends on cache sharding and any KV-head replication. The function below applies the formula; the asserts reproduce the numbers above and the capacity example in Section 45.
def kv_cache_bytes(layers, kv_heads, head_dim, seq_len, batch=1, bytes_per_elem=2):
    """Bytes of KV cache: a key and a value per layer, KV head, and token."""
    return 2 * layers * kv_heads * head_dim * seq_len * batch * bytes_per_elem

GiB = 2**30

# Llama 3.1 8B: 32 layers, 8 KV heads, head dimension 128, FP16 cache.
llama_8b = kv_cache_bytes(32, 8, 128, seq_len=8_192)
print(f"8B at 8K tokens: {llama_8b / 1e9:.2f} GB")  # 1.07 GB
assert llama_8b == 1 * GiB

# Llama 3.1 70B: 80 layers, 8 KV heads, head dimension 128.
assert kv_cache_bytes(80, 8, 128, seq_len=131_072) == 40 * GiB

# How many 4K-token sequences fit in a 40 GiB KV budget?
per_4k = kv_cache_bytes(80, 8, 128, seq_len=4_096)
print(f"70B at 4K tokens: {per_4k / GiB:.2f} GiB per sequence")  # 1.25 GiB
print("4K sequences in 40 GiB:", 40 * GiB // per_4k)  # 32
assert 40 * GiB // per_4k == 32

# An FP8 KV cache halves the size per sequence and doubles the count.
assert 40 * GiB // kv_cache_bytes(80, 8, 128, 4_096, bytes_per_elem=1) == 64
The result is an upper bound. The runtime also needs memory for activations, allocator overhead, and headroom for request-length variance.
7. Prefill vs decode: two phases, two bottlenecks
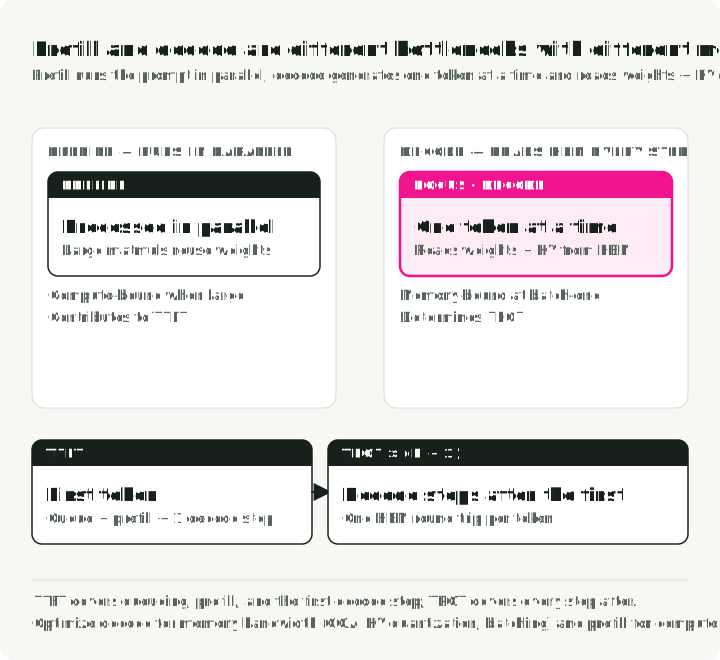
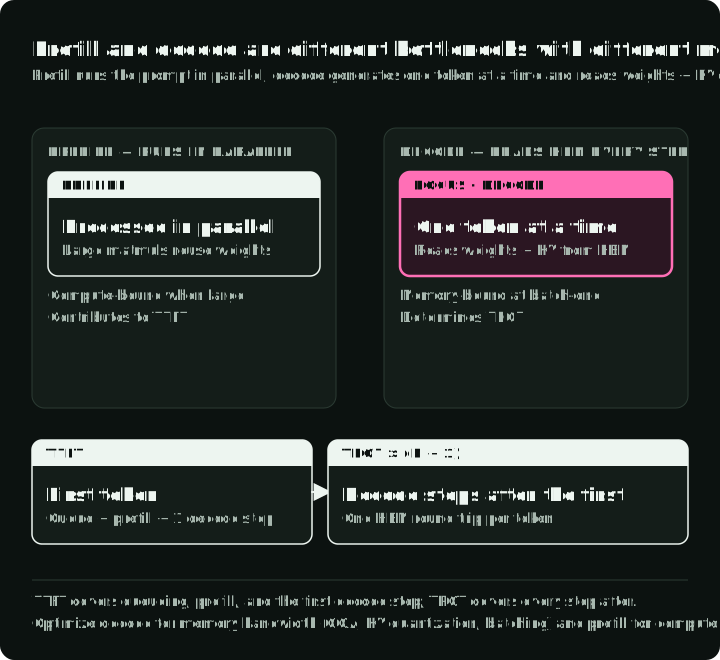
The prefill phase processes the input prompt in parallel and populates the KV cache. Long or sufficiently batched prefills often become compute-bound because they use large matrix multiplications; short prefills may remain limited by memory traffic or kernel-launch overhead. Prefill contributes to time to first token (TTFT), alongside queueing, tokenization, scheduling, and network delivery; its forward pass also produces the first output token. The decode phase generates one token at a time. Each step reads model weights and the KV cache from HBM, making batch-one decode memory-bandwidth-bound and the main driver of time per output token (TPOT).
The figure follows one request: prefill reuses weights across prompt tokens and ends with the first token, inside TTFT; each later decode step reads the weights and KV cache again for one token and adds to TPOT.
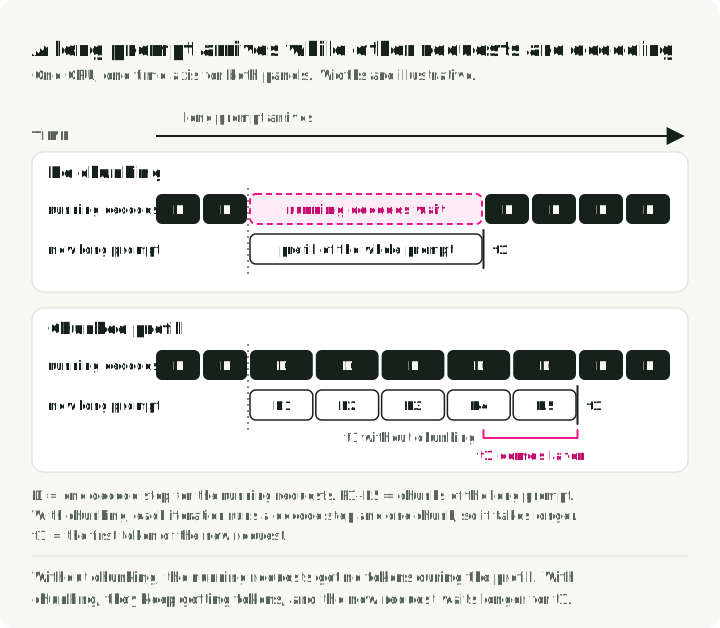
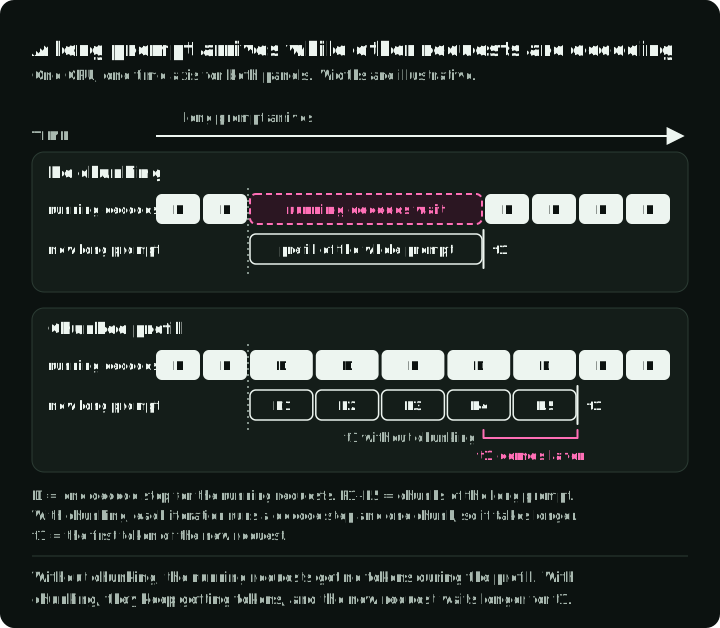
Chunked prefill splits a long prompt into chunks and schedules them alongside running decodes. Actual chunk sizes can vary with the iteration’s available token budget. In Sarathi-Serve (section 4.2) and in vLLM, the scheduler puts the running decodes into the batch first and fills the rest of a per-iteration token budget with prefill tokens. A long prompt then no longer stops the other requests from getting tokens. The new request pays for this: its prefill spans several iterations, and each chunk reads the KV cache of the earlier chunks again. Sarathi-Serve measured about 25% extra prefill time for Yi-34B with tensor parallelism of two and 512-token chunks (section 5.4.1), and the vLLM docs state that a smaller token budget gives better inter-token latency and a worse TTFT. Sarathi-Serve reports better throughput-latency trade-offs in its tested workloads, but the gain depends on the model, hardware, request-length distribution, chunk size, and comparison baseline.
Disaggregated serving places prefill and decode on separate GPU pools, allowing each pool to target a different bottleneck. Splitwise and DistServe describe the pattern. The prefill pool sends each request’s KV cache to the decode pool. DistServe uses NVLink inside a node and InfiniBand across nodes; Splitwise uses InfiniBand, which supports RDMA. The transfer cost becomes part of the design.
The figure puts both schedules on one time axis: one long prompt arrives while other requests are decoding. Chunking keeps the other requests’ tokens coming and moves the new request’s first token later.
8. GQA and MQA: shrinking the KV cache
Standard Multi-Head Attention (MHA) gives every query head its own K and V head. Multi-Query Attention (MQA) shares a single KV head across all query heads, which is an extreme reduction. Grouped-Query Attention (GQA) is the practical middle ground: groups of query heads share one KV head. The figure draws eight query heads and the KV heads each variant keeps; the KV cache shrinks in proportion to the KV head count.
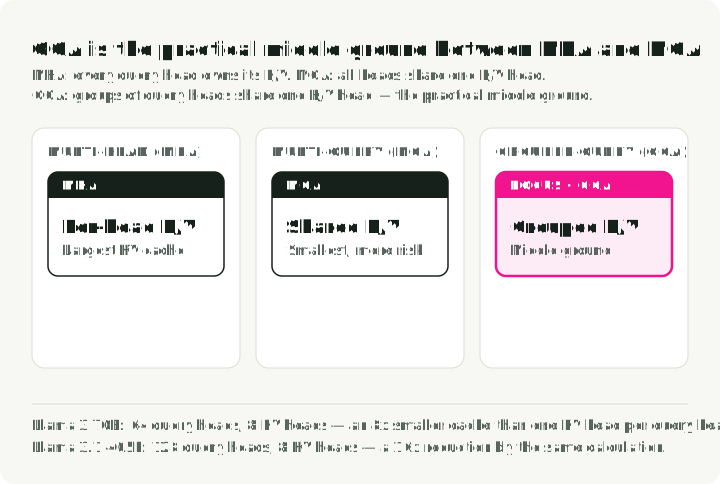
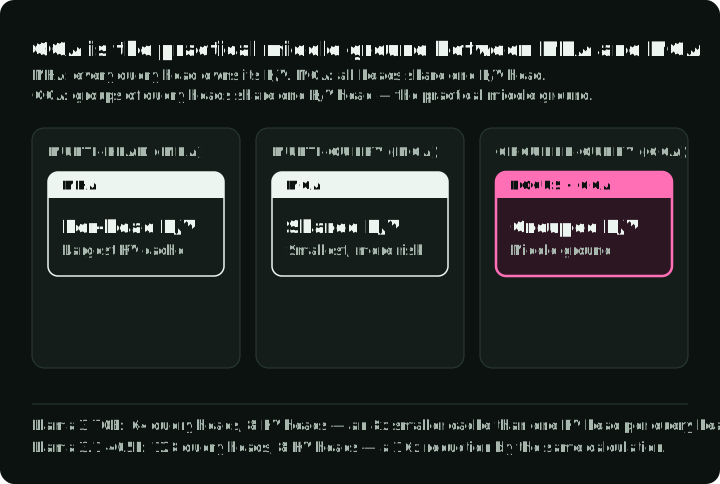
Llama 3 70B uses 64 query heads but only 8 KV heads, an 8x KV cache reduction versus the same architecture with one KV head per query head. Llama 3.1 405B uses 128 query heads and 8 KV heads, a 16x reduction by the same calculation (Meta, 2024). Ainslie et al. report GQA quality close to MHA in their tested models while approaching MQA speed. A smaller KV cache can support larger batches, but the realized latency and throughput gain still depends on the kernel and workload.
9. Quantization: trading bits for speed and memory
Quantization reduces the precision of model weights and/or activations. The core tradeoffs:
| Format | Bits | Weight memory (7B model) | Quality note |
|---|---|---|---|
| FP16/BF16 | 16 | ~14 GB | Baseline for comparison |
| FP8 | 8 | ~7 GB | Hardware-native on Hopper; evaluate model |
| INT8 | 8 | ~7 GB | Calibration and kernel dependent |
| INT4 | 4 | ~3.5 GB | Largest compression; evaluate carefully |
AWQ (Activation-Aware Weight Quantization) identifies salient weight channels from activation magnitudes and applies per-channel scaling to protect them. Its calibration needs depend on the model and configuration; in one OPT-6.7B INT3-g128 comparison, AWQ used 16 calibration sequences while GPTQ used 192. Report both the sequence count and sequence length in a reproducible setup. GPTQ uses approximate second-order information for layer-wise quantization. bitsandbytes can quantize during model loading without a separate preprocessing pass; its NF4 format powers QLoRA fine-tuning. FP8 on Hopper-class hardware halves weight memory relative to FP16/BF16, but quality and speed still depend on the model, calibration, and kernel.
The table maps each method to the job it usually fits. The model quantization guide covers each method in depth.
| Method | Calibration data | Typical use |
|---|---|---|
| AWQ or GPTQ (INT4 weight-only) | Yes, a small sample | Serving a large model on memory-limited GPUs through a supported INT4 kernel |
| bitsandbytes NF4 | No | QLoRA fine-tuning and quick experiments |
| FP8 | Small sample or dynamic scaling | Serving on Hopper or newer GPUs, with a quality check on the target task |
| INT8 (W8A8) | Yes, for activation scales | GPUs without FP8, such as A100 or A10G, when the serving kernel supports it |
The serving kernel can matter as much as the quantization algorithm. Section 10 gives a bounded Marlin result and explains why the gain depends on the serving configuration.
Part III — Inference optimizations
The optimizations in this part solve different constraints. FlashAttention reduces attention’s HBM traffic; PagedAttention improves KV allocation; continuous batching prevents finished sequences from holding batch capacity.
10. CUDA kernels and kernel fusion
A CUDA kernel is a function written for the GPU that runs in parallel across thousands of threads. When the CPU calls a kernel, the GPU distributes the work across its SMs: each SM runs multiple warps of 32 threads, and each thread processes a slice of the data. A CUDA serving implementation runs GPU work through kernels. Launch counts depend on the model graph, compiler, runtime, and fusion. Kernel implementation can determine whether the system meets its latency SLO.
The main kernel categories in LLM serving:
- GEMM kernels for matrix multiplication, which dominate both prefill and decode compute.
- Attention kernels like FlashAttention that tile computations to stay in SRAM instead of spilling to HBM.
- Fused kernels that combine multiple operations (such as add + layer norm or QKV projection) into a single launch to skip the intermediate HBM round-trips.
- Sampling kernels that convert logits to token IDs via top-k, top-p, or temperature sampling.
Kernel quality can determine whether compressed weights deliver a speedup. The Marlin paper reports up to 2.8x end-to-end speedup over its FP16 baseline for tested weight-only INT4 vLLM configurations. That result is specific to the paper’s models, GPUs, batch sizes, and serving setup, so it is not a universal INT4 gain.
Triton lowers the barrier to writing custom kernels by exposing GPU programming through Python instead of raw CUDA C++, which puts kernel-level optimization within reach of ML engineers and not only GPU specialists. Most of the optimizations later in this part (FlashAttention, fused kernels, PagedAttention) are either better kernels or smarter ways to orchestrate kernel launches.
Kernel fusion combines sequential operations into one GPU kernel and skips intermediate HBM writes. Common fusions include QKV projection, attention plus softmax, and residual addition plus RMSNorm. FlashNorm instead combines RMSNorm scaling with the following linear projection and defers normalization. DeepFusionKernel fuses a complete SwiGLU MLP, including its matrix multiplications. The exact launch-count and utilization gains depend on the model graph, compiler, GPU, and serving framework, so profile the deployed stack rather than relying on a universal percentage.
11. FlashAttention: tiling attention to live in SRAM
Standard attention materializes the full attention matrix in HBM, which costs memory and produces a lot of memory traffic. The idea behind FlashAttention is to never materialize this matrix at all. It tiles the Q, K, V matrices into blocks that fit in SRAM, computes partial attention within each tile, and merges results using an online softmax (incrementally tracking the running max and sum across blocks). Intermediate storage drops from to , with fewer HBM reads and writes in the paper’s tested shapes. Dense attention arithmetic remains quadratic in sequence length.
Each version targets the bottleneck of its GPU generation:
- FlashAttention v1 (A100, 2022) proved the tiling plus online-softmax idea works. The paper reported a 2–4x speedup over standard attention, but only 25–40% GPU utilization. The FA2 paper attributes this to non-matmul work, shared-memory communication, and limited parallelism.
- FlashAttention v2 (A100, 2023) reworked the parallelism to split across the sequence dimension as well as batch and heads. It reached 50–73% utilization on A100, roughly 2x faster than v1.
- FlashAttention v3 (H100 Hopper, 2024) added warp specialization (separate warps for data movement vs. math) and GEMM-softmax pipelining to overlap memory loads with computation. The paper reports up to 740 TFLOPS in FP16 (75% utilization) and close to 1.2 PFLOPS in FP8 on H100.
- FlashAttention v4 (B200 Blackwell, 2026) addresses a new bottleneck: on Blackwell, tensor core throughput scales so fast that non-matmul operations (softmax exponentials, rescaling) become the limiter. FA4 software-emulates the exponential with polynomial approximations on FMA units, uses conditional rescaling to reduce overhead, and stores intermediates in Blackwell’s dedicated tensor memory (TMEM) instead of registers. The paper reports about 1.6 PFLOPS on B200 in BF16, 1.3x faster than cuDNN 9.13 and 2.7x faster than Triton in its tests.
12. FlashDecoding: parallelizing the decode bottleneck
Standard FlashAttention keeps the GPU busy by splitting work across batch size and query length. During decode the model generates exactly 1 token at a time (query length = 1). When batch size times the number of attention heads is far below the GPU’s SM count (108 on an A100), many SMs can remain idle while the active ones process the token history.
FlashDecoding solves this by adding a new parallelization dimension: the KV sequence length itself. It chops the KV cache into smaller chunks and distributes them across all the otherwise-idle GPU processors to evaluate in parallel, then merges their partial computations with a log-sum-exp reduction.
In Stanford’s batch-one CodeLlama-34B benchmark, on four A100 GPUs with sequence lengths from 512 to 64K tokens, FlashDecoding reached up to an 8x end-to-end speedup over the tested baselines and improved attention scaling across the tested long contexts. The result is bounded to that hardware and benchmark rather than a general decode guarantee.
13. Continuous batching vs static batching
Static batching waits for every sequence in a batch to finish before starting the next, so short sequences waste GPU cycles idling after they hit end-of-sequence. Continuous batching (introduced by the Orca paper, OSDI 2022) operates at iteration-level granularity: at each decode step, completed sequences are removed and new ones inserted. The figure shows four batch slots over ten decode steps under each policy.
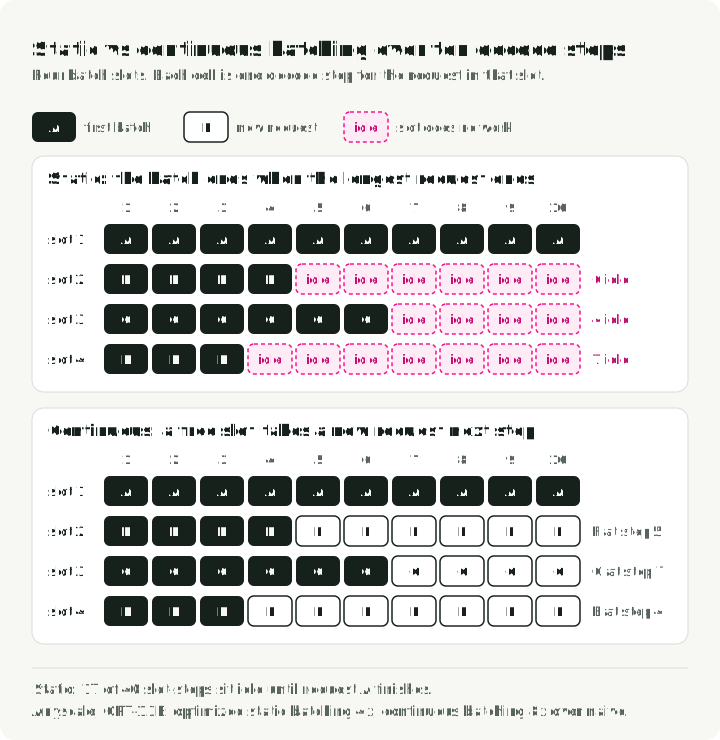
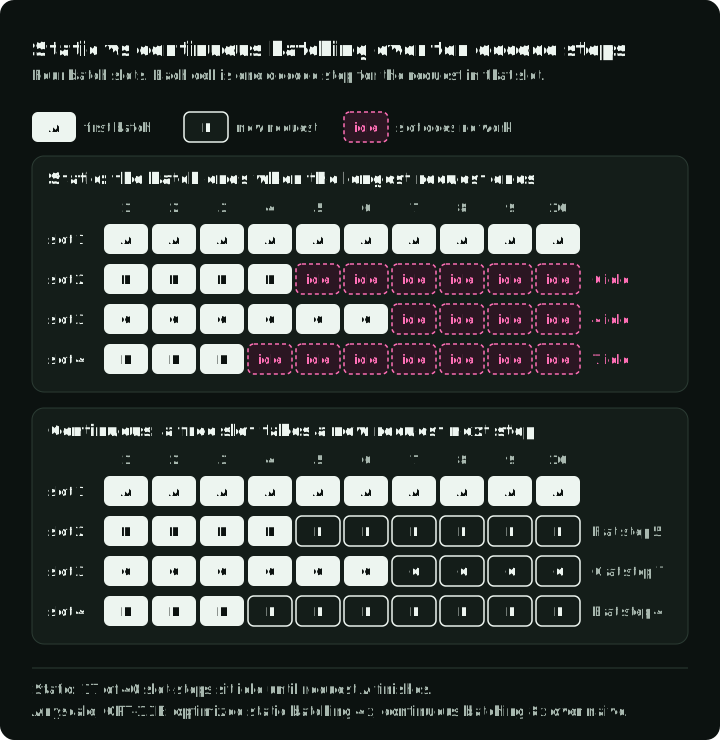
In Anyscale’s 2023 OPT-13B benchmark on an A100-40GB, with 1,000 requests, 512-token prompts, and mean-128-token outputs, optimized static batching reached 4x its naive baseline, continuous batching reached 8x, and vLLM with continuous batching plus PagedAttention reached 23x (Anyscale, 2023). Continuous batching also increases pressure on KV allocation, which is why it is commonly paired with paged memory management.
14. PagedAttention: virtual memory for KV cache
vLLM’s PagedAttention applies the OS virtual-memory idea to KV cache management. The KV cache is split into fixed-size blocks (16 tokens in this illustration; runtime block sizes vary), blocks are allocated on demand as tokens are generated, and logical (sequential) positions map to physical (scattered) memory locations through block tables. Multiple requests that share a prefix (system prompts, beam search) can point to the same physical blocks. Prefix reuse also requires compatible cache keys and a cache lookup policy. The figure shows a block table for two requests that share a system prompt.
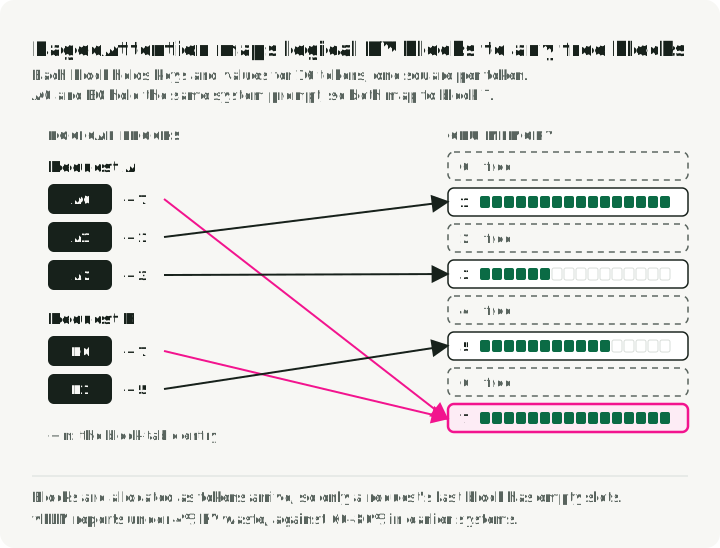
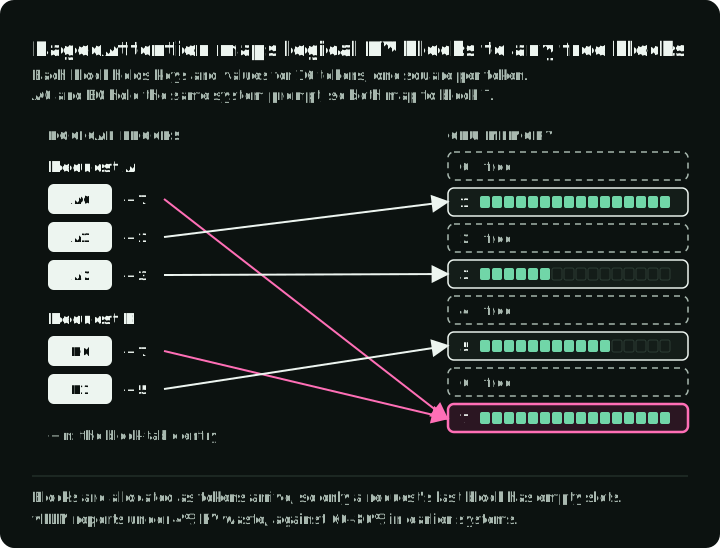
The June 2023 vLLM evaluation reported 60–80% KV-memory waste in the earlier systems it tested and under 4% with its paged allocator. It reported 2–4x higher throughput than TGI and up to 24x over Hugging Face Transformers in selected workloads. These are historical end-to-end comparisons of serving systems, not a universal PagedAttention speedup or waste bound. A partly filled final block can waste a larger share for short sequences.
15. Speculative decoding: multiple tokens per forward pass
In speculative decoding, a small draft model generates candidate tokens, then the large target model scores all positions in one forward pass. The decoder accepts draft tokens from left to right with probabilities derived from the target and draft distributions. After the first rejection, it samples a correction from the residual target distribution and discards the remaining draft tokens. This modified rejection-sampling step preserves the target model’s output distribution within hardware numerics; exact token matching alone does not. The figure works through one round with four draft tokens.
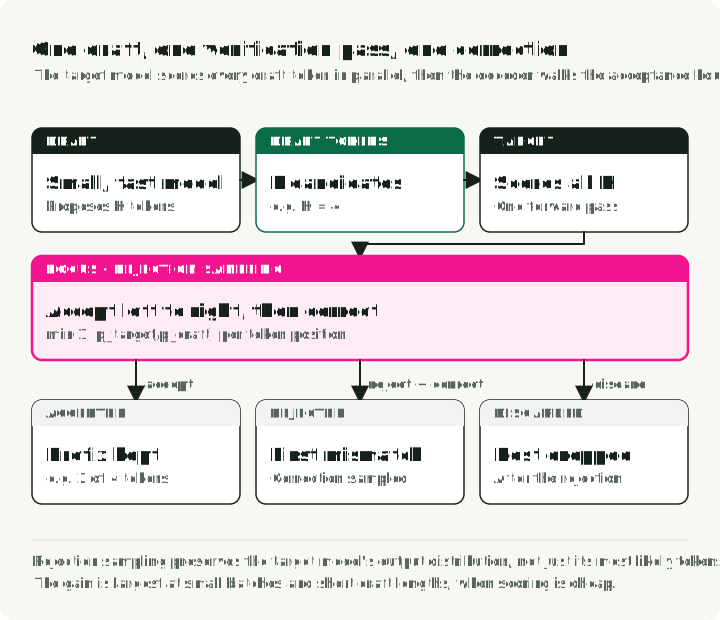
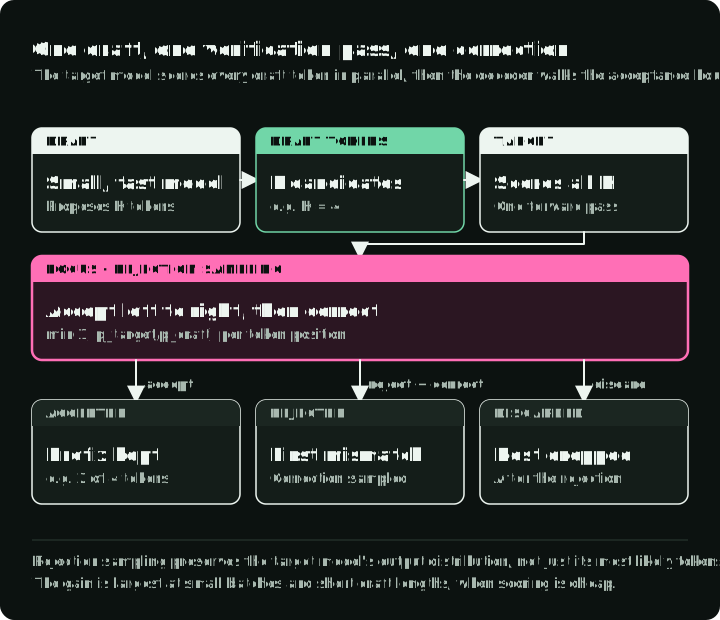
The gain is most plausible at small serving batches and short draft lengths, when scoring the draft is dominated by weight, KV-cache, or communication traffic rather than the extra token compute. The original speculative-sampling paper reported a 2–2.5x decoding speedup for its tested 70B Chinchilla setup; EAGLE-3 v3 reported up to 6.5x in its tests. Variants include Medusa (extra prediction heads, no separate model), prompt lookup decoding (n-gram matching against the input without a separate draft-model forward pass), and EAGLE. The original EAGLE extrapolates features; EAGLE-3 combines several feature levels and predicts tokens directly.
At high batch sizes, extra draft and verification work can erase the gain. Speculative decoding is most promising when the serving batch is small enough and draft acceptance is high; benchmark the full serving loop rather than the verification kernel alone.
16. Prefix caching and KV cache reuse
Instead of throwing away the KV cache when a request finishes, prefix caching keeps it around for reuse on new requests that share the same prefix tokens. That cuts redundant prefill for system prompts, few-shot examples, RAG context, and multi-turn conversation history.
vLLM’s Automatic Prefix Caching hashes KV blocks and uses a global hash table for lookup. SGLang’s RadixAttention maintains a radix tree of cached KV tensors with token-level granularity. Both require token-identical prefixes and compatible cache keys. Model or adapter identity, multimodal inputs, and isolation settings can also affect reuse. Report hit rate alongside latency or throughput.
17. Streaming in practice
Streaming sends tokens to the client as they are generated instead of waiting for the full response. Many serving frameworks expose it via Server-Sent Events: the client opens a long-lived HTTP connection, and the server pushes each token or token batch as a data: event. TTFT determines when the user first sees output; TPOT helps determine how smooth it feels. Set the target through product testing and the chosen interaction model.
On the client side, streaming forces buffering decisions. Rendering token by token can cause visual jitter, especially with markdown or code blocks that need multi-token context to format correctly. Common patterns are word-level buffering (accumulate tokens until a whitespace boundary), line-level buffering (wait for a newline before rendering), and adaptive buffering (render immediately for prose, buffer for code blocks). In the OpenAI Chat Completions API, stream_options: {"include_usage": true} adds a final usage chunk before the data: [DONE] message. Interrupted OpenAI streams may omit the final usage chunk. OpenAI-compatible servers may differ, so verify the selected implementation.
Chunked prefill is one way to keep long prefills from stalling token delivery for concurrent users. Decode-priority scheduling can protect in-flight requests, while disaggregated serving isolates prefill and decode on separate GPU pools.
Part IV — Model architecture
Architecture sets the memory footprint, attention behavior, and training dynamics that the serving and training sections work around.
18. Transformer architecture essentials
A modern decoder-only transformer (GPT, Llama) is a stack of identical layers, each with two sub-blocks: attention and feed-forward. Every sub-block is wrapped with a residual connection and normalization. The figure shows one Llama-style layer, including the two paths that skip a sub-block, and how its projection weights split between attention and the feed-forward network; the components are described below it.
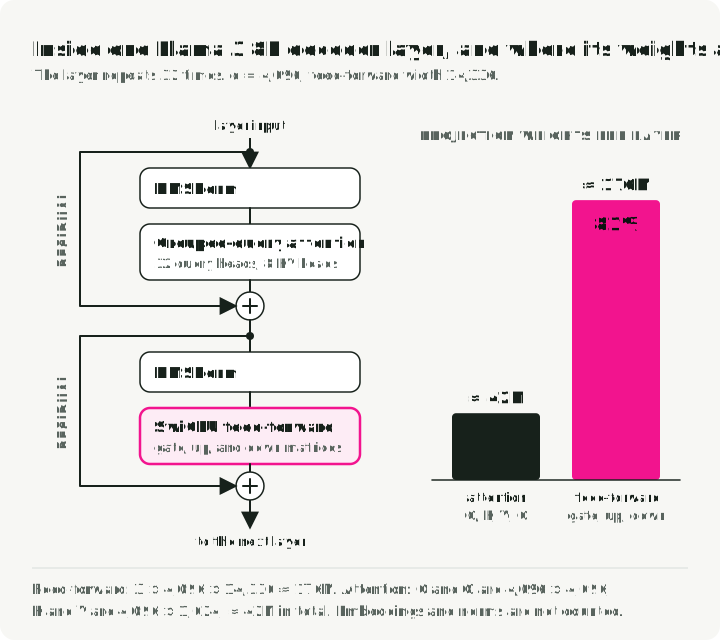
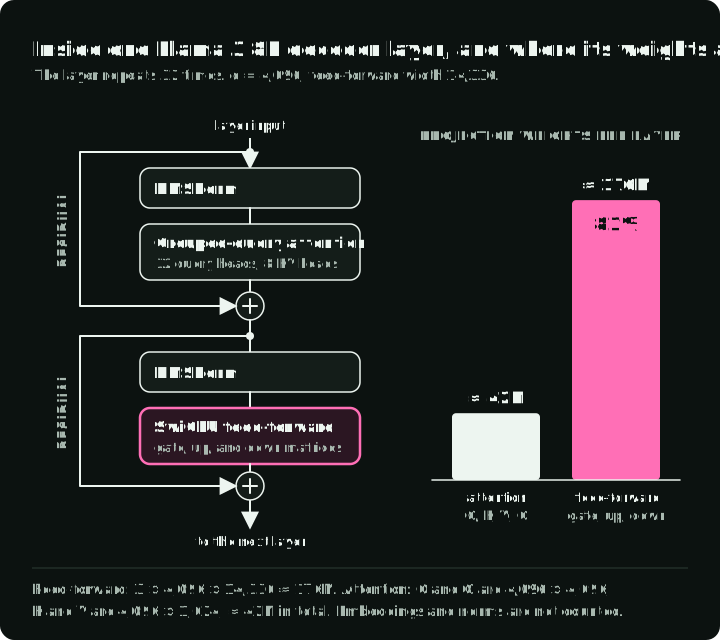
The key components:
Multi-Head Attention lets each token weight information from the tokens visible under the attention mask. The input is projected into three matrices: Queries (what am I looking for?), Keys (what do I contain?), and Values (what information do I carry?). Attention scores are then computed as:
The dot product measures similarity between every pair of tokens. Dividing by keeps the dot products from growing too large (which would push softmax into regions with vanishing gradients). The softmax converts scores to probabilities, and multiplication by produces a weighted combination of value vectors. Running this across multiple heads in parallel lets the model attend to different relationships at the same time (heads can learn different relationships; their roles are not fixed).
The Feed-Forward Network (FFN) transforms each token representation independently after attention mixes information across tokens. Modern LLMs often use SwiGLU instead of the original two-matrix ReLU FFN:
SwiGLU has three weight matrices, versus two for a ReLU FFN, and uses smooth Swish. Llama, Mistral, and Qwen use it; Gemma uses an approximate GeGLU. The familiar two-thirds rule applies to a conventional full-MHA block with : its two FFN matrices contribute about parameters, versus about for attention. It is not a general estimate for SwiGLU/GQA architectures. In Llama 3 8B, , , and eight key/value heads make the FFN M parameters per layer, versus about 42M attention-projection parameters: about 81% of those projection weights, before embeddings and normalization.
Residual connections add each sub-block’s output back to its input: . The skip path improves signal and gradient propagation through deep stacks.
RMSNorm is common in modern LLM families. LayerNorm re-centers by subtracting the mean and re-scales by the standard deviation. RMSNorm skips mean subtraction and only re-scales; its paper reports 7–64% reductions in running time across its tested models and frameworks without reducing the measured task performance. Pre-norm placement, which normalizes before attention or the FFN, is also common because it improves gradient stability.
Parameter count estimation for a conventional decoder with full MHA, a two-matrix FFN of width , and tied input/output embeddings:
where is vocabulary size, is hidden dimension, and is layer count. The term is the input embedding matrix; the term approximates the attention and FFN weights in each layer. For Llama 3 8B (, , ), the estimate is about parameters. The published 8.03B total is higher because the approximation omits architectural details such as the exact FFN width and the separate output projection.
19. Decoder-only models for general-purpose generation
The original Transformer (2017) had both an encoder and a decoder. Since then, the field split into three architectural families, and one became the default for generative AI.
| Family | Attention | Training objective | Used today for | Examples |
|---|---|---|---|---|
| Encoder-only | Bidirectional | Masked-token prediction | Embeddings, rerankers, classifiers | BERT, RoBERTa |
| Encoder-decoder | Bidirectional encoder; causal decoder with cross-attention | Sequence to sequence (span corruption, T5) | Translation, speech recognition | T5, BART, Whisper |
| Decoder-only | Causal | Next-token prediction | General text generation, chat, code | GPT, Llama |
Encoder-only models use bidirectional attention: every token attends to every other token in both directions. That produces representations for understanding tasks. Standard encoder-only models are not normally used as autoregressive decoders; they commonly provide the base architecture for embedding models, rerankers, and lightweight classifiers (for example, the BERT-based routers in RouteLLM).
Encoder-decoder models separate understanding from generation. The encoder processes the full input with bidirectional attention, then the decoder generates output autoregressively while attending to the encoder’s representations through cross-attention. That fits tasks where input and output are different sequences, such as translation and speech recognition.
Decoder-only models such as GPT, Llama, and Mistral use causal attention: each token attends to itself and previous tokens. Four useful properties for generation are:
- KV-cache reuse. With causal attention, earlier tokens never attend to later ones, so their keys and values stay valid as new tokens are generated. One cache per sequence grows by append (Section 6). An encoder-decoder also keeps cross-attention state over the encoder output.
- Training on raw text. Next-token prediction needs no paired input and output, so any text corpus is training data.
- One repeated block. The model is a stack of identical decoder layers, with no separate encoder stack or cross-attention path to build, shard, and optimize.
- In-context learning. Instructions, few-shot examples, and the query are all tokens in one prefix, so one model can take on a new task from the prompt.
20. Mixture of experts
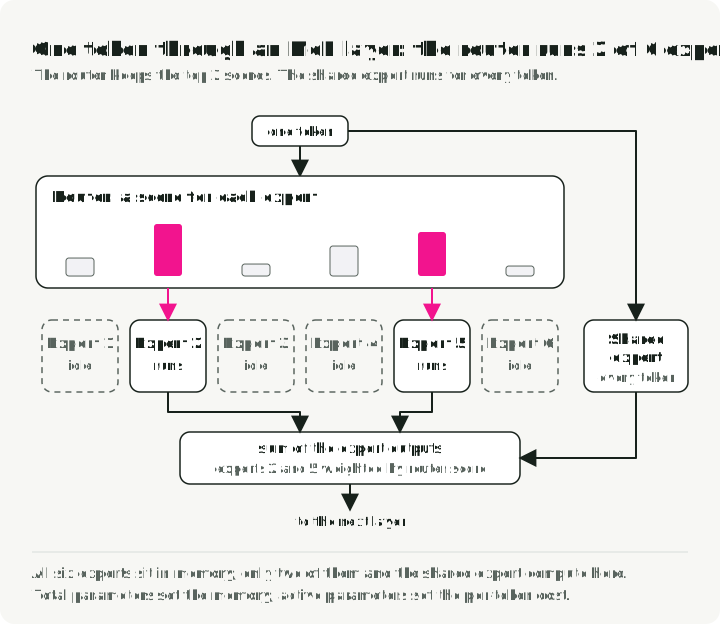
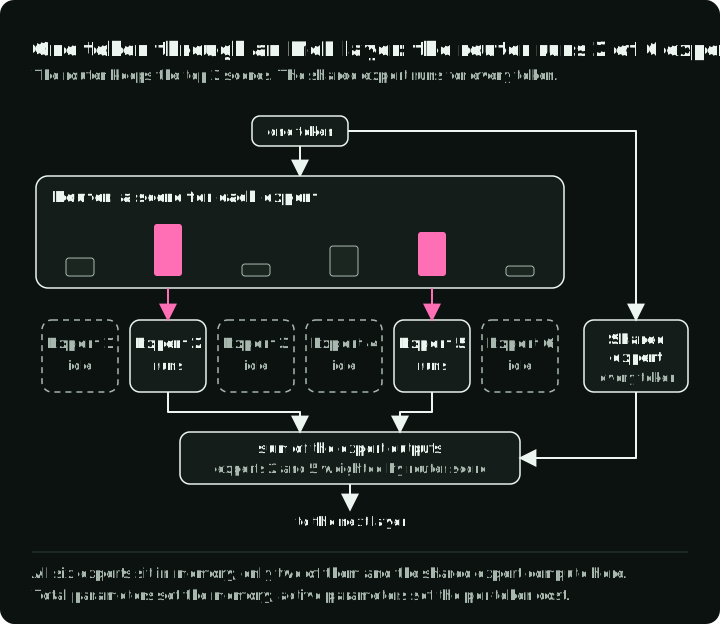
MoE replaces selected dense FFNs with multiple expert FFNs plus a lightweight gating router. The router computes a score for each expert (typically a softmax over learned linear projections) and selects the top- experts per token. Only the activated experts compute, so a model can have enormous total capacity while keeping per-token cost low. This is sparse conditional computation. Active parameters approximate per-token arithmetic, but all expert weights need storage. Communication, routing, batch occupancy, and KV memory also affect runtime cost. The figure follows one token through an MoE layer with six routed experts and a shared expert.
| Model | Total Params | Active Params | Experts (Routed + Shared) | Top- |
|---|---|---|---|---|
| Mixtral 8x7B | 47B | ~13B | 8 + 0 | 2 |
| DeepSeek-V3 | 671B | 37B | 256 + 1 | 8 |
The shared expert in DeepSeek-V3 is activated for every token. It provides a baseline representation that the routed experts can specialize on top of.
Training MoE has three recurring problems: load imbalance, expert collapse, and communication overhead for expert parallelism. Traditional MoE models add an auxiliary loss to penalize imbalanced routing, but that loss can compete with the main objective. DeepSeek-V3 primarily uses a batch-wise, auxiliary-loss-free strategy: bias terms outside backpropagation lower the score of overloaded experts and raise the score of underused ones. It also applies an extremely small complementary sequence-wise balance loss to prevent extreme imbalance within a sequence. The paper reports better routing balance without the main auxiliary-loss trade-off in its setup.
21. Tokenization: BPE, SentencePiece, and tiktoken
LLMs do not see text. They see sequences of integer token IDs. A tokenizer splits raw text into tokens (subword pieces) and maps each to an ID. The tokenizer choice affects model quality, inference speed, and multilingual fairness.
Byte Pair Encoding (BPE) is the common algorithm. It iteratively merges the most frequent adjacent pairs in the training corpus. A simplified example:
- Start with character-level vocabulary:
[l, o, w, e, r, _] - Most frequent pair is
(l, o)→ merge intolo→ vocabulary:[l, o, w, e, r, _, lo] - Next most frequent pair is
(lo, w)→ merge intolow→ vocabulary addslow - Continue until the vocabulary reaches the target size (e.g., 128K tokens)
Common words like “the” become single tokens, while rare words like “defenestration” get split into subword pieces like ["def", "en", "est", "ration"] in an invented illustration. Actual splits depend on the tokenizer and version. The trade is vocabulary size against sequence length.
Three tokenizer implementations cover most production use:
- SentencePiece trains directly on raw Unicode text without a language-specific pre-tokenizer. It preserves whitespace with the
▁meta-symbol and can optionally fall back to UTF-8 byte tokens. It supports both BPE and unigram models and is used by Llama 1/2, T5, and early Mistral tokenizers. Newer Mistral Tekken tokenizers use tiktoken-style BPE. - tiktoken is OpenAI’s Rust-based tokenizer using byte-level BPE. In its published GPT-2 benchmark, it ran 3–6x faster than the tested
GPT2TokenizerFastconfiguration. Llama 3 switched from SentencePiece to tiktoken’s algorithm. - Hugging Face Tokenizers is a widely used Rust-based library supporting BPE, WordPiece, and Unigram.
Vocabulary size varies widely between model families:
| Model | Tokenizer | Vocabulary size |
|---|---|---|
| GPT-2 | Byte-level BPE | 50,257 |
| Llama 2 | SentencePiece BPE | 32,000 |
| Llama 3 | tiktoken-style BPE | 128,256 |
| GPT-4o | tiktoken o200k_base | ~200K |
Within a comparable tokenizer-training setup, a larger vocabulary can mean fewer tokens for the same text, but a larger embedding matrix (the term in Section 18).
Fertility measures how many tokens a tokenizer produces per word or other chosen text unit. It varies with the exact tokenizer, language, script, normalization, domain, and sample. Measure it on representative traffic instead of extrapolating from one tokenizer or language.
22. Context windows and positional encodings
The context window limits the sequence of tokens available to a generation request. Chunked prefill and cached decode process only part of that sequence in a pass. APIs may also set separate input and output limits. Published limits include:
| Model | Published token limit | Year |
|---|---|---|
| Llama 1 | 2,048 | 2023 |
| Llama 3.1 | 128K | 2024 |
| GPT-4.1 | 1,047,576 | 2025 |
| Gemini 2.5 Pro | 1,048,576 input | 2025 |
GPT-4.1 also caps output at 32,768 tokens; Gemini 2.5 Pro caps output at 65,536. The Gemini row reports an input limit, while GPT-4.1 reports a context window, so these fields are not identical.
Attention compares every pair of visible tokens, but nothing in that comparison says how far apart they are. Without positional information, full self-attention cannot distinguish different word orders from the same set of tokens; per-token states follow the input permutation. A decoder’s causal mask gives some order signal, because each token sees only its prefix, but it does not provide explicit relative positions. Positional encodings add position and relative distance explicitly.
Three common approaches are:
-
RoPE (Rotary Position Embeddings) rotates query and key vectors by position-dependent angles so their dot product depends on relative position. The token content still determines the attention score; RoPE adds position information without learned absolute-position embeddings. It is used by open model families including Llama, Mistral, and Qwen.
-
ALiBi (Attention with Linear Biases) skips embedding modifications and adds a penalty directly to attention scores: the farther apart two tokens are, the larger the negative bias. It has no learned positional parameters. In the original paper, a 1.3B model trained with 1,024-token sequences performed comparably at 2,048 tokens to a sinusoidal-position model trained at 2,048. Behavior beyond the paper’s tested models and lengths is model-dependent.
-
YaRN (Yet another RoPE extensioN) extends a RoPE model beyond its training context. It groups frequency dimensions into three categories and scales each differently. In the paper’s same-recipe comparison with position interpolation, YaRN used 400 rather than 1,000 training steps (Appendix B.2). The abstract’s broader 10x-data claim uses a different comparison.
Part V — Training and alignment
This part distinguishes the objective that creates capabilities, the techniques that make training fit available hardware, and the methods that shape a model’s behavior afterward.
23. Pretraining, fine-tuning, and alignment
Pretraining for an autoregressive LLM uses self-supervised next-token prediction on a large corpus. Encoder models can use other objectives, such as masked-token prediction. Its compute spans many orders of magnitude; Llama 3 405B, for example, used FLOPs. Supervised fine-tuning (SFT) adapts the pretrained model to task-specific labeled data. RLHF / RLAIF uses preference data to shape behavior: a conventional RLHF pipeline collects comparisons, trains a reward model, then optimizes the policy. RLAIF substitutes AI-generated feedback for some human judgments. Section 31 covers distillation, a separate path in which an aligned teacher generates training data for a smaller student.
Compute depends on model size, sequence length, data volume, optimizer, and method. PPO also carries more model state than SFT because a typical setup includes policy, reference, reward, and critic models. I covered the full fine-tuning decision framework in LLM Fine-Tuning Guide.
24. LoRA and QLoRA: parameter-efficient fine-tuning
LoRA freezes the pretrained weights and injects trainable low-rank matrices () and () so that the updated weight is . The LoRA paper reduced GPT-3 175B to about 18 million trainable parameters in its setup. Rank is a tuning parameter rather than a task-complexity rule; select it with a quality and memory sweep. LoRA adapters can be merged into the base weights after training to avoid a separate adapter path at inference.
QLoRA loads the base model in 4-bit NF4 quantization while training LoRA adapters in BF16. NormalFloat4 places more quantization levels near zero, where weight density is highest. The paper fine-tuned a 65B model on a single 48 GB GPU and reported results close to its 16-bit baselines. Its runtime and memory trade-offs are specific to the tested stack.
25. Mixed-precision training
Every floating-point format allocates its bits across three fields: sign (always 1 bit), exponent (sets the dynamic range), and mantissa (sets the precision). More exponent bits mean a wider range of representable magnitudes; more mantissa bits mean finer distinctions between nearby values. Integer formats have no exponent at all and represent only evenly spaced whole numbers within a fixed range.
| Format | Bits | Layout (S / E / M) | Range | Precision | Common use |
|---|---|---|---|---|---|
| FP32 | 32 | 1 / 8 / 23 | ~7 decimal digits | Master weights, optimizer states (Adam momentum & variance) | |
| BF16 | 16 | 1 / 8 / 7 | ~2 decimal digits | Preferred training format; same range as FP32 and usually no loss scaling | |
| FP16 | 16 | 1 / 5 / 10 | ~3 decimal digits | Training with loss scaling (older GPUs); inference on pre-Hopper hardware | |
| FP8 E4M3 | 8 | 1 / 4 / 3 | ~1 decimal digit | Forward pass on Hopper (H100) — more precision for weights & activations | |
| FP8 E5M2 | 8 | 1 / 5 / 2 | ~0.6 decimal digits | Backward pass on Hopper — wider range for gradients | |
| INT8 | 8 | signed integer | to | Exact integers | Post-training weight quantization for inference (W8A8); KV cache quantization |
| INT4 | 4 | signed integer | to | Exact integers | Aggressive weight-only quantization (AWQ, GPTQ) for inference on memory-constrained hardware |
BF16 has the same range as FP32 because range is set by the exponent field, and BF16 keeps all 8 exponent bits from FP32. It gives up mantissa bits instead (7 vs 23), trading precision for a 2x memory reduction while avoiding many range problems that affect FP16 training. FP16 has only 5 exponent bits, capping its finite range at about 65K. Many gradients are instead too small for FP16 and underflow toward zero. Loss scaling multiplies the loss before backpropagation so those gradients remain representable, then unscales them before the optimizer step; dynamic scaling lowers the factor if overflow occurs. BF16’s wider exponent range usually avoids this requirement.
Integer formats are uncommon for the main training arithmetic because backpropagation needs a wide dynamic range. They are widely used for inference, where frozen weights can be mapped to calibrated scales. INT4 weight quantization cuts a 7B model from about 14 GB to 3.5 GB before runtime overhead; quality must be measured for the chosen model and method.
FP8 training on H100 via Transformer Engine uses E4M3 where precision matters and E5M2 where wider range matters. The FP8-LM paper reports that its mixed-precision framework trained GPT-175B 75% faster than its BF16 Megatron-LM baseline and 37% faster than NVIDIA Transformer Engine under the tested H100 setup. DeepSeek-V3 used FP8 mixed precision and reported about $5.6 million in rental-equivalent compute for its final training run, excluding R&D and infrastructure.
26. Gradient checkpointing
Each layer of the forward pass produces an intermediate output called an activation:
Normally all activations have to stay in memory because backpropagation needs them to compute gradients. For a deep transformer, the stored activations can take more memory than the model weights themselves.
Gradient checkpointing trades compute for memory by throwing most of those activations away and recomputing them on the fly during backprop. The standard strategy (Chen et al., 2016) divides a network of layers into evenly spaced segments and saves only the boundary activation of each segment. Those saved boundaries are the “checkpoints.” All intermediate activations within a segment are dropped immediately.
When the backward pass reaches a layer inside a segment, its activations are recomputed from the nearest checkpoint. For the evenly segmented strategy, saved activation memory drops from to . Each segment is recomputed once, which costs about one extra forward pass per training step (Chen et al., 2016). Actual memory savings and recomputation overhead depend on the model, checkpoint boundaries, sequence length, framework, and implementation, so measure both on the target training run. FlashAttention applies the same principle inside attention by not materializing the full attention matrix. For ordinary Hugging Face Trainer runs, enable it with gradient_checkpointing=True. With FSDP, use the framework’s activation-checkpointing integration where supported; the generic option can cause redundant backward all-gathers.
27. DeepSpeed ZeRO stages
In standard data parallelism, every GPU holds a complete copy of the model weights, gradients, and optimizer states. For Adam, each parameter takes 2 bytes for the FP16 weight + 4 bytes for the FP32 master weight + 4 bytes for momentum + 4 bytes for variance + 2 bytes for the gradient, which is 16 bytes per parameter. A 7.5B-parameter model needs ~120 GB per GPU, and every GPU stores the same thing. On 64 GPUs that is 64 identical 120 GB copies.
DeepSpeed ZeRO (Zero Redundancy Optimizer) removes this duplication by sharding these components across GPUs instead of replicating them:
- Stage 1 — partition optimizer states. Each GPU stores only 1/N of the optimizer states (the FP32 master weights plus Adam’s first and second moments, 12 bytes/param). When a GPU needs to update a weight, it updates only its slice and broadcasts the result. Under the assumptions below, memory drops from ~120 GB to ~41.3 GB per GPU.
- Stage 2 — also partition gradients. Gradients (2 bytes/param) are no longer all-reduced to every GPU. Each GPU receives only the gradient slice it needs via reduce-scatter. Under the same assumptions, memory drops to ~28.1 GB per GPU.
- Stage 3 — also partition the model weights. Each GPU holds only 1/N of the FP16 weights. Before each layer’s forward or backward pass, the GPU calls all-gather to temporarily reconstruct the full layer weights from all other GPUs, computes, and discards the gathered weights. Under the same assumptions, memory drops to ~15.0 GB per GPU.
The figure draws the per-GPU model state at each stage to scale, with the communication cost of each stage.
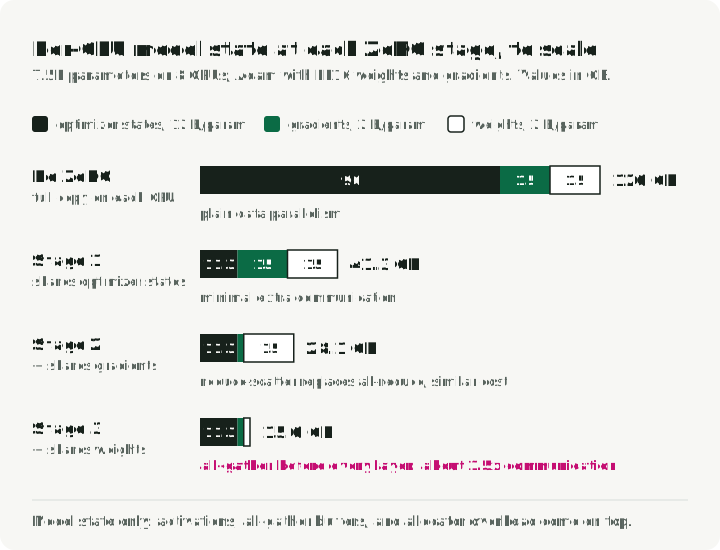
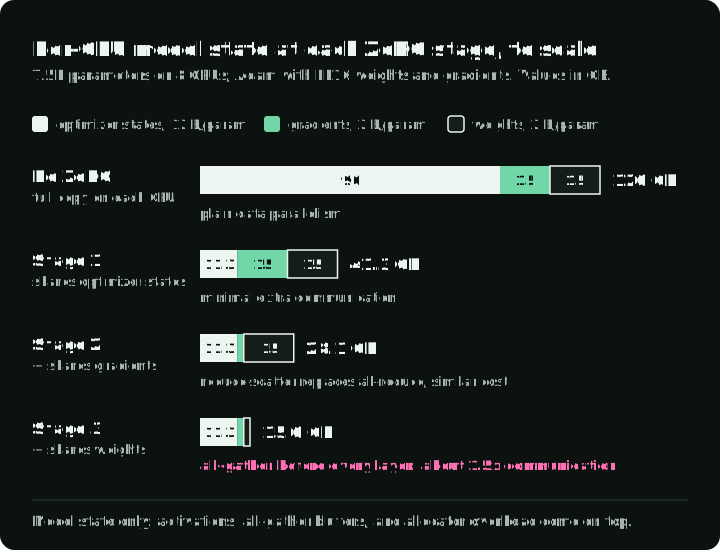
These are approximate model-state values for a 7.5B-parameter model on 8 GPUs (world size ), with FP16 weights and gradients and FP32 Adam master weights, momentum, and variance. They exclude activations, temporary all-gather buffers, allocator fragmentation, and framework/runtime overhead. The calculation boundary is bytes per parameter, with each state divided by only at the stages that shard it.
To repeat the calculation for another model size or GPU count:
def zero_model_state_gb(params_b, n_gpus, stage):
    """Model-state GB per GPU for Adam with FP16 weights and gradients.

    Optimizer states (FP32 master weights, momentum, variance) take 12 bytes
    per parameter, gradients 2, and weights 2. Stage 1 shards the optimizer
    states, stage 2 also the gradients, and stage 3 also the weights.
    """
    optimizer, gradients, weights = 12, 2, 2
    if stage >= 1:
        optimizer /= n_gpus
    if stage >= 2:
        gradients /= n_gpus
    if stage >= 3:
        weights /= n_gpus
    return params_b * (optimizer + gradients + weights)

for stage in range(4):
    print(f"stage {stage}: {zero_model_state_gb(7.5, 8, stage):g} GB per GPU")

assert [zero_model_state_gb(7.5, 8, s) for s in range(4)] == [120.0, 41.25, 28.125, 15.0]
# 70B parameters: Stage 3 on 8 GPUs still needs 140 GB of model state per GPU;
# 16 GPUs bring it to 70 GB, before activations.
assert zero_model_state_gb(70, 8, 3) == 140.0
assert zero_model_state_gb(70, 16, 3) == 70.0
The tradeoff is communication. Stage 1 adds minimal overhead, and Stage 2 replaces all-reduce with reduce-scatter at similar cost. Stage 3 needs all-gather calls before every layer in both the forward and backward passes, roughly 1.5x communication volume versus standard data parallelism.
ZeRO-Infinity extends Stage 3 by offloading partitioned states to CPU RAM and even NVMe SSDs, which can make training models with trillions of parameters possible on limited GPU clusters. Storage offload adds PCIe and storage-transfer cost; its measured impact depends on the drive, PCIe topology, partitioning, prefetch, transfer overlap, and workload. Use it to satisfy capacity requirements rather than assuming a fixed slowdown, and profile the target configuration.
28. FSDP: PyTorch-native sharding
Fully Sharded Data Parallel (FSDP) is PyTorch’s built-in answer to DeepSpeed ZeRO-3. It shards parameters, gradients, and optimizer states across GPUs with the same core idea. With full sharding and resharding enabled, the operations for each wrapped unit are:
- All-gather the full parameters from all GPUs (temporarily reconstruct the complete layer).
- Compute the forward or backward pass for that layer.
- Free the gathered parameters immediately. Each GPU keeps only its own shard.
- Reduce-scatter gradients so each GPU gets only its assigned gradient slice.
Because FSDP is native to PyTorch, it integrates directly with PyTorch debugging tools, profilers, and torch.compile. Performance relative to DeepSpeed ZeRO-3 depends on wrapping policy, communication topology, offload settings, and model size, so compare them on the same cluster.
| Criteria | FSDP (PyTorch) | DeepSpeed ZeRO |
|---|---|---|
| Control style | Full sharding through PyTorch APIs | Selectable ZeRO stages |
| Offloading | CPU offloading | CPU + NVMe with ZeRO-Infinity |
| Framework integration | Native PyTorch, torch.compile paths | Separate library and config system |
| Selection test | Profile the target PyTorch workload | Profile required features and offload |
FSDP2 (2024–2025) is a rewrite that improves torch.compile integration for better kernel fusion, adds FP8 training support via TorchAO, and simplifies the API. Both FSDP and DeepSpeed are accessible through HuggingFace Accelerate, which supports both through configuration for compatible, prepared training scripts. Required wrapping, checkpointing, and offload settings still differ.
29. Scaling laws and inference cost
Chinchilla scaling (DeepMind, 2022) found a compute-optimal allocation near 20 training tokens per parameter under its assumptions. That objective does not include downstream serving cost. If a smaller model trained on more data reaches the required quality, it may cost less over a high-volume inference lifecycle.
One lifecycle-cost strategy is to train a smaller model on much more data:
| Model | Params | Training Tokens | Tokens/Param | Tokens/param ÷ 20 (derived) |
|---|---|---|---|---|
| Chinchilla | 70B | 1.4T | 20:1 | 1× |
| Llama 1 | 65B | 1.4T | 22:1 | 1× |
| Llama 2 | 70B | 2.0T | 29:1 | 1.4× |
| Llama 3 8B | 8B | 15T | 1,875:1 | 94× |
| Qwen3-0.6B | 0.6B | 36T | 60,000:1 | 3,000× |
This is the displayed tokens-per-parameter ratio divided by the Chinchilla paper’s approximate 20-token-per-parameter point. It is a descriptive ratio, not a measured quality or cost multiplier.
For a model served at high volume, spending more training compute on a smaller model can reduce lifecycle cost. Llama 3 8B illustrates the strategy, but whether it wins depends on the required quality and projected inference volume. “Chinchilla-optimal” refers to training-compute efficiency, which is a different objective from lifecycle cost.
30. RLHF, DPO, GRPO, and the alignment landscape
Alignment steers a pretrained model toward desired instructions, preferences, and safety policies. It does not by itself guarantee truthfulness or safe behavior. The methods below trade off implementation complexity, data requirements, exploration, and training stability.
The classic RLHF pipeline: SFT → collect human preference pairs → train a reward model on those pairs → fine-tune the policy with PPO (Proximal Policy Optimization). A conventional PPO setup has four model roles: policy, reference, critic/value model, and reward model. Their memory use depends on sharing, sharding, precision, offload, and placement; four roles do not imply four complete GPU-resident copies. PPO is also hyperparameter-sensitive. It is also prone to reward hacking, where the model exploits quirks in the reward model, such as verbose, confident-sounding answers, instead of genuinely improving quality.
DPO (Direct Preference Optimization) skips the learned reward model and online RL loop by optimizing a loss on preference pairs directly. That simplifies the training pipeline. Standard DPO is offline: it trains on a fixed dataset and does not explore new responses during the update loop. Whether that limitation matters depends on the task and data coverage.
GRPO (Group Relative Policy Optimization, DeepSeek) removes PPO’s learned critic by generating multiple completions per prompt and using group-relative rewards as the baseline. This reduces the model-state burden relative to a typical PPO setup. Unlike DPO, GRPO is on-policy: the model generates fresh responses during training. DeepSeek-R1 combines GRPO with RLVR (reinforcement learning from verifiable rewards), using checks such as math answers, code compilation, and unit tests. These rewards are easier to audit than a learned preference score, but incomplete tests and proxy objectives can still be exploited.
| Method | Model roles in a conventional setup | Reward signal | Online/offline | Key limitation |
|---|---|---|---|---|
| PPO | Policy, reference, critic, reward | Learned reward model | Online | Reward hacking, complex tuning |
| DPO | Policy plus reference scores, which can be precomputed | Implicit (preference pairs) | Offline | No exploration, fixed data |
| GRPO | Policy; optional reference for KL and optional learned reward | Explicit (rule/verifier or learned) | Online | Depends on reward quality and informative within-group variation |
The reference policy in GRPO is implementation-dependent. For example, TRL GRPOTrainer does not load a reference model when its KL coefficient beta is zero. Include model placement and precision when comparing training memory.
31. Distillation: compressing knowledge across models
Knowledge distillation transfers capabilities from a large teacher to a smaller student. Logit-based distillation trains the student to match the teacher’s output distribution. Data-based distillation has the teacher generate examples that the student fine-tunes on. Data-based methods are common for LLMs because they can work across architectures and with API-only teachers, but their value is bounded by teacher quality, data coverage, filtering, and generation cost.
DeepSeek-R1 curated an approximately 800,000-example mixture—about 600,000 reasoning-related samples and 200,000 non-reasoning samples—and used it to distill Qwen2.5 and Llama 3 models from 1.5B to 70B parameters. In the paper’s evaluation:
- DeepSeek-R1-Distill-Qwen-32B scores 72.6% on AIME 2024 and 94.3% on MATH-500, above the paper’s reported OpenAI o1-mini numbers.
- DeepSeek-R1-Distill-Qwen-7B scores 55.5% on AIME 2024, above the paper’s QwQ-32B-Preview result with a smaller model.
In DeepSeek-R1’s small-model experiments, distillation outperformed direct GRPO on the tested base models. That result supports distillation for this setup; it does not establish a universal ranking between distillation and RL.
32. Synthetic-data generation
LLM-generated training data is used in several recurring patterns:
- Self-Instruct bootstraps from a small seed set of human-written instructions: the LLM generates new instructions, inputs, and outputs, which are filtered and added back to the pool. The Alpaca project used 52,000 examples generated from 175 seeds. Stanford reported data generation under $500 and fine-tuning under $100, putting the initial reproduction cost under $600; its GPT-3.5 comparison was a limited project evaluation, not broad equivalence.
- Evol-Instruct (WizardLM) takes existing instructions and iteratively evolves them along complexity axes (adding constraints, deepening reasoning, making problems more concrete) to produce progressively harder training examples.
- Microsoft’s Phi-4 (14B) used synthetic data for much of pretraining, including generation, critique, self-revision, and instruction reversal. Its technical report compares the resulting STEM and coding performance with larger models on the selected benchmarks.
One risk is model collapse under recursive replacement of real data with generated data. In the studied settings, rare parts of the original distribution progressively disappear (Shumailov et al., published in Nature in 2024). This is not an inevitable result of all synthetic-data use. A separate accumulation study found different behavior when real and generated data were retained across generations. A separate Ahrefs classifier study sampled one newly detected English page per domain from 900,000 pages in April 2025 and classified 74.2% as containing some AI-generated text. That vendor study is not a census of the web. Mitigation starts with blending synthetic and real data, filtering, and lineage tracking so recursively generated material can be measured.
Part VI — Scaling and deployment
Once a workload no longer fits or meets its SLO on one device, the choices are how to split work, which runtime exposes the needed controls, and whether every request needs the same model.
33. Four forms of parallelism
The four forms differ in which part of the model each GPU holds and in what crosses the link between GPUs. The figure shows each one on two GPUs.
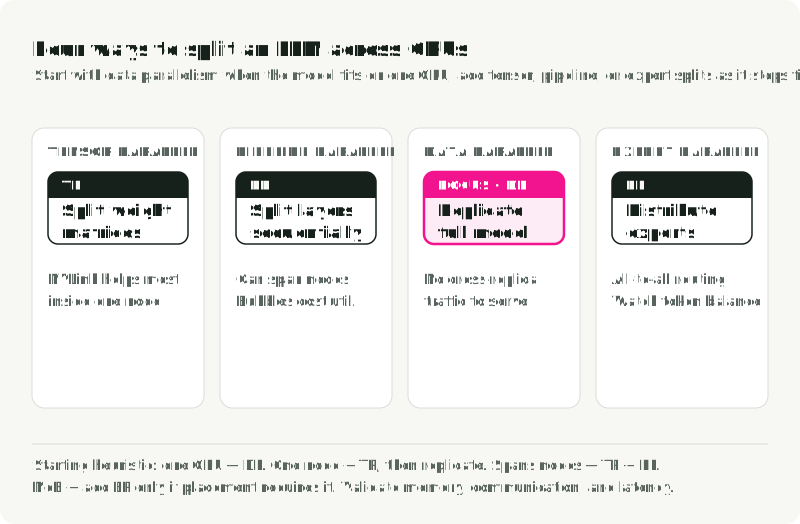
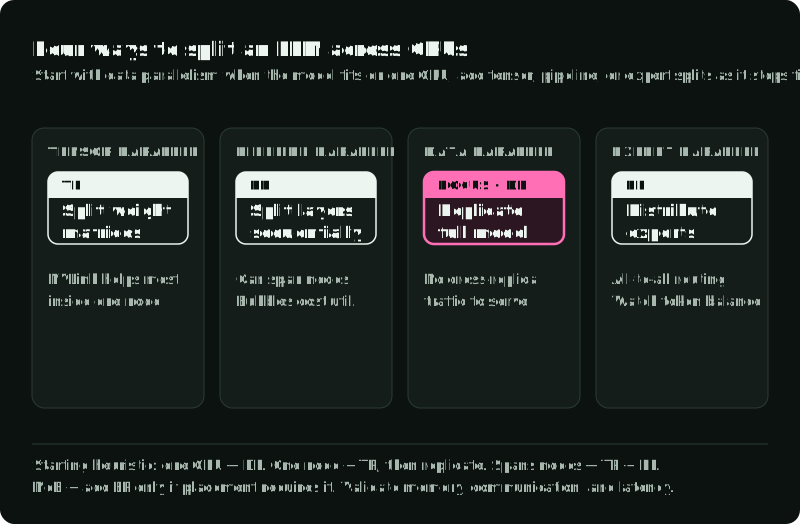
Tensor Parallelism (TP) splits individual weight matrices across GPUs and usually communicates after each layer. Fast intra-node links such as NVLink make it most practical within a node. More shards reduce per-device memory and compute but increase communication, so select the degree with a latency benchmark.
Pipeline Parallelism (PP) splits layers sequentially across GPUs, passing activations between stages. Its communication pattern can work across nodes, but pipeline bubbles and uneven stage times reduce utilization. Large deployments often combine TP within a node and PP across nodes.
Data Parallelism (DP) replicates the serving model so each replica handles independent requests without per-request cross-replica communication. It is efficient when the model fits and traffic can be balanced. In training, DP is commonly combined with ZeRO or FSDP to shard state.
Expert Parallelism (EP) distributes MoE experts across GPUs using all-to-all communication for token routing. Its performance depends on token balance, expert placement, and interconnect topology; all-to-all traffic can become the dominant bottleneck.
A starting parallelism heuristic:
- Model fits on one GPU: begin with independent replicas and measure DP scaling.
- Model fits within one node: test TP within the node, then replicate the group if traffic requires it.
- Model spans nodes: test a TP and PP combination against the interconnect and latency target.
- Mixture of experts: add EP only when expert placement requires it.
34. Serving frameworks compared
The runtime decides which of the optimizations in Part III you get without writing kernels. Use the table to pick the first one to benchmark, then compare it with one alternative on the same prompts, output lengths, hardware, and SLO.
| Runtime | Use it when | Check first |
|---|---|---|
| vLLM | General GPU serving with an OpenAI-compatible API | The target model and GPU in the current compatibility matrix |
| SGLang | Traffic shares long prefixes (system prompts, multi-turn chat, agents) or needs structured output | Prefix-cache hit rate on your own traffic |
| TensorRT-LLM | The fleet is NVIDIA-only and the lowest latency matters more than portability | Support for your model and precision (FP8, FP4) |
| llama.cpp | CPU, Apple silicon, or a single consumer GPU, with GGUF quantized models | Tokens per second from its benchmark tool on the target machine |
| Ollama | Local development and demos | Move to a serving runtime before high concurrency or SLO work |
The same benchmark starting points as an ordered list:
- One local machine or one consumer GPU: start with llama.cpp, or Ollama for development.
- NVIDIA only and latency is the priority: include TensorRT-LLM in the benchmark.
- Long shared prefixes or structured output: SGLang.
- Otherwise: vLLM.
Benchmark the first choice on your prompts, output lengths, hardware and SLO.
vLLM provides paged KV allocation, continuous batching, an OpenAI-compatible API, and several parallelism modes. Its model and hardware support changes often.
SGLang combines RadixAttention for prefix reuse, a custom scheduler, and structured generation. Its published throughput gains depend on workload and configuration.
TensorRT-LLM targets low single-request latency through CUDA graph capture and replay, which reduce launch overhead, and kernel optimization, including fusion, with native FP8/FP4 support. Earlier releases such as v1.2.0 supported an ahead-of-time TensorRT engine build. NVIDIA’s current migration guide specifies PyTorch as the sole backend: its LLM API and trtllm-serve load a Hugging Face checkpoint directly, without an engine-build step. Its published numbers are hardware- and model-specific, and it runs only on NVIDIA GPUs.
TGI was archived on March 21, 2026, and its repository is read-only. Its README recommends vLLM, SGLang, llama.cpp, or MLX for new deployments.
Ollama emphasizes a simple local model workflow.
llama.cpp is a portable C/C++ runtime with ARM, x86, Metal, CUDA, ROCm, and Vulkan paths. GGUF supports several quantization levels. Performance varies widely by model, quantization, context, and backend.
35. GPU selection for inference
The table compares published hardware characteristics. Vendor precision support does not make peak-compute figures directly comparable across formats, so select by memory fit first and benchmark the target workload. Check current cloud prices separately because they vary by provider, region, commitment, and availability.
| GPU | Memory | Bandwidth | Native low precision | NVLink per GPU |
|---|---|---|---|---|
| B200 SXM | 180 GB HBM3e | Up to 8 TB/s | FP4, FP8 | 1.8 TB/s |
| H200 SXM | 141 GB HBM3e | 4.8 TB/s | FP8 | 900 GB/s |
| H100 SXM | 80 GB HBM3 | 3.35 TB/s | FP8 | 900 GB/s |
| A100 80 GB SXM | 80 GB HBM2e | 2.039 TB/s | INT8 (no FP8) | 600 GB/s |
| L40S | 48 GB GDDR6 | 864 GB/s | FP8 | None |
| A10G (AWS G5) | 24 GB GDDR6 | 600 GB/s | INT8 (no FP8) | None |
| RTX 4090 | 24 GB GDDR6X | ~1 TB/s | FP8 | None |
The A10G row uses NVIDIA’s A10 specification as a bandwidth proxy; the linked AWS G5 specification does not establish the exact A10G bandwidth. The RTX 4090 figure (1,008 GB/s) comes from the Ada architecture whitepaper.
H200’s 141 GB capacity can simplify some large-model deployments. The GDDR cards in the lower rows have a third or less of H100 bandwidth and no NVLink, so they suit quantized models that fit on one GPU better than models that need tensor parallelism.
AWQ and GPTQ serve 4-bit models by dequantizing supported matrix operations into a compute format such as FP16 or BF16. Compatibility and speed still depend on the model architecture, quantization format, serving backend, kernel, and GPU, so check the backend’s support matrix and benchmark the exact artifact. All listed GPUs support INT8 matrix operations.
LLM decode is often memory-bandwidth-bound, so HBM capacity and bandwidth can matter more than peak TFLOPS for serving workloads. Compare GPUs with the model, precision, batch distribution, context length, and latency target held constant.
36. Model cascading and routing
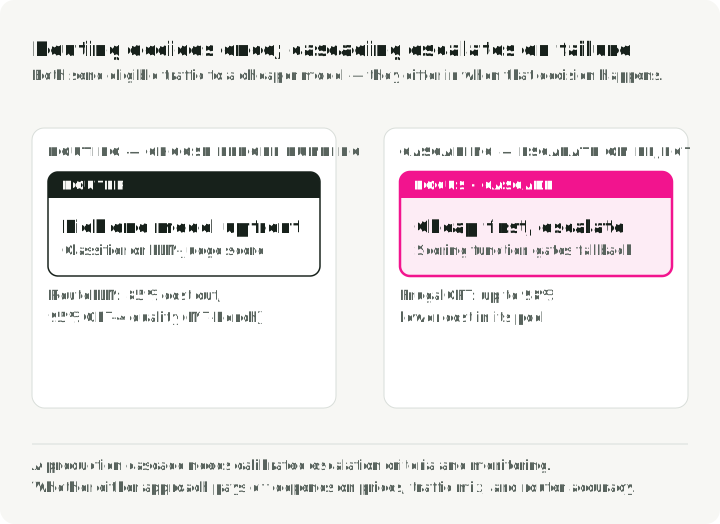
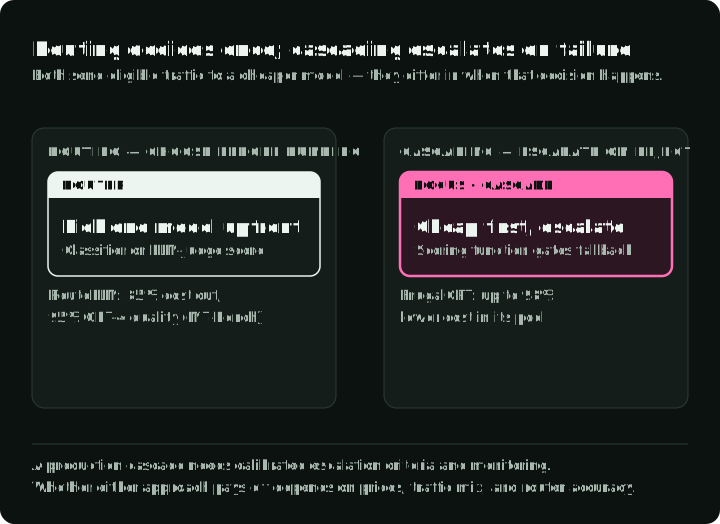
Model routing picks which LLM handles each query based on predicted complexity or capability. RouteLLM (LMSYS/UC Berkeley, ICLR 2025) reports a 3.66x cost ratio at 95% of the GPT-4-Turbo baseline score on MT-Bench in Table 6. This corresponds to about 73% lower modeled cost under that experiment’s prices, weak model, and scoring setup. Whether routing pays off depends on current prices, the traffic mix, router errors, and the quality floor.
Routers range from lightweight classifiers to LLM-based judges. Cascading is the sequential variant: a query starts with a cheaper model and escalates when a scoring function rejects the answer. FrugalGPT reports up to 98% lower cost or up to 4% higher accuracy in its evaluated model pool. A production cascade needs calibrated escalation criteria and monitoring for the queries the cheap model accepts incorrectly. The figure shows where each approach makes its choice and where each one fails.
Part VII — Applications
Applications fail in places the serving stack does not see. Retrieval can fail before generation begins, agents can choose an invalid action, and a prompt change can improve one task while breaking another.
37. Embedding models vs generative models
Embedding models encode text into fixed-dimensional vectors that capture semantic meaning. The single-vector models compared below output one dense vector per input, commonly with a few hundred to several thousand dimensions. Other retrieval architectures can keep several token-level vectors; the following storage comparison concerns single-vector embeddings. Their backbones include bidirectional encoder-only transformers and decoder-derived models adapted for representation learning. A pooling layer often collapses per-token representations into one vector through mean pooling, a special classification token, or a model-specific last-token method. Contrastive fine-tuning then pushes semantically similar texts closer together and dissimilar texts farther apart.
Current embedding models differ in the properties that set storage cost and index choice: output dimensions, accepted input types, deployment, and output precision.
| Model | Max dimensions | Input | Weights | Native output precision |
|---|---|---|---|---|
| Qwen3-Embedding-8B | 4,096 (32–4,096 via MRL) | Text | Open (Apache 2.0) | Float |
| Gemini Embedding 2 | 3,072 (128–3,072) | Text, image, video, audio, PDF | API | Not stated |
| pplx-embed-v1-4B | 2,560 (MRL) | Text | Open (MIT) | INT8 and binary |
| OpenAI text-embedding-3-large | 3,072 (shortened via dimensions) | Text | API | Float |
These are examples, not a ranking. Evaluate language, modality, task, dimension, and serving cost on one retrieval set.
Matryoshka Representation Learning (MRL, Kusupati et al., NeurIPS 2022) makes embedding dimensions flexible. Named after Russian nesting dolls, MRL trains selected embedding prefixes to retain useful information. Its experiments compare these prefixes with separately trained smaller representations; matching their quality is an empirical result, not a guarantee for every task. During training, MRL aggregates losses over a chosen set of prefix dimensions, usually consistent halvings; the paper’s 2048-dimensional example uses . The aggregated loss pushes the leading dimensions to carry coarse semantic information, with later dimensions adding finer detail.
After training, an MRL embedding can be truncated to a supported prefix dimension. OpenAI reports that text-embedding-3-large at 256 dimensions outperforms text-embedding-ada-002 at 1,536 dimensions on its cited MTEB comparison. That gives a 6x reduction in raw vector storage; search latency and database cost also depend on the index, metadata, filtering, and hardware.
The embedding model is one important component in a RAG pipeline, alongside parsing, chunking, search, reranking, and generation. If relevant evidence is not retrieved, a stronger generator cannot reliably recover it.
38. RAG architecture in production
Retrieval-Augmented Generation supplies an LLM with documents retrieved at query time. It can provide current or private evidence that is absent from model weights, but retrieval does not guarantee that the answer uses that evidence correctly. A production RAG system is a multi-stage pipeline whose stages need separate evaluation. The figure shows the offline ingestion path, the per-query path, and where the three failure modes listed below occur.
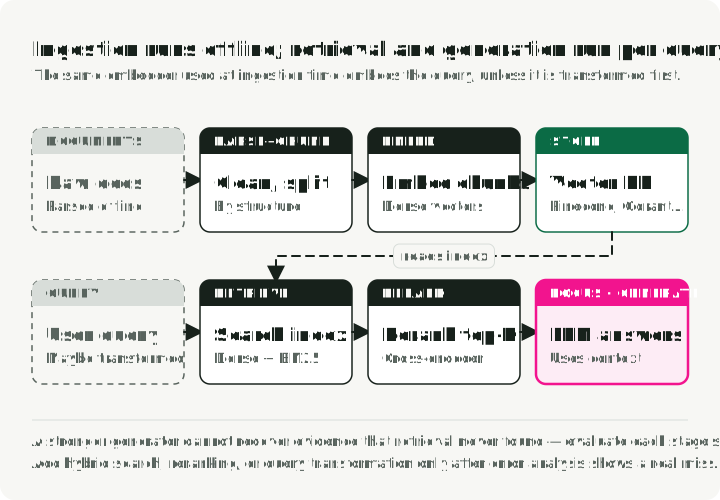
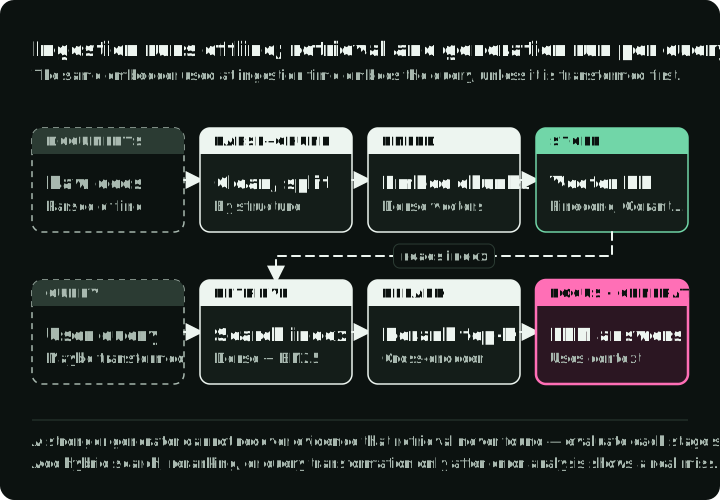
The ingestion pipeline runs offline. Raw documents (PDFs, HTML, Markdown, databases) are first parsed into clean text. PDF parsing can lose tables, headers, and formatting. The text is then split into chunks, which are embedded and indexed independently.
Chunking affects both retrieval recall and the context available to the generator. Useful sizes depend on document structure, query granularity, embedder limits, and reranker limits. Common approaches are fixed-size with overlap, recursive splitting along document boundaries, and semantic chunking by embedding similarity. Compare them on page- or section-level relevance labels instead of adopting one token range universally.
Each chunk is then embedded with a model like those in Section 37 and stored in a vector index. pgvector keeps vectors in a Postgres database you already run. A dedicated store such as Qdrant, Weaviate, or Pinecone adds built-in hybrid search and scales the index separately from the application database.
The retrieval pipeline runs at query time. Start with a measurable baseline, then add stages when error analysis shows they address a real miss:
- Hybrid search combines dense vector retrieval with sparse retrieval such as BM25, often merged through Reciprocal Rank Fusion (RRF). Dense search handles semantic paraphrases; sparse search catches exact identifiers, error codes, and acronyms. Vendor benchmarks report gains over vector-only baselines, but the size depends on the corpus and relevance labels.
- Reranking passes retrieved candidates through a model that scores the query and document together. This can improve fine-grained relevance at the cost of another model call. Candidate count, retained count, and latency should be tuned together. I covered the full multi-stage pipeline in Building a Modern Search Ranking Stack.
- Query transformation rewrites the user’s query before retrieval to improve recall. HyDE (Hypothetical Document Embeddings) has the LLM generate a hypothetical document, which is embedded and used to retrieve real documents. The generated text is a search representation, not verified answer evidence. Multi-query expansion generates multiple phrasings of the same question. Step-back prompting asks a more general question first to retrieve or reason from higher-level principles.
The common failure modes:
- Retrieval failure — the correct document exists but is not retrieved. Test chunking, query transformation, hybrid search, and metadata filtering against the miss.
- Context poisoning — irrelevant retrieved chunks mislead the LLM. Test reranking, context filters, and smaller retained sets.
- Lost-in-the-middle — in the tested multi-document question-answering and key-value retrieval settings, Liu et al. found answer performance was generally highest when relevant information appeared near the beginning or end of the input and lower when it appeared in the middle.
GraphRAG (Microsoft, 2024) extracts entities and relationships, detects graph communities, and builds community summaries. Its global-search method answers corpus-level questions from those summaries; it is not simply vector retrieval with a graph added. The trade-off is additional extraction, indexing, storage, and evaluation work.
Practitioner guides publish latency ranges for embedding, search, reranking, and generation, but those figures vary by region, corpus, hardware, and model. Measure each stage in traces and evaluate the quality change before accepting the added latency.
39. Agent architectures and tool calling
LLM agents use models to select and sequence tool calls around an evolving state. Three useful orchestration patterns are:
- ReAct — interleaves action selection with observations. It can adapt after each tool result, but a growing history raises token and latency cost.
- ReWOO — plans tool calls with placeholders and explicit result dependencies, then executes the plan and synthesizes. Only independent calls can run in parallel; a call that refers to an earlier result must wait for it. Its paper reports token savings over ReAct, but the fixed plan needs an explicit recovery path when a tool fails.
- Planner-executor — separates planning from execution and can add a re-planning policy after failure. It allows a different model for each role, but adds plan state and a second model call that can fail.
| Pattern | Repeated model work | Adaptability | Useful starting point |
|---|---|---|---|
| ReAct | Reads observations before the next action | Updates after observations | Uncertain or exploratory tool use |
| ReWOO | Reuses a plan with explicit dependencies | Fixed plan unless extended | Work that can be planned before tool results |
| Planner-executor | Plans, executes, and may re-plan | Can revise the explicit plan | Longer tasks that benefit from control |
The figure draws the three patterns, so you can see where each one plans and whether it has a path back after a tool result.
Function calling is a common mechanism for tool invocation. APIs expose tool definitions and return structured arguments, reducing the need to parse free-form text. Schema-valid arguments can still select the wrong tool or contain invalid values. Parallel function calling can reduce round trips when operations are independent.
Structured output and constrained decoding enforce a schema by restricting the tokens available at each generation step. Engines such as xgrammar, used in vLLM and SGLang, can remove many syntax and parsing failures with low overhead in supported configurations. They do not guarantee that the extracted values or decisions are correct. Schema-Guided Reasoning (SGR) uses field order and schema structure to make intermediate state inspectable before the final decision. Its three patterns are Cascade (sequential steps), Routing (union types as semantic switches), and Cycle (bounded lists).
A larger tool set and deeper action sequence can reduce selection quality and increase latency or token cost. Measure those curves with the actual tool descriptions and failure distribution. Frameworks such as LangGraph can make state and recovery paths explicit, but they do not remove the evaluation burden.
40. Prompt engineering for production
Production prompting is an evaluation problem: change one part of the prompt or context, then measure task quality and failure modes. The techniques below are common starting points, not a universal order.
Few-shot examples are often effective for controlling output format. Start with 3–5 examples that cover empty inputs, ambiguous queries, and multi-part answers, then measure the result on a held-out set. Examples should span the real input distribution rather than only the happy path. More examples consume context and do not guarantee further gains.
Chain-of-thought (CoT) prompting asks a model to expose intermediate reasoning before answering. Kojima et al. (2022) reported gains from the suffix “Let’s think step by step” on their tested reasoning tasks, but the effect varies by model and newer reasoning APIs may not expose hidden traces. For production, prefer an inspectable task decomposition or concise rationale when it is useful to the evaluator. Self-consistency (Wang et al., 2023) samples several reasoning paths and aggregates the answers, trading extra inference cost for robustness on suitable tasks.
Structured output with explicit JSON schemas (Section 39) removes many parsing failures. Constrained decoding engines such as xgrammar can enforce the supported grammar during generation; factual accuracy and semantic validity still require evaluation, and unsupported schema features may still need handling.
Prompt chaining breaks a task into focused stages, for example classify intent → retrieve context → generate response → validate output. It can localize failures, allow different models per stage, and expose cacheable intermediate state. It also adds interfaces and latency, so compare it with a single-call baseline.
Temperature changes the sampling distribution. Low values are a reasonable starting point for classification or extraction; higher values can increase diversity for ideation. Exact behavior differs across model APIs and interacts with top_p, top_k, and provider defaults, so sweep the supported settings on the task rather than copying one range.
System vs user message separation keeps persistent policy apart from per-request content. Chat templates and instruction tuning give these roles different priority, but they do not make a system message an enforcement boundary. Put stable behavior in the system message, keep untrusted data in user or tool content, and enforce hard constraints such as PII removal outside the model as well.
Context engineering expands prompt work to the assembly of retrieved documents, tool results, conversation history, and examples. Liu et al. found a lost-in-the-middle effect in the long-context models they tested, so position should be part of the evaluation rather than assumed irrelevant. I covered the broader workflow in Context Engineering for AI Agents.
Part VIII — Production operations
Production operations turns the earlier concepts into admission limits, load tests, alerts, and capacity decisions under real traffic.
41. Rate limiting for variable-cost requests
Traditional requests-per-second rate limiting assumes roughly equal cost per request. LLMs break that assumption. A 10-token classification prompt and a 100K-token document analysis hit the same API endpoint but differ in input length by a factor of 10,000. Total cost also depends on output length, model, caching, and pricing. Rate-limiting by RPS either lets expensive requests through unchecked or starves cheap requests unnecessarily.
Production systems need token-based rate limiting across multiple dimensions. OpenAI documents request and token limits by usage tier. Anthropic separates input-token and output-token limits. Exact quotas and algorithms can change, so treat the provider documentation as the source of truth; the architectural point is to budget requests and tokens independently.
One application-level implementation is a multi-dimensional limit hierarchy (user → application → organization → global), with priority tiers for premium access. At the request level, reserve tokens at admission: estimate total tokens (input + max_tokens), deduct the estimate from the bucket, then refund the unused part when the request completes with actual usage. That prevents a burst of long-generation requests from exhausting capacity before they start producing output. A request with 2,000 input tokens and max_tokens = 1,000 reserves 3,000. If the answer uses 200 output tokens, actual usage is 2,200 and 800 are refunded. This is a local admission policy; provider quota algorithms can use different estimates and separate input/output budgets. If the bucket holds less than 3,000, return a 429 or queue the request.
For self-hosted deployments, the equivalent is provisioned throughput: reserving dedicated GPU capacity for target token rates. For vLLM deployments, that means configuring admission control around active decode slots and KV cache pressure rather than request count alone. As Section 5 explains, throughput and admission both need token-aware limits.
42. Failure modes to design against
LLM serving adds failure modes tied to variable sequence length, KV memory, and long-running decode work. Design and load-test the defenses before production traffic depends on them.
Out-of-Memory (OOM) is a common failure. A 70B FP16 model needs about 140 GB for weights alone, and KV cache for a single Llama 3.1 70B 128K-context sequence can add about 40 GiB under the assumptions in Section 6. The gap between “fits in memory” and “OOM under load” is smaller than it looks because a batch of long-context requests can consume more KV memory than expected. Prevention combines a measured memory reserve with quantization and paged KV allocation. In vLLM, --gpu-memory-utilization sets the fraction of GPU memory the engine may use for weights, activations, and KV cache; the remainder is the reserve. For workloads with high KV pressure, LMCache can offload KV data to CPU memory or disk; use its published results as a starting point and benchmark the local memory hierarchy.
Preemption happens when KV cache pressure forces the scheduler to evict or recompute work. The exact strategy depends on the serving version and configuration. From the user’s side, the symptom is higher end-to-end latency without an obvious application error. Watch preemption counts and correlate them with KV use, queue depth, and request lengths.
Tail latency can spike when large prefills delay decode work. Chunked prefill (Section 7) and length-aware scheduling target this interference. The Learning-to-Rank scheduler (Fu et al., 2024) and CascadeInfer papers report improvements over their baselines under their evaluated workloads, but the exact result depends on the request-length distribution and scheduler configuration.
Cascading failures can start when slow requests grow the queue, upstream clients time out, and retries add more load. Defenses include admission control, per-tenant concurrency limits, output caps, retry budgets, and gateway circuit breakers. Disaggregated prefill and decode pools may help when load tests show persistent phase interference. The figure shows the loop and the defense on each edge.
43. Monitoring LLM systems
LLM monitoring differs from API monitoring in three ways: every request has a different cost, each request has two phases with different bottlenecks, and its memory footprint depends on both input and output length. Request latency and error rate alone do not show any of these.
Goodput is the number of requests per second that meet all defined SLO thresholds, such as TTFT, TPOT, and total latency. It is a useful combined measure because raw throughput can look healthy while latency SLOs fail: a system processing 100 requests per second but missing its thresholds on 40% of them has a goodput of 60 requests per second. Optimizing for goodput keeps the performance distribution visible instead of reporting only the mean.
vLLM exposes a Prometheus endpoint at /metrics with running and waiting requests, KV cache use, generation-length distributions, and prefix-cache statistics. Metric names can change across releases, so bind dashboards to the deployed version. A typical stack uses Prometheus for metrics, Grafana for visualization, and OpenTelemetry-compatible traces across application and serving components.
Useful alert patterns include the following. Derive their thresholds from load tests rather than copying these examples unchanged:
- Preemption count spikes — the runtime is swapping or recomputing work, which adds latency without an application error.
- KV cache utilization approaching the tested preemption region — add capacity or shed load before evictions cascade.
- Queue depth persistently above the tested batch envelope — admission control should start rejecting or deprioritizing.
- TTFT rising while TPOT stays flat — this divergence points first to queuing, admission, network, or prefill pressure rather than decode throughput. Use traces and queue metrics to distinguish among them.
In vLLM, the first three alerts map to vllm:num_preemptions_total, vllm:kv_cache_usage_perc, and vllm:num_requests_waiting (vLLM metrics).
44. Cost optimization: a compounding strategy
Provider prices and input-to-output price ratios change. Pull current rates before a purchasing decision; model tier and output length can dominate the bill even before infrastructure optimizations.
OpenAI, Anthropic, and Google all price output tokens several times higher than input tokens for their flagship models. Separately, the prefill/decode split explains why input and output have different execution costs: prefill processes prompt tokens together, while ordinary decode generates tokens sequentially. This mechanism alone does not establish how a provider sets its commercial prices. Cutting unneeded output (a tight max_tokens, structured output, no restated input) usually saves more than cutting the same number of input tokens.
Several approaches can be stacked, but only after measuring which ones apply to the workload:
- Quantization from FP16 to INT4 cuts raw weight-value storage by 75%, before scales and other metadata. Whether that reduces the bill depends on kernel speed, batch size, and hardware utilization (Section 9).
- Model routing sends eligible traffic to cheaper models. Measure the router’s false-accept rate and end-to-end quality before increasing the share handled by the cheaper model (Section 36).
- Prompt caching reduces repeated-prefix work. Provider discounts and rate-limit treatment change over time, so combine measured hit rate with current terms (Section 16).
- Batch APIs can discount non-real-time work such as evaluations, synthetic-data generation, and bulk classification. Check current prices and completion windows.
- Self-hosting can win at sustained utilization, but there is no universal token-volume break-even. Include engineering, orchestration, observability, capacity slack, and on-call costs in addition to GPU rental.
Do not multiply separate optimization gains as if all requests benefit independently: quantization changes throughput, routing changes quality mix, and caching and batching apply only to eligible traffic. Build the estimate from measured traffic shares and validate it against the invoice.
45. Capacity planning and autoscaling
Capacity planning for LLM serving must account for variable request cost, long-running decode work, and sequence-dependent memory. Depending on the workload, the limiting resource may be KV memory, memory bandwidth, compute, or the interconnect.
The theoretical memory bound on concurrent requests comes from the KV-cache budget:
For capacity arithmetic, suppose the runtime exposes a 40 GiB KV budget for Llama 3.1 70B with an FP16 KV cache. Each 4K sequence uses about 1.25 GiB and each 128K sequence about 40 GiB. That budget therefore fits at most about 32 4K sequences or one 128K sequence before allocator, runtime, workload-variance, and SLO overhead. The kv_cache_bytes function in Section 6 repeats this calculation for another model or budget. This is why GPU selection and KV cache optimization directly drive the capacity plan.
The capacity formula for fleet sizing:
Convert both rates to the same time unit before dividing. Use per-GPU throughput measured at the target SLO, not peak throughput. A multiplier of 1.3 provisions 30% more throughput than expected demand, which leaves about 23% of the provisioned capacity unused at that demand. Round up to complete serving replicas; a TP/PP replica needs its full GPU group. Per-GPU rates are useful only for a fixed, measured replica topology. Choose the multiplier from measured burstiness, failures, and recovery time. Peak token throughput and SLO-compliant throughput can differ sharply as concurrency rises. Benchmark with the real prompt and output-length distribution at the required TTFT and TPOT thresholds rather than using a theoretical maximum.
GPU utilization is insufficient as the only autoscaling signal because it can stay high during both healthy processing and overload. Combine it with queue depth, KV cache utilization, and goodput degradation. Tune thresholds from load tests; values such as 80% KV utilization are starting points, not universal limits. These metrics are introduced in Section 43.
Scale-to-zero can fit development and staging environments with long idle periods. Serverless inference platforms and Kubernetes-based autoscalers such as KEDA can remove idle capacity, but the savings and cold-start time depend on model size, image and weight caching, and infrastructure. Measure startup time before using the same policy for latency-sensitive production traffic.
How the inference concepts connect
Parts I to III connect memory capacity with serving performance. KV size per sequence (Section 6) gives a raw bound on resident sequences. Larger decode batches can improve weight reuse and arithmetic intensity (Section 1), but attention traffic, scheduling, and communication also affect TPOT and throughput. GQA and lower-precision KV storage reduce cache payload; PagedAttention reduces allocation waste. With the stated Llama 3.1 70B layout, an FP16 KV cache, and a 40 GiB budget, the raw bound is 32 sequences of 4K tokens or one of 128K, before runtime overhead and latency constraints. Admission control can queue or reject work before that bound is reached. Under KV pressure, the runtime may preempt requests; unchecked allocations can cause OOM (Section 42).
Routing, caching, quantization, and hardware choice compound only when each is evaluated against the same quality and latency target. Pick one symptom from the table at the top, establish that baseline, and make the next change easy to reverse.
Further reading
Related deep-dives from this blog, organized by topic:
- LLM Fine-Tuning Guide — when to fine-tune vs. RAG vs. prompt engineering
- Open-Source LLM Variants and File Formats — matching model variants and quantized formats to hardware
- LoRAX Serving Guide — serving thousands of LoRA adapters in production
- Scaling Large Language Models — multi-GPU and multi-node strategies
- Local LLMs on macOS — hands-on setup with llama.cpp and Ollama
- AI Agent Reasoning Loops in 2026 — deep dive into ReAct, ReWOO, and planner-executor loops
- AI Agent Memory Architecture in 2026 — checkpoints, vector stores, and document memory for stateful agents
References
Organized by topic area.
Inference and attention
- FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness - Dao et al., NeurIPS 2022
- FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning - Dao, 2023
- FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision - Shah et al., NeurIPS 2024
- Flash-Decoding for long-context inference - Dao et al., 2023
- Efficient Memory Management for Large Language Model Serving with PagedAttention - Kwon et al., SOSP 2023
- Orca: A Distributed Serving System for Transformer-Based Generative Models - Yu et al., OSDI 2022
- GQA: Training Generalized Multi-Query Attention - Ainslie et al., 2023
- Triton: an intermediate language and compiler for neural network computations - Tillet et al., MAPL 2019
- FlashNorm: Fast Normalization for LLMs - 2024
- Deep Kernel Fusion for Transformers - DeepFusionKernel, 2026
Speculative decoding
- Accelerating Large Language Model Decoding with Speculative Sampling - Chen et al., 2023
- EAGLE-3: Scaling up Inference Acceleration of Large Language Models - Li et al., NeurIPS 2025
- Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads - ICML 2024
Quantization
- AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration - MLSys 2024 Best Paper
- GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers - Frantar et al., ICLR 2023
- Marlin: Mixed-Precision (FP16xINT4) LLM Inference Kernel - Frantar et al., 2024
Training and fine-tuning
- LoRA: Low-Rank Adaptation of Large Language Models - Hu et al., ICLR 2022
- QLoRA: Efficient Finetuning of Quantized LLMs - Dettmers et al., NeurIPS 2023
- ZeRO: Memory Optimizations Toward Training Trillion Parameter Models - Rajbhandari et al., SC20
- ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning - Rajbhandari et al., 2021
- Self-Instruct: Aligning Language Models with Self-Generated Instructions - Wang et al., ACL 2023
- WizardLM: Empowering Large Language Models to Follow Complex Instructions - Xu et al., ICLR 2024
- Phi-4 Technical Report - Microsoft, 2024
- Training Deep Nets with Sublinear Memory Cost - Chen et al., 2016 (gradient checkpointing)
- AI models collapse when trained on recursively generated data - Shumailov et al., Nature 2024
Alignment
- Direct Preference Optimization: Your Language Model is Secretly a Reward Model - Rafailov et al., NeurIPS 2023
- DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models - Introduced GRPO
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning - DeepSeek, 2025
Scaling and architecture
- The Llama 3 Herd of Models - Meta, 2024
- LLaMA: Open and Efficient Foundation Language Models - Touvron et al. (Meta), 2023
- Llama 2: Open Foundation and Fine-Tuned Chat Models - Touvron et al. (Meta), 2023
- Qwen3 Technical Report - Qwen Team (Alibaba), 2025
- Training Compute-Optimal Large Language Models - Hoffmann et al. (Chinchilla), NeurIPS 2022
- RoFormer: Enhanced Transformer with Rotary Position Embedding - Su et al., 2021
- YaRN: Efficient Context Window Extension of Large Language Models - Peng et al., ICLR 2024
- SGLang: Efficient Execution of Structured Language Model Programs - Zheng et al., NeurIPS 2024
- Mixtral of Experts - Jiang et al. (Mistral AI), 2024
Embeddings
- Matryoshka Representation Learning - Kusupati et al., NeurIPS 2022
- pplx-embed-v1: Diffusion-Pretrained Dense and Contextual Embeddings - Perplexity AI, 2026
Agent architectures
- ReAct: Synergizing Reasoning and Acting in Language Models - Yao et al., ICLR 2023
- ReWOO: Decoupling Reasoning from Observations for Efficient Augmented Language Models - Xu et al., 2023
Prompting
- Large Language Models are Zero-Shot Reasoners - Kojima et al., NeurIPS 2022
- Self-Consistency Improves Chain of Thought Reasoning in Language Models - Wang et al., ICLR 2023
Routing
- RouteLLM: Learning to Route LLMs with Preference Data - Ong et al., ICLR 2025
Benchmarks
- MLPerf Inference v5.0 Results - MLCommons, April 2025
Serving architectures
- Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve - Agrawal et al., OSDI 2024 (Chunked prefill)
- Splitwise: Efficient Generative LLM Inference Using Phase Splitting - Patel et al., ISCA 2024 (Disaggregated Serving)
- DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving - Zhong et al., OSDI 2024 (Disaggregated Serving)
Serving frameworks
- vLLM - PagedAttention-based serving engine
- SGLang - RadixAttention and structured generation
- TensorRT-LLM - NVIDIA optimized inference
- llama.cpp - Portable C/C++ inference
- DeepSpeed - Microsoft distributed training library
- Ollama - Local LLM runner
Operations
- Efficient LLM Scheduling by Learning to Rank - Fu et al., NeurIPS 2024 (vLLM-LTR)
- CascadeInfer: Length-Aware Scheduling of LLM Serving with Low Latency and Load Balancing - Yuan et al., 2025
- Goodput metric as measure of ML productivity - Google Cloud, 2024
- vLLM Optimization and Tuning - vLLM Documentation
- vLLM Metrics - vLLM Documentation
- LMCache: KV Cache Management for LLM Serving - KV cache offloading
- OpenAI Rate Limits - OpenAI API Documentation
- Anthropic Rate Limits - Anthropic API Documentation